Updated on
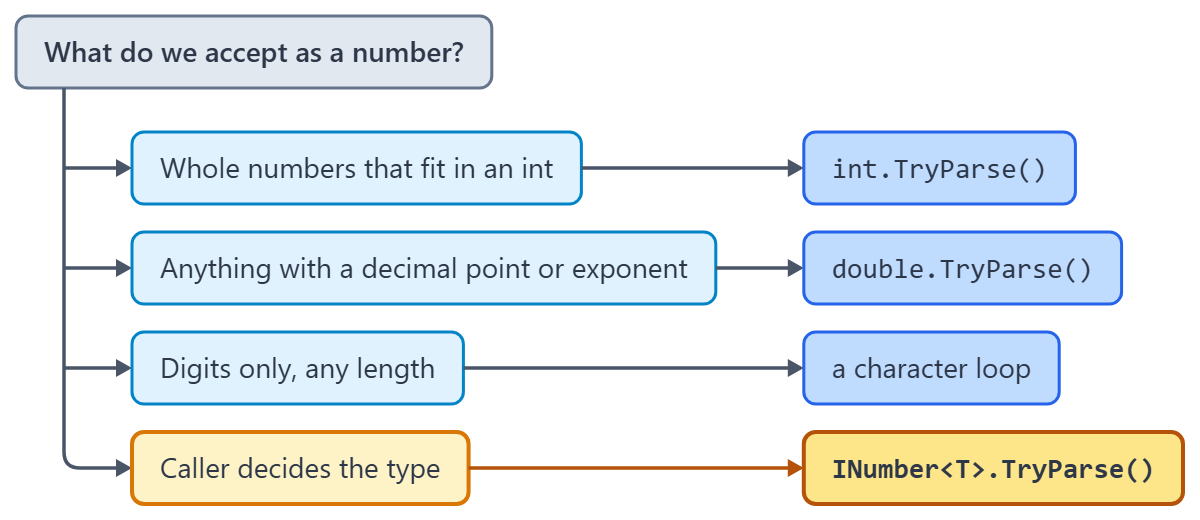
There is no single “is this string a number” check in C#, because “number” is not one type. int.TryParse() answers one question, double.TryParse() answers a wider one, and a character loop asks a third question: is every character a digit?
So the check we want is decided by the values we are willing to accept: whole numbers only, anything with a decimal point, or any digit sequence of any length. The sections below show what each option says yes and no to, and a benchmark near the end compares their speed.
Why Does the Answer Depend on the Numeric Type?
C# has no single check for “is this string a number”, because “number” is not one type. Every parsing check commits to a target type first, and the answer follows from that choice.
int.TryParse() asks a narrow question: does this text fit in a 32 bit signed integer? It returns true for "1234", and false for "1.23", which carries a decimal point, and false for "9999999999", which is a whole number but larger than int.MaxValue of 2,147,483,647.
double.TryParse() widens the question to any floating point value, so both of those return true.
The second argument is where the parsed value lands. When we want only the yes or no answer, we discard it with out _.
So the first decision is which values we are willing to call numbers: whole numbers only, anything with a decimal point, or any digit sequence at all. The method follows from that.
Before we start coding, let’s create a console application using the Visual Studio wizard or the dotnet new console command. For the parsing pattern in general, see TryParse and Parse in C#.
We write each check as a public static method of a StringIsANumberChecker class in its own file and call it from Program.cs. The snippets also use three namespaces that the console template does not import, so we add global using System.Globalization;, global using System.Numerics; and global using System.Text.RegularExpressions; at the top of Program.cs.
The simplest check is the int.TryParse() method:
int.TryParse(stringValue, out _);
This method receives a string value as a parameter and tries to parse it into an int. In case the parse was successful, it returns true, otherwise false.
Note that, the TryParse() method has a second argument. That is an out argument that means that if the parse is successful, the TryParse() method will assign the parsed value to this argument. In this case, we use the discard key (_) to indicate that we don’t need this value. When we do need it, see our article on converting a string to an int.
Let’s run this method against an array of string values:
var values = new string[] { "1234","ABC-789", "1.23", "9999999999" };
The first value represents an integer number which our method must parse as a number. The second value is an alphanumeric string, so we expect the int.TryParse() method to return false.
Now, let’s analyze the result:
"1234"       // true
"ABC-789"    // false
"1.23"       // false
"9999999999" // false
As we can see, the values 1.23 and 9999999999 are numbers, but they evaluate as false. That happens because we are using the int.TryParse() method which checks only for the int data type.
Note that 9999999999 is, mathematically, an integer number. However, it isn’t an int because it exceeds the maximum value of the int (Int32) data type, which is 2,147,483,647. Thus, the int.TryParse() method evaluates it as false.
The same pattern exists on other .NET types: long.TryParse(), double.TryParse(), decimal.TryParse(), bool.TryParse(), DateTime.TryParse() and more.
That said, let’s switch the int.TryParse() to double.TryParse() to validate if a string is a valid number:
double.TryParse(stringValue, NumberStyles.Float | NumberStyles.AllowThousands,
    CultureInfo.InvariantCulture, out _);
Besides the string, we pass a number style and a culture. Together they fix the rules for decimal points and thousands separators, so the answer does not depend on the regional settings of the machine that runs the code. We come back to that in the culture section below.
Now, let’s run the method against the same array of strings:
"1234"       // true
"ABC-789"    // false
"1.23"       // true
"9999999999" // true
Now, the values 1.23 and 9999999999 both evaluate as true. That’s because the double datatype handles both mathematical integers and non-integer numeric values.
Is There an IsNumeric Function in C#?
No. C# has no IsNumeric() function. The name comes from Visual Basic, where IsNumeric() is a built in function, and developers moving to C# look for it by name and do not find one.
The nearest equivalent is a single line we write ourselves:
public static bool IsNumeric(string stringValue) =>
    double.TryParse(stringValue, NumberStyles.Float | NumberStyles.AllowThousands,
        CultureInfo.InvariantCulture, out _);
Any string that double.TryParse() accepts is a number by the loosest reasonable definition: whole numbers, decimals, negatives, and values far larger than an int can hold. That one line is what most people mean when they search for IsNumeric.
That makes it too loose for validating input. It accepts "NaN", "1e3" and a thousands separator, so "1,234" passes. To check that a form field holds a plain number, we need a stricter check, and the regular expression and character loop sections below build several.
Visual Basic’s own IsNumeric() is still callable from C# through Microsoft.VisualBasic.Information, and it follows different rules from double.TryParse().
The Information.IsNumeric documentation says that it “returns True if Expression is a string that contains a valid hexadecimal or octal number”, so it accepts "&H1F", which double.TryParse() rejects.
Does the Current Culture Change the Answer?
Yes, which is why the double.TryParse() examples above pass CultureInfo.InvariantCulture. double.TryParse() reads the current thread’s culture unless we tell it otherwise, and cultures disagree about what a decimal point is.
On a machine running en-US, parsing "1.23" succeeds and produces 1.23. On a machine running de-DE, the same call still succeeds, but it produces 123, because German reads the dot as a thousands separator. "1.234" becomes 1234 there. The call does not throw or warn, and the check still answers “yes, that is a number”. Here is the German case in code:
var de = new CultureInfo("de-DE");

double.TryParse("1.23", NumberStyles.Float | NumberStyles.AllowThousands, de, out var value);
// value is 123, not 1.23
For text that arrived from a file, an API or a database, the machine’s culture is irrelevant and CultureInfo.InvariantCulture is the correct choice. For text a person typed into a form, that person’s culture is the correct one.
The overloads that take a style and a format provider let us choose the culture explicitly, while the two-argument overload uses whatever culture the thread runs under.
The culture also decides which words count as numbers. CultureInfo.InvariantCulture spells infinity as "Infinity", so our double.TryParse() call accepts "Infinity" and "-Infinity", while en-US uses the ∞ symbol and rejects the word. The NumberStyles flags themselves are covered in TryParse and Parse in C#.
How Do We Check a Numeric String With a Regular Expression?
Regular expressions can be extremely helpful when checking patterns within a string.
We will use this tool to check whether a given string represents a number or not:
public static bool UsingRegex(string stringValue)
{
    const string pattern = @"^-?[0-9]+(?:\.[0-9]+)?$";
    var regex = new Regex(pattern);

    return regex.IsMatch(stringValue);
}
Here, we have a method that receives a string (stringValue) as input and returns true if this input represents a number, and false otherwise.
To perform this validation, we create a simple regular expression pattern (^-?[0-9]+(?:\.[0-9]+)?$). First, this pattern checks if the string starts with an optional minus sign (-?) indicating a negative value.
The second step consists of validating if the string has one or more digits ([0-9]+).
Finally, the regular expression checks if the string has an optional decimal point followed by one or more digits ((?:\.[0-9]+)?$).
Now that our pattern is ready, we instantiate a new regex object that takes this pattern as a parameter. Next, we use the IsMatch() method to validate the string by passing it as an argument and returning the result.
In this case, we separate decimal points with a dot (.), however, if we want to use commas (,), we could simply modify the regex pattern expression to adapt to this change.
Also, if we want to validate only integer numbers, we can modify the regular expression to ^-?[0-9]+$.
Source-Generated Regex
Source-generated Regex is the same pattern as above, but the matching code is generated at build time instead of being interpreted at run time, which makes it faster to execute.
We can learn more about the differences here. For a closer look at the generator itself, see our article on source-generated regular expressions.
Let’s declare the same regular expression, but in the source-generated form:
public partial class StringIsANumberChecker
{
    [GeneratedRegex(@"^-?[0-9]+(?:\.[0-9]+)?$")]
    private static partial Regex IsDigitRegex();

    public static bool UsingCompiledRegex(string stringValue)
    {
        return IsDigitRegex().IsMatch(stringValue);
    }
}
We create a static partial method that returns a regex instance and annotate it with GeneratedRegexAttribute. The compiler will handle the rest and generate the method body for us during compilation. Because the generator writes that body into another part of the class, the class itself must be declared partial too. Then we can use the regex instance returned by the method in the same way as in the previous example.
This regular expression syntax is only available since .NET 7. If we were to target an older version, we should use the RegexOptions enum’s Compiled member to achieve a similar result:
new Regex(@"^-?[0-9]+(?:\.[0-9]+)?$", RegexOptions.Compiled)
Note that \d in .NET matches any Unicode decimal digit, including Arabic-Indic and Devanagari digits, while [0-9] matches only the ASCII ten.
RegexOptions.Compiled will compile the regular expression, just like when we use the GeneratedRegexAttribute. However, the compilation for each happens at different times. The regular expression is compiled at build time when we use the GeneratedRegexAttribute, while the regular expression gets compiled at runtime when we use the RegexOptions.Compiled flag.
Using GeneratedRegexAttribute over RegexOptions.Compiled is preferred because it doesn’t introduce the startup cost that RegexOptions.Compiled does. Moreover, it generates C# code that is later translated into IL, instead of translating directly to IL, so it’s easy to view and debug.
How Do We Check That Every Character Is a Digit?
In this approach, we are going to use the All() extension method to check if every character in the string is a number in conjunction with the char.IsAsciiDigit() method.
We utilize the IsAsciiDigit() method instead of solely relying on the IsDigit() method because IsDigit() incorporates Unicode checks, allowing it to match numbers written in various languages containing non-ASCII characters, such as Arabic or Thai. However, in this article, our focus is on English characters.
Let’s check this approach:
public static bool UsingCharIsDigit(string stringValue)
{
    return !string.IsNullOrEmpty(stringValue) && stringValue.All(char.IsAsciiDigit);
}
Here, we use the All() extension method that is responsible for iterating over each character in the input string and verifying if it represents a number. If every character is a number, we return true. Otherwise false.
The string.IsNullOrEmpty() check comes first because All() returns true for an empty sequence, so without it an empty string would count as a number.
Note that, as with the int.TryParse() method, this approach works for integer numbers without a sign as well. However, different from the int.TryParse() method, this approach can validate numbers that exceed the int data type max value.
Is a Foreach Loop Faster Than All()?
The previous method has the advantage of being very readable. However, LINQ introduces some overhead because All() calls a delegate for every character, which can result in slower performance.
Let’s fix that now by introducing a foreach loop instead of the All() method:
public static bool UsingCharIsDigitWithForeach(string stringValue)
{
    if (string.IsNullOrEmpty(stringValue))
        return false;

    foreach (var c in stringValue)
    {
        if (!char.IsAsciiDigit(c))
            return false;
    }

    return true;
}
We eliminate the delegate calls by using a foreach loop. We use an early return strategy by checking if the character is not a digit, and then we instantly return false. This way, just like All(), the algorithm stops at the first non-digit when encountering a non-numeric-only string, so it doesn’t have to loop through the entire string.
The same empty-string check sits at the top, because a foreach over an empty string never runs its body and would fall through to return true.
Now let’s try another approach without using the IsAsciiDigit() method.
Can We Compare Character Values Directly?
We can go one step further and compare the character’s value directly, which is what char.IsAsciiDigit() does internally:
public static bool UsingCharIsBetween09(string stringValue)
{
    if (string.IsNullOrEmpty(stringValue))
        return false;

    foreach (var c in stringValue)
    {
        if (c is < '0' or > '9')
            return false;
    }

    return true;
}
We simply replace the IsAsciiDigit() method call with a pattern. It checks whether the current character is not between 0 and 9, then early returns false. If all the characters were between 0 and 9, then our method returns true.
What Is the Fastest Way to Check If a String Is a Number?
After learning the different ways to verify if a string is a number, let’s analyze a benchmark result to determine which is the fastest way to check if a string is a number. Every method runs against two inputs, "123456789", which is all digits, and "a12345678", which fails on its first character:
BenchmarkDotNet v0.15.8, Windows 10 (10.0.19045.6466/22H2/2022Update)
AMD Ryzen 5 3600 3.60GHz, 1 CPU, 12 logical and 6 physical cores
.NET SDK 10.0.302
  [Host]     : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3
  DefaultJob : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3

| Method                      | Value     | Mean          | Error      | StdDev     | Gen0   | Gen1   | Allocated |
|---------------------------- |---------- |--------------:|-----------:|-----------:|-------:|-------:|----------:|
| UsingCharIsDigitWithForeach | a12345678 |     0.2523 ns |  0.0069 ns |  0.0058 ns |      - |      - |         - |
| UsingCharIsBetween09        | a12345678 |     0.2607 ns |  0.0153 ns |  0.0119 ns |      - |      - |         - |
| UsingCharIsDigit            | a12345678 |     2.5069 ns |  0.0200 ns |  0.0177 ns |      - |      - |         - |
| UsingCharIsBetween09        | 123456789 |     3.2124 ns |  0.0822 ns |  0.0769 ns |      - |      - |         - |
| UsingCharIsDigitWithForeach | 123456789 |     3.3910 ns |  0.0972 ns |  0.1158 ns |      - |      - |         - |
| IntTryParse                 | a12345678 |     5.8315 ns |  0.0414 ns |  0.0367 ns |      - |      - |         - |
| IntTryParse                 | 123456789 |    14.8640 ns |  0.3049 ns |  0.2852 ns |      - |      - |         - |
| UsingCompiledRegex          | a12345678 |    18.1585 ns |  0.2066 ns |  0.1831 ns |      - |      - |         - |
| UsingCharIsDigit            | 123456789 |    21.7109 ns |  0.1812 ns |  0.1695 ns |      - |      - |         - |
| UsingCompiledRegex          | 123456789 |    26.2210 ns |  0.2220 ns |  0.2076 ns |      - |      - |         - |
| DoubleTryParse              | a12345678 |    35.3407 ns |  0.3949 ns |  0.3694 ns |      - |      - |         - |
| DoubleTryParse              | 123456789 |    50.3004 ns |  0.2197 ns |  0.2055 ns |      - |      - |         - |
| UsingRegex                  | a12345678 | 1,787.0632 ns | 19.8846 ns | 16.6045 ns | 0.4444 | 0.0038 |    3720 B |
| UsingRegex                  | 123456789 | 1,905.1397 ns | 38.0888 ns | 99.6718 ns | 0.4444 | 0.0038 |    3720 B |
As we can see in this benchmark result, the UsingRegex approach is significantly slower than any other approach. Despite its slower performance, the regex approach is more flexible, allowing us to validate integers and non-integer values.
We can use the UsingCharIsDigit approach only if we deal with mathematical integer numbers without a sign.
Although we don’t have much flexibility when we are using the IntTryParse or DoubleTryParse approaches, they still perform this job considerably faster than the UsingRegex approach.
If we need flexibility and don’t mind the drawbacks of source-generated Regex, then it’s the overall winner. Being able to check strings for any specified pattern in less time than the DoubleTryParse approach is a fantastic result.
However, if our goal is only to check strings for characters that are integers between 0 and 9, the fastest approaches are the two foreach loops, UsingCharIsBetween09 and UsingCharIsDigitWithForeach, which finish within 0.2 nanoseconds of each other on both inputs.
On the second input, the three character loops stop at the a and drop below 3 nanoseconds, and IntTryParse, UsingCompiledRegex and DoubleTryParse also finish sooner when the first character is not a digit.
We can also combine multiple approaches to achieve the same result. For example, if we require high performance, we can combine the IntTryParse and DoubleTryParse approaches to handle integer and non-integer values. These two approaches combined are still more efficient than the UsingRegex approach.
Besides speed, the methods differ in which strings they accept:
| Method | "1234" | "1.23" | "9999999999" | "-42" | "1,234" | "NaN" | "١٢٣" |
|---|---|---|---|---|---|---|---|
IntTryParse | yes | no | no | yes | no | no | no |
DoubleTryParse | yes | yes | yes | yes | yes | yes | no |
UsingRegex / UsingCompiledRegex | yes | yes | yes | yes | no | no | no |
UsingCharIsDigit | yes | no | yes | no | no | no | no |
UsingCharIsDigitWithForeach | yes | no | yes | no | no | no | no |
UsingCharIsBetween09 | yes | no | yes | no | no | no | no |
The three character loops give the same answer for every input in the table, so the choice between them comes down to readability and the speed measured above. Only DoubleTryParse accepts "1,234" and "NaN", and none of the seven methods accepts an empty string.
Can One Method Cover Every Numeric Type?
Yes. Since .NET 7, the numeric types implement INumber<T>, and that interface carries a static TryParse(). One generic method answers the question for int, long, double, decimal or any other numeric type the caller names:
public static bool IsNumber<T>(string stringValue) where T : INumber<T> =>
    T.TryParse(stringValue, CultureInfo.InvariantCulture, out _);
Calling IsNumber<int>("1.23") returns false and IsNumber<double>("1.23") returns true. That is the same type decision as the first section, except the caller now makes it at the call site instead of us making it in the method body.
The same parsing methods also accept a ReadOnlySpan<char> wherever they accept a string. That matters when the text we are checking is a slice of a larger buffer: slicing a span allocates nothing, while Substring() allocates a new string.
Neither of these appears in the benchmark above. Generic math changes what the check can express and spans change where it can read from, while the benchmark measures how fast each check runs.
For what a span is and when it pays, see How to Use Span in C# to Improve Application Performance.
Conclusion
In this article, we have learned different ways to verify if a string can be parsed into a number.
We have seen the limitations of the IntTryParse and UsingCharIsDigit approach, as well as the flexibility that using Regex, gives us when we need to change how we verify the string. However, it’s less efficient than all other approaches we have discussed. On the other hand, we discussed how to make Regexes execute faster by generating them at build time.
Furthermore, we have learned how to enhance code efficiency at the expense of lines of code by using foreach loops. Additionally, we have discovered that the DoubleTryParse approach can efficiently parse large numbers with or without decimal points.
When the number sits inside a longer string, our article on finding and extracting a number from a string picks up where this one stops.
Ultimately, it is up to us to decide which fits our algorithm and use case better.
Tested with .NET 10.0.10 and BenchmarkDotNet 0.15.8.
How much faster would regex be if it was precompiled regex?
Hi Michael. We really didn’t try that, so I am not sure how much faster it would be. But of course, if you want and have some free time, you can always download our source code (at the top of the article) and test it.