Updated on
Removing the last character of a string in C# is a single expression: inputString[..^1]. The range operator on a string compiles to Substring(0, Length - 1), so it is the call the framework has always had, with less to type and one fewer place to get the arithmetic wrong.
Nothing here edits a string in place, because strings are immutable. Every technique builds a new string one character shorter, and the only way to skip that allocation is to stop asking for a string at all: inputString.AsSpan()[..^1] returns a view over the characters we already have and copies nothing.
StringBuilder is the exception. It is mutable, so stringBuilder.Remove(stringBuilder.Length - 1, 1) shortens the buffer in place and allocates nothing until we call ToString().
How Do We Remove the Last Character With the Range Operator?
inputString[..^1] is the shortest way to write it. The range operator takes everything from the start up to one character before the end, and the compiler turns that into inputString.Substring(0, inputString.Length - 1), so the two forms are the same call.
Substring() is the explicit version of the same thing. Its arguments are a start index and a length, so Substring(0, inputString.Length - 1) starts at the beginning and takes one character fewer than we have.
Neither of the two copies less than the other. Both of them allocate a new string of one character fewer than the original, because the original string cannot be changed once it exists.
The range form is the one to prefer in new code. It is a single expression, it puts the intent where the eye lands, and it extends to any number of characters by changing one digit.
Substring() still earns its place in a codebase that predates the range operator, and in code where an explicit start index makes the intent clearer to the next reader.
Both operators arrived in C# 8.0, where Microsoft’s C# version history lists them as “Indices and ranges” and notes that they “require new types in the .NET Core 3.0 libraries”. Here is the range form on its own:
return inputString[..^1];
The range ..^1 means everything from the start up to one place before the end. The index operator ^ counts backwards from the end of the string, so ^1 is the position of the last character and the range stops just in front of it.
Here is the same operation written the explicit way:
return inputString.Substring(0, inputString.Length - 1);
Our example utilizes an overload of the String.Substring() method by passing two integer arguments (the index to start from and the length) to extract a substring from the first index to the second-last character of the inputString.
How Do We Remove the Last Character Without Allocating?
Sometimes, we may need to manipulate strings with performance considerations in mind. That’s where the ReadOnlySpan<T> struct comes in handy, providing memory and type-safe representations of our string object. The difference between the two shapes below is the whole reason this section exists:
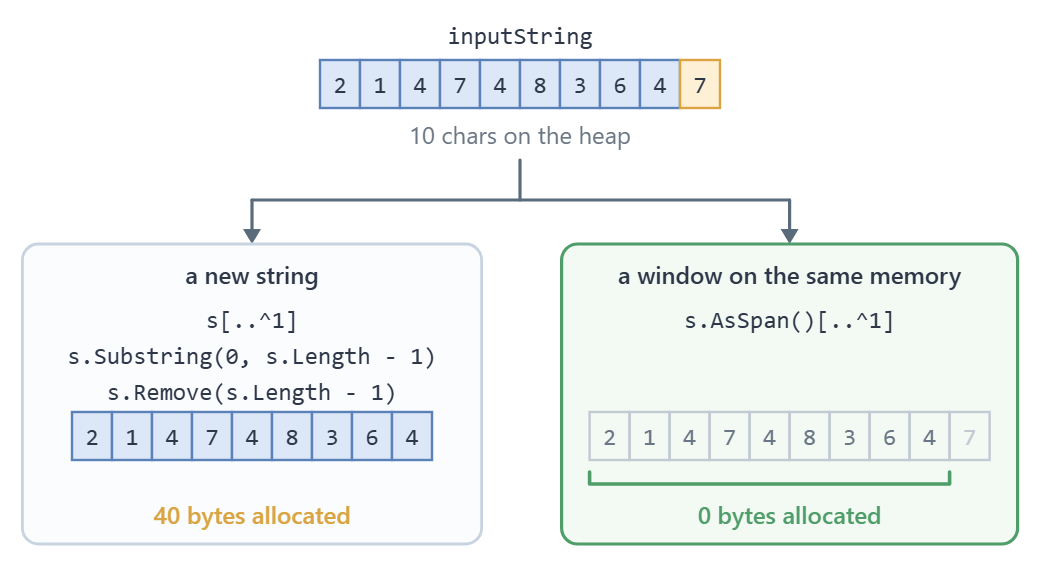
Converting the span back into a string undoes the saving, so this first form is here only to show the shape. The version worth writing is the one below it.
Here’s an example of how we can achieve our goal using the ReadOnlySpan<char>:
var inputSpan = inputString.AsSpan()[..^1];

return new string(inputSpan);
Our example uses the ReadOnlySpan<char>.Slice() method to create a slice from our string’s first character to the second-last character. (Note that here we are exercising the Range operator, which will be lowered to call Slice() as seen here). Finally, we return the string representation of the current ReadOnlySpan<char> instance. If the mechanics of that call are new, converting a string to a span covers them in full.
We can greatly improve the overall performance of our application by continuing to operate on the ReadOnlySpan<char> slice rather than creating a new string from it. This will be the fastest way to remove the last character from the string as the ReadOnlySpan<char> provides a view over the original string data without any additional allocation or copying:
return inputString.AsSpan()[..^1];
Traditional string manipulation methods often create new string object instances, which leads to more memory utilization and garbage collection overhead. This form creates none: nothing is copied, and the slice keeps pointing at the characters the original string already holds. Our article on using Span to improve application performance takes the same idea through the rest of the framework.
What Does String.Remove() Actually Remove?
As the name implies, the String.Remove() method returns a new string object where characters from the current instance are deleted starting from a specific position to the end:
return inputString.Remove(inputString.Length - 1);
Here we invoke String.Remove() with inputString.Length - 1, the index of the last character. The method deletes from that index to the end of the string, so passing the last character’s index removes exactly one character and returns a new string instance.
How Do We Remove the Last Character From a StringBuilder?
The StringBuilder class is mutable, so removing its last character changes the buffer we already have instead of building a new string.
The call stringBuilder.Remove(stringBuilder.Length - 1, 1) is the direct one. It deletes one character at the last index and returns the same builder, so it chains straight onto a sequence of appends.
The statement stringBuilder.Length-- does the same job with less work. Assigning a smaller value to the length is a resize: the characters past the new end simply stop counting.
Both of them throw an ArgumentOutOfRangeException on an empty builder, so anything appending inside a loop needs a length guard first.
Prefer the first when someone else will read the code. The length setter also grows a builder, padding it with null characters, so a bare decrement says nothing about intent.
The usual reason to want any of this is a trailing separator. Appending an item and a comma in a loop leaves two characters to drop, and shortening the length by two drops them before we call ToString().
Here is the direct call, wrapped around a builder we have just filled:
var stringBuilder = new StringBuilder(inputString);
stringBuilder.Remove(stringBuilder.Length - 1, 1);

return stringBuilder.ToString();
Besides using the String.Remove() method, we can use the StringBuilder class to remove the last character of a string in C#. Unlike the string class, StringBuilder provides a mutable sequence of characters, allowing for more flexible and memory-efficient modifications of its contents.
The cheaper form adjusts the length directly:
var stringBuilder = new StringBuilder(inputString);
--stringBuilder.Length;

return stringBuilder.ToString();
Here, we subtract 1 from the StringBuilder.Length property to remove the last character. Since StringBuilder is mutable, the Length property can be adjusted to shrink our “string”. After our modifications, we invoke the stringBuilder.ToString() method to return the final string representation.
When the trailing separator is the only reason we reached for a builder, there may be no separator to drop at all: the String.Join() method puts the separator between the items instead of after each one, and the problem never arises.
Can We Remove the Last Character With LINQ?
LINQ can do it too, and it is the slowest option on this page by an order of magnitude:
return new string(inputString.Take(inputString.Length - 1).ToArray());
Our example uses the Enumerable.Take() method, one of the basic concepts of LINQ, to return a range of elements up to the second-last character of the string.
It does have one property none of the others has: Take(-1) yields nothing rather than throwing, so this is the only technique here that returns an empty string instead of an exception when the input is empty.
How Do We Remove the Last N Characters of a String?
The same expressions take a count instead of a one. The expression inputString[..^n] removes the last n characters, inputString.Remove(inputString.Length - n) and inputString.Substring(0, inputString.Length - n) do it with the older methods, and inputString.AsSpan()[..^n] does it without allocating.
The expression inputString[1..^1] drops the first and the last character together, which is the shape most quoted or bracketed values arrive in.
The arithmetic is where this goes wrong. All of these throw an ArgumentOutOfRangeException when the count is larger than the string, so a count that comes from configuration or from user input needs checking before it reaches the slice.
The Math.Min() method handles that in one expression: inputString[..^Math.Min(n, inputString.Length)] returns an empty string rather than throwing when the count overshoots the end.
None of this is a search and remove. Dropping a known suffix is a different operation, and so is TrimEnd(), which strips every trailing occurrence of a character rather than exactly one.
Taking from the other end is the mirror image of this work, and the fastest way to get the first N characters of a string covers it with the same expressions turned around.
What Can Go Wrong When We Remove the Last Character?
Three things can, and the first two of them are silent.
An empty string throws. The Substring() method, Remove(), the range operator, the span form and both of the StringBuilder forms all raise an ArgumentOutOfRangeException on a zero-length input, so anything reading from a file, a form or a database needs a length check first.
A single char is not always a whole character. The text "Hi 👋" has a length of five, because the emoji occupies two char values, so the range form leaves the first half of a surrogate pair behind and the result is no longer valid text.
Accented letters behave the same way. The word café written with a combining acute accent has a length of five, and removing the last char removes the accent and leaves the bare letter sitting there.
When the input can hold either of those, walk the text elements instead. The StringInfo.GetTextElementEnumerator() method gives us the index where the last one starts, and slicing there removes a whole character as a reader understands it.
Here is that walk as a method:
public static string RemoveLastTextElement(string input)
{
    if (input.Length == 0)
        return input;

    var enumerator = StringInfo.GetTextElementEnumerator(input);
    var lastStart = 0;

    while (enumerator.MoveNext())
        lastStart = enumerator.ElementIndex;

    return input[..lastStart];
}
We walk every text element in the string, keeping the index where the last one begins, and then slice up to it. On an empty input the method returns the input unchanged rather than throwing.
Windows line endings land in the same trap. The string "line\r\n" has a length of six, and taking one character off it leaves a bare carriage return where a complete line ending used to be. Removing line breaks from a string is its own operation, and the text-element walk above removes the pair together.
Which Way to Remove the Last Character Is Fastest in C#?
Keeping the result as a ReadOnlySpan<char> wins, not narrowly. It copies nothing, so it allocates nothing, and its cost does not grow with the length of the input.
Every technique that hands back a string allocates. The range operator, Substring() and Remove() land within two nanoseconds of each other and allocate the same 40 bytes for a ten-character input, which is what three spellings of one copy should look like.
Converting a span back into a string buys nothing. It does the slice and then the copy, so it measures level with the slowest of those three rather than ahead of them.
The StringBuilder forms cost three to four times as much and allocate 144 bytes against 40, because each builds a buffer and then copies out of it again. That is the price of mutability, worth paying only when we were already building with one.
LINQ comes last, by the best part of an order of magnitude. It fills an array and then copies it into a string.
These numbers come from BenchmarkDotNet, and our introduction to benchmarking covers setting the tool up. Here is the output of the run:
BenchmarkDotNet v0.15.8, Windows 10 (10.0.19045.6466/22H2/2022Update)
AMD Ryzen 5 3600 3.60GHz, 1 CPU, 12 logical and 6 physical cores
.NET SDK 10.0.302
  [Host]     : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3
  DefaultJob : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3

| Method                                 | inputString | Mean       | Rank | Gen0   | Allocated |
|--------------------------------------- |------------ |-----------:|-----:|-------:|----------:|
| RemoveLastCharAsSpan                   | 2147483647  |  0.8660 ns |    1 |      - |         - |
| RemoveLastCharUsingRange               | 2147483647  |  8.8840 ns |    2 | 0.0048 |      40 B |
| RemoveLastCharUsingSubstring           | 2147483647  |  9.1210 ns |    2 | 0.0048 |      40 B |
| RemoveLastCharUsingRemove              | 2147483647  | 10.5946 ns |    3 | 0.0048 |      40 B |
| RemoveLastCharUsingSpan                | 2147483647  | 10.7888 ns |    3 | 0.0048 |      40 B |
| RemoveLastCharUsingStringBuilderLength | 2147483647  | 30.4818 ns |    4 | 0.0172 |     144 B |
| RemoveLastCharUsingStringBuilderRemove | 2147483647  | 37.4256 ns |    5 | 0.0172 |     144 B |
| RemoveLastCharUsingLinq                | 2147483647  | 78.8202 ns |    6 | 0.0210 |     176 B |
As we mentioned earlier and now see from the benchmark, converting our string to a ReadOnlySpan<char> and then continuing to use the span without converting to a new string, is the most performant option. It requires no allocation, and the allocation column is the part of the claim worth reading: a single-digit nanosecond figure sits at the edge of what a benchmark can resolve, but zero bytes copied is not a measurement error.
If we need to continue our work using a new string object, the range operator is the one to write. It measures at the top of the three-way group that string.Substring() and string.Remove() also sit in, and all three allocate the same 40 bytes, which is what we should expect from three spellings of one copy. Besides that, we can see that using the ReadOnlySpan<T> struct has some performance benefits over the LINQ and StringBuilder techniques.
The ranking has not moved since this article’s first benchmark run in 2024, on a different major runtime and a different version of the benchmark library. What did move is LINQ’s allocation: it printed 288 bytes then and measures 176 bytes now.
Speed is one question and the table below answers the other one, which is which of these expressions to reach for in the first place:
| Expression | What it gives back | Allocates | On an empty input | Reach for it when |
|---|---|---|---|---|
s[..^1] | a new string | one string | throws | this is the default |
s.Substring(0, s.Length - 1) | a new string | one string | throws | the codebase predates C# 8 |
s.Remove(s.Length - 1) | a new string | one string | throws | the intent is "delete", and reads better as one |
s.AsSpan()[..^1] | a ReadOnlySpan<char> | nothing | throws | the next step also takes a span |
new string(s.AsSpan()[..^1]) | a new string | one string | throws | never, on its own: it is Substring() with extra steps |
sb.Remove(sb.Length - 1, 1) | the same StringBuilder | nothing until ToString() | throws | we are already building with a StringBuilder |
sb.Length-- | nothing (mutates in place) | nothing until ToString() | throws | the same, and the call sits in a hot loop |
new string(s.Take(s.Length - 1).ToArray()) | a new string | an array and a string | returns the empty string | never; its only distinction is the empty-input column |
Conclusion
Reach for inputString[..^1]. It is the shortest form, it measures within a nanosecond or two of Substring() and Remove(), and it is the one a reader of our code will understand at a glance. Drop to inputString.AsSpan()[..^1] when the next step also takes a span and the allocation is worth avoiding, and use stringBuilder.Remove(stringBuilder.Length - 1, 1) when we are already building the string with a StringBuilder.
Whichever we choose, check the length first, and remember that one char is not always one character.
Which technique have you used before and why? Let us know in the comments section below.
Tested with .NET 10.0.10 and BenchmarkDotNet 0.15.8.