Updated on
XML deserialization turns an XML document into a C# object. We describe the shape we expect as a class, hand the document to XmlSerializer, and get back an object with its properties filled in.
Without a class to map onto, the alternative is reading and parsing an XML file and picking out the values we need.
What Is XML Deserialization in C#?
XML deserialization turns an XML document into a C# object, so we read properties instead of walking nodes.
XmlSerializer, in the System.Xml.Serialization namespace, does the work. We give it the target type, hand it a stream or a reader, and it returns an object of that type for us to cast.
Attributes drive the mapping. [XmlRoot] names the document element, [XmlElement] names a child element, [XmlAttribute] reads an XML attribute rather than an element, and [XmlArray] paired with [XmlArrayItem] handles a repeated element inside a wrapper element.
Two constraints decide whether a type can take part at all, and Microsoft Learn states both plainly: only public properties and fields can be serialized, and a class must have a parameterless constructor to be serialized by XmlSerializer.
Records qualify only once we add that constructor ourselves, which is why they get their own section below.
When we only need a few nodes, querying a document we already have in memory with XPath or with LINQ to XML reaches them directly.
How Do We Deserialize XML to an Object in C#?
Deserializing XML to an object takes three steps, and they are the same three for a one-element document and a deeply nested one.
First, describe the shape as a class. One property per element we care about, decorated with [XmlElement] when the names differ, and [XmlRoot] on the class when the document element has a name of its own.
Second, construct a serializer for that class with new XmlSerializer(typeof(Person)). It inspects the type once and generates the reading code it needs.
Third, call Deserialize(). It accepts a Stream, a TextReader or an XmlReader, and it returns object, so we cast the result to our type.
Nesting needs no extra machinery. A property whose type is another class becomes a nested element, and a List<T> property becomes a repeated element described with [XmlArray] for the wrapper and [XmlArrayItem] for each entry.
When a property name already matches its element name, the attribute is optional.
XML Serialization Attributes
C# provides a set of attributes that allow developers to control the serialization and deserialization process. These attributes include XmlRoot, XmlElement, XmlAttribute, and XmlArray, among others.
By using these attributes to decorate classes and properties, we can influence the conversion of XML data into objects.
So, let’s start our example by creating an XML file, person.xml, that requires deserialization:
<Person>
    <Name>Jane Smith</Name>
    <Age>25</Age>
</Person>
To deserialize this XML file, we need to create a new class:
[XmlRoot("Person")]
public class Person
{
    [XmlElement("Name")]
    public string Name { get; set; } = string.Empty;
    [XmlElement("Age")]
    public int Age { get; set; } = int.MinValue;
}
We define a Person class with two properties: Name and Age. We also use the XmlRoot attribute to specify that the XML element representing an instance of the Person type is named “Person”. The XML to C# Class Converter generates a class like this one, with the XmlRoot and XmlElement attributes already in place, directly from an XML sample.
The XmlElement attribute map the Name and Age properties to the corresponding XML elements within the “Person” element.
Now, let’s convert this XML to the class object:
var personSerializer = new XmlSerializer(typeof(Person));

using (var reader = new StreamReader("person.xml"))
{
    var person = (Person?)personSerializer.Deserialize(reader);
    if (person != null)
    {
        Console.WriteLine($"Name: {person.Name}, Age: {person.Age}");
    }
}
Here, we create an instance of the XmlSerializer class, specifying the type of the object we want to deserialize: Person. We then use a StreamReader to read the XML data from a person.xml file.
The Deserialize() method converts the XML data into an object, and then we cast it to a Person object, which we can use to access the deserialized values.
Handling Complex Types and Relationships
XML elements can also have nested sub-tags. Let’s create a library.xml file:
<Library>
    <Books>
        <Book>
            <Title> Book 1 </Title>
            <Author> Author 1 </Author>
        </Book>
        <Book>
            <Title> Book 2 </Title>
            <Author> Author 2 </Author>
        </Book>
    </Books>
</Library>
This XML contains multiple Book elements, each with multiple sub-elements. Therefore, to handle these several Book elements and their corresponding sub-elements, we need a class capable of accommodating them:
[XmlRoot("Library")]
public class Library
{
    [XmlArray("Books")]
    [XmlArrayItem("Book")]
    public List<Book> Books { get; set; } = new();
}

public class Book
{
    [XmlElement("Title")]
    public string Title { get; set; } = string.Empty;

    [XmlElement("Author")]
    public string Author { get; set; } = string.Empty;
}
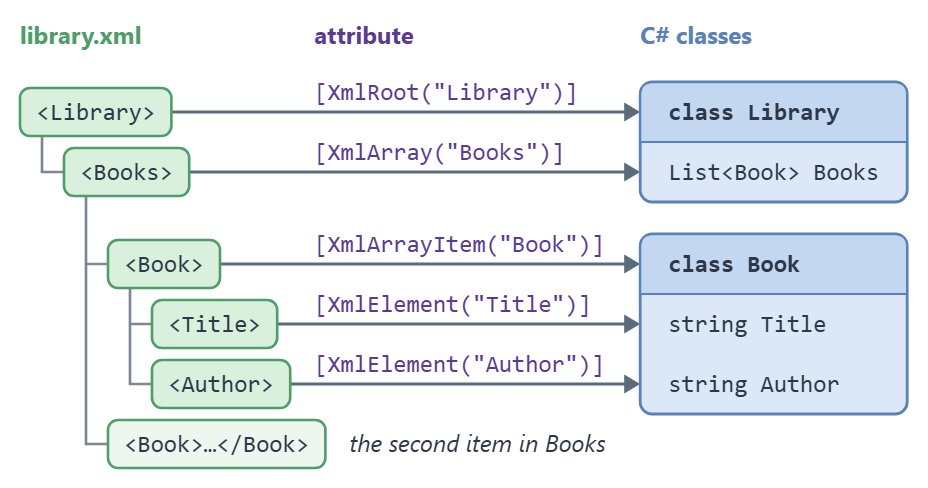
We have a Library class as a collection of books. The XmlArray attribute specifies the name of the XML element containing the list of books. The XmlArrayItem attribute specifies that each item within the “Books” element should have a representation as an XML element named “Book”.
The Book class defines properties for each book, such as Title and Author, and establishes the mapping to the corresponding XML elements.
Each of those attributes connects one element of library.xml to one part of our classes:
Let’s check how we can deserialize a complex XML structure:
var librarySerializer = new XmlSerializer(typeof(Library));

using (var reader = new StreamReader("library.xml"))
{
    var library = (Library?)librarySerializer.Deserialize(reader);
    if (library != null)
    {
        foreach (Book book in library.Books)
        {
            Console.WriteLine($"Title: {book.Title}, Author: {book.Author}");
        }
    }
}
Here, we instantiate XmlSerializer with the typeof(Library) argument to specify the target type for deserialization. We then deserialize the XML data using the Deserialize method, which takes a StreamReader to read the library.xml file.
Then, we assign the deserialized Library object to the library variable. After that, we use a loop to iterate through each Book object in the Books list of the Library object. The title and author of each book are displayed using Console.WriteLine.
Why Should We Reuse an XmlSerializer Instance in C#?
XmlSerializer generates an assembly for our type and reuses it on later calls, which makes the first call expensive and every call after it fast.
The reuse is conditional, and the condition is the constructor we picked. Microsoft Learn says the caching occurs only when using XmlSerializer(Type) and XmlSerializer(Type, String).
The same page states the consequence for every other overload: if we use any of the others, multiple versions of the same assembly are generated and never unloaded, which results in a memory leak and poor performance.
So a serializer built from typeof(T) can be constructed wherever it is convenient. A serializer built with an XmlRootAttribute, an XmlAttributeOverrides or an extra-types array has to be cached by us and reused.
Learn documents XmlSerializer as thread safe, so a static readonly field holding one instance per type is the simplest cache that works.
A serializer that renames the root element to Contact belongs in exactly that kind of field:
public static class PersonSerializer
{
    private static readonly XmlSerializer _serializer =
        new(typeof(Person), new XmlRootAttribute("Contact"));

    public static Person? Deserialize(string xml)
    {
        using var reader = new StringReader(xml);

        return (Person?)_serializer.Deserialize(reader);
    }
}
The _serializer field is built once, before PersonSerializer first uses it, and every call after that goes through the same instance.
Only two of the eight public constructors reuse the assembly they generate:
| Constructor | Generated assembly cached and reused | What we have to do |
|---|---|---|
XmlSerializer(Type) | Yes | Nothing. Construct it wherever it is needed |
XmlSerializer(Type, String) | Yes | Nothing. Construct it wherever it is needed |
XmlSerializer(Type, XmlRootAttribute) | No | Cache the instance and reuse it |
XmlSerializer(Type, XmlAttributeOverrides) | No | Cache the instance and reuse it |
XmlSerializer(Type, Type[]) | No | Cache the instance and reuse it |
XmlSerializer(Type, XmlAttributeOverrides, Type[], XmlRootAttribute, String) | No | Cache the instance and reuse it |
XmlSerializer(Type, XmlAttributeOverrides, Type[], XmlRootAttribute, String, String) | No | Cache the instance and reuse it |
XmlSerializer(XmlTypeMapping) | No | Cache the instance and reuse it |
For the six that do not, the XmlSerializer class reference says we must “cache the assemblies in a Hashtable” ourselves, keyed on every argument passed to the constructor. A static readonly field is the same idea for the case where those arguments never change.
Which Exceptions Does XML Deserialization Throw in C#?
XML deserialization in C# can encounter errors and exceptions during the process. Handling these errors gracefully and implementing robust exception management keeps the application stable and reliable.
InvalidOperationException
The InvalidOperationException is a common exception that may occur during XML deserialization. It typically indicates that the XML data does not conform to the expected format or structure defined by the target object or its attributes.
XmlException
The XmlException is another frequently encountered exception in XML deserialization. It occurs when the XML data is invalid, contains syntax errors, or the system fails to parse it correctly.
NotSupportedException
The NotSupportedException may occur during XML deserialization if the serializer encounters an unsupported XML construct or attribute. This exception occurs when the deserialization process or the chosen XML serializer does not support a specific XML feature or construct.
To illustrate this point, consider how we can handle these exceptions using a try-catch block:
try
{
    // XML deserialization code
}
catch (InvalidOperationException ex)
{
    Console.WriteLine($"Error: {ex.Message}");
}
catch (XmlException ex)
{
    Console.WriteLine($"XML Error at line {ex.LineNumber}: {ex.Message}");
}
catch (NotSupportedException ex)
{
    Console.WriteLine($"Unsupported operation: {ex.Message}");
}
catch (Exception ex)
{
    Console.WriteLine($"An error occurred: {ex.Message}");
}
We offer different ways to handle various types of exceptions, including InvalidOperationException, XmlException, and NotSupportedException. Our article on handling exceptions in C# covers the general techniques.
How Do We Deserialize XML Into a C# Record?
A record deserializes with XmlSerializer, but a positional record does not, at least not as written.
The reason is the rule from the first section. Microsoft Learn states that a class must have a parameterless constructor to be serialized by XmlSerializer, and a positional record declares only its primary constructor. Deserialization throws until we add one.
The fix is one line inside the record body: a constructor taking no arguments that chains to the primary one with placeholder values.
Property names are the second catch. A positional parameter becomes a property, and an attribute written plainly would land on the parameter, so we target the property explicitly with [property: XmlElement("Title")].
What survives of immutability is the part callers care about, since the generated properties are init-only and nothing reassigns them afterwards. What does not survive is the guarantee that a record is always fully constructed, because the parameterless constructor exists precisely to build a half-empty one first.
Records have more to them than deserialization needs, such as built-in equality comparison, and our article on records covers them in full.
First, let’s create a new record:
public record PersonRecord(string Name, int Age)
{
    public PersonRecord() : this("", int.MinValue) { }
}
Here, we define a Person record with properties for the person’s Name (string) and Age (int). The record provides an immutable representation of a person. We should pay attention that this record has a parameterless constructor. Without it, new XmlSerializer(typeof(PersonRecord)) throws an InvalidOperationException saying the type “cannot be serialized because it does not have a parameterless constructor”, before any XML is read.
Then, we add a generic helper that deserializes an XML string into any type:
public static class XmlDeserializer
{
    public static T? DeserializeXmlData<T>(string xmlData)
    {
        var serializer = new XmlSerializer(typeof(T));
        using var reader = new StringReader(xmlData);

        return (T?)serializer.Deserialize(reader);
    }
}
And we call it from Program.cs to deserialize some XML data into our record:
var personXML = """
    <PersonRecord>
        <Name>John Wick</Name>
        <Age>35</Age>
    </PersonRecord>
    """;
var personRecord = XmlDeserializer.DeserializeXmlData<PersonRecord>(personXML);
if (personRecord != null)
{
    Console.WriteLine($"Name: {personRecord.Name}, Age: {personRecord.Age}");
}
In Program.cs, we pass the XML data representing a person to the DeserializeXmlData method, which returns a Person record. The person’s name and age are then displayed using Console.WriteLine.
Records handle nested XML the same way. Let’s create a new record for Library and Books:
public record LibraryRecord()
{
    public List<BookRecord> Books { get; init; } = new();
}

public record BookRecord([property: XmlElement("Title")] string Title, [property: XmlElement("Author")] string Author)
{
    private BookRecord() : this("", "")
    {

    }
}
Without a parameterless constructor, XmlSerializer cannot be created for the record at all, so deserialization fails before it reads a single element. The private constructor on BookRecord is enough, because the serializer does not need it to be public.
Let’s check how we can deserialize XML with these records in Program.cs:
var libraryXML = """
    <LibraryRecord>
        <Books>
            <BookRecord>
                <Title>Book 3</Title>
                <Author>Author 3</Author>
            </BookRecord>
            <BookRecord>
                <Title>Book 4</Title>
                <Author>Author 4</Author>
            </BookRecord>
        </Books>
    </LibraryRecord>
    """;

var libraryRecord = XmlDeserializer.DeserializeXmlData<LibraryRecord>(libraryXML);
if (libraryRecord != null)
{
    foreach (BookRecord book in libraryRecord.Books)
    {
        Console.WriteLine($"Title: {book.Title}, Author: {book.Author}");
    }
}
We use the DeserializeXmlData method, which takes an XML string and utilizes the XmlSerializer class to deserialize it into the specified record type.
In Program.cs, we pass the XML data representing a library with books to the DeserializeXmlData method, which returns a Library record. Then, we iterate over the Books property of the Library record and display the book titles and authors using Console.WriteLine.
What Are the Best Practices for Deserializing XML?
Define Strongly-Typed Classes
To accurately represent the XML structure, we should create classes that utilize properties for mapping XML elements or attributes. It helps us to establish a simple mapping between the XML data and the corresponding class properties.
Also, we should choose appropriate data types for the properties based on the corresponding XML data. It is essential to match the data types to ensure accurate and reliable deserialization.
Additionally, we have to apply XML serialization attributes, such as XmlRoot, XmlElement, XmlAttribute, XmlArray, and XmlArrayItem, to customize the deserialization process, as we did in our previous examples. These attributes enable the definition of specific behaviors and mappings for the deserialization process, granting greater control and flexibility.
Handle Data Validation
Before performing deserialization, it is essential to validate the XML data to ensure that it conforms to the expected format and constraints. We can achieve this by utilizing XML schema validation or implementing custom validation logic. XML schema validation checks the integrity and validity of the XML data against a predefined XML schema.
Custom validation logic enables the application of specific and customized validation rules. Validating the XML data before deserialization helps us to detect and handle potential issues or inconsistencies, ensuring a smooth and reliable deserialization process:
var settings = new XmlReaderSettings();
settings.ValidationType = ValidationType.Schema;
settings.Schemas.Add(null, "schema.xsd");

using (var reader = XmlReader.Create("data.xml", settings))
{
   var serializer = new XmlSerializer(typeof(Person));
   var person = (Person)serializer.Deserialize(reader);
}
In this snippet, we provide XML data validation using an XML schema (XSD) file. We configure the XmlReaderSettings to enable schema validation by associating it with the XML reader and providing the necessary schema file.
By validating the XML data before deserialization, we can identify and address any inconsistencies or violations in the XML data.
Consider Performance
To optimize XML deserialization performance, especially for large XML documents, there are specific techniques that we can employ. One such technique is buffering, which involves reading and processing XML data in chunks, reducing the memory footprint and improving efficiency. Additionally, asynchronous processing allows for parallel execution of deserialization tasks, leveraging the capabilities of multi-threading or asynchronous programming models.
Another technique is stream-based deserialization, where XML data is read and processed incrementally from a stream, neglecting the need to load the entire XML document into memory at once:
var serializer = new XmlSerializer(typeof(Person));
using (var stream = new FileStream("data.xml", FileMode.Open))
{
   // Perform buffered or stream-based deserialization
   var person = (Person)serializer.Deserialize(stream);
}
In this snippet, we utilize a FileStream to read the XML data as part of the deserialization process. This approach allows us to improve performance for large XML documents by leveraging stream-based deserialization, which avoids loading the entire XML into memory at a time.
Security Considerations
When working with XML deserialization, it is essential to address potential security risks that may arise, such as XML External Entity (XXE) attacks. These can include techniques such as disabling external entity resolution, implementing input validation and sanitization routines, and adopting strong coding practices.
By incorporating these security measures into our XML deserialization process, we can help safeguard our application against potential security threats and ensure the integrity and safety of our data:
var settings = new XmlReaderSettings();
settings.DtdProcessing = DtdProcessing.Prohibit;
settings.XmlResolver = null;

using (var reader = XmlReader.Create("data.xml", settings))
{
   var serializer = new XmlSerializer(typeof(Person));
   var person = (Person)serializer.Deserialize(reader);
}
Here, we configure the XmlReaderSettings to prohibit the processing of Document Type Definitions (DTD) and nullify the XmlResolver. By doing so, the application mitigates the risk of XML External Entity (XXE) attacks, where malicious entities attempt to exploit vulnerabilities in XML parsing.
On .NET 10, a new XmlReaderSettings already prohibits DTD processing, so the first setting in that snippet makes the default explicit.
When Should We Use XmlSerializer Instead of DataContractSerializer?
Use XmlSerializer when we need control over the XML and DataContractSerializer when we need control over the object.
Microsoft Learn draws the line by what each one can reach. XML serialization does not convert methods, indexers, private fields or read-only properties, except read-only collections. To serialize all of an object’s fields and properties, both public and private, Learn points us at DataContractSerializer instead.
So XmlSerializer earns its place whenever somebody else decides the document shape: a schema we were handed, a SOAP contract, a legacy feed we do not control. Its attributes are the only way to say element rather than attribute, to rename, to set a namespace, or to describe an array wrapper.
DataContractSerializer gives up most of that control and gets private members and less ceremony in return, which suits a format we own on both ends.
Neither is a source generator. XML deserialization on .NET is still reflection plus a generated assembly, which is why the constructor rule above matters.
Side by side, the two serializers differ on seven points:
XmlSerializer | DataContractSerializer |
|
|---|---|---|
| Namespace | System.Xml.Serialization | System.Runtime.Serialization |
| Members it reaches | public read/write properties and fields only | public members by default; private fields and properties too, once the type carries [DataContract] and the member [DataMember] |
| Parameterless constructor | required | required for an unattributed class; not required once the type carries [DataContract] |
| Control over the XML shape | full: element vs attribute, names, namespaces, array wrappers | limited |
| Mapping attributes | [XmlRoot], [XmlElement], [XmlAttribute], [XmlArray], [XmlArrayItem], [XmlIgnore] | [DataContract], [DataMember], [IgnoreDataMember] |
| Reads XML it did not write | yes, that is what it is for | only its own contract shape |
| Fits when | the document shape is fixed by a schema, a SOAP contract or a legacy feed | we own both ends of the format |
Both of them write XML as well, and serializing an object back to XML with XmlSerializer uses the same attributes in the other direction.
Conclusion
XML deserialization empowers developers to convert XML data into strongly typed objects in C#. By leveraging the tools and libraries provided by .NET, developers can harness the benefits of XML deserialization, including simplified data integration, type safety, and increased productivity.
Tested with .NET 10.0.10 and MSTest 4.4.1.
ok, so:
1) in the first example with library, books have to be in <books> element
2) at some places you use StringReader but parameter is not xml but flie path
Thanks for the feedback! We’ve addressed these issues, so do check them out and let us know if you find anything else.
You have a loooot of mistakes in this example, I suppose you wrote it without even testing it… So, check it and fix it.
I’ve spent enough time myself to find out why examples doesn’t work.
At the same time Thank you VERY MUCH for examples.
If you want to know at least two or thre mistakes, let me know 🙂
Hey Petr, thanks for letting us know.
Sorry about the inconvenience. We did test the code, and we do check the code in the article as well, but we’re only human and mistakes do happen.
Also, the code in the article is sometimes different than the code in the source code as you’ve already seen. The code in the article uses the StreamReader class, and the code in the article uses the StringReader class.
That said, we’ve fixed the mistakes you mentioned in the other comment, so please let us know if you find any more of those.
We appreciate your feedback, and we’ll improve our process even further.
Thanks!
Hi , I m getting randomly out of memory exception on production exception.
Do you have any suggestions to fix that ?
Hi Usman. I am not sure why you get that error but for sure you are missing to dispose of some of the used resources and then those just eat up your memory. You should use some memory profiler tool to check for leaks.