Updated on
Convert.FromHexString() turns a hexadecimal string into a byte array in one line on .NET 5 and later. It accepts uppercase and lowercase digits, and it throws a FormatException for an odd length, a 0x prefix or any character that is not hex.
In the rest of this article, we build the same conversion by hand four ways, from modular arithmetic to a precomputed lookup table, and benchmark all five on .NET 10.
In our previous article on converting a byte array to a hex string, we explored several techniques for performing the conversion from binary data to hexadecimal. This time, we will explore several methods for reversing that conversion.
Where Do Hexadecimal Strings Show Up?
Our previous article discussed some of the use cases for converting a byte array into a hexadecimal string. One very common use case is as a means of providing a license key string to a user of our software. While the hex string is something easy for an end user to deal with, within our software we will need to convert it back into an array of bytes.
Hexadecimal strings are often used for transmitting data over a network connection. They are frequently found when dealing with encryption. While they are useful for the transfer and storage of data, within the context of our executing application, we generally need to convert the data back into an array of bytes. If the string holds ordinary text rather than hex digits, the job is converting a string to a byte array with an encoding instead.
With that in mind let’s take a look at five different techniques, which we can use to convert a hexadecimal string to a byte array.
Before We Begin
For each of our examples, we will use the following hexadecimal string:
"0xDEADBEEFDECAFBAD"
This string is the hexadecimal encoding of the following byte array:
[222,173,190,239,222,202,251,173]
Hexadecimal strings are often written with the prefix 0x for clarity, but this is not required. Because of this and to make our methods more general, we will support both prefixed and unprefixed strings. Our methods will also support converting both uppercase and lowercase hexadecimal strings to byte arrays.
For our article, we will create a simple static class ConversionHelpers and will add each of our methods there.
How Do We Convert Hex to Bytes With Modular Arithmetic?
The first method we will look at performs modular arithmetic on each character in the string to convert it back into an array of bytes. First, let’s take a look at the workhorse of our method, the modular calculation.
Modular Calculation
To prevent code duplication and to make the method easier to read, let’s define a helper method to perform the modular calculation:
private static int PerformModularArithmeticCalculation(char value) => (value % 32 + 9) % 25;
This calculation converts an individual hex character back into its decimal value. It is the same base 16 arithmetic we use when converting a number between hexadecimal and decimal, applied one digit at a time. Let’s unpack the method to see exactly what it is doing.
First, using the modulus operator, we restrict our char value to the range 0-31. But where did this “magic” value of 32 come from? We chose it based on the ASCII value of the characters. ‘A’ has a value of 65 while ‘a’ is 97. Subtracting them yields a distance of 32. This means performing a modulus 32 calculation on either of them yields the same result, namely 1.
Next, we add 9 to our result. Keeping in mind that the decimal value of the hexadecimal digit A is 10, it should be clear why we add 9 to our modulus result. The goal of our final calculation is: ‘A’ = 10. Thus in order to finish mapping A-F to 10-15 we have to add 9.
Our last step is another modulus operation. Once again we have an apparently “magic” number: 25. To find the source of this magic, we need to revisit the ASCII character values. This time let’s look at the ASCII values for the digits 0-9. The character ‘0’ has an ASCII value of 48. 48 mod 32 is 16. Adding 9 yields 25 (our “magic” number). And of course, 25 % 25 is 0. Since the characters ‘0’-‘9’ are contiguous within the ASCII standard, this modulus operation converts them to their equivalent decimal values.
Our Method
Now, let’s take a look at the whole method:
public static byte[] FromHexWithModularArithmetic(ReadOnlySpan<char> input)
{
    if (input.Length % 2 != 0)
        throw new ArgumentException("Input has invalid length", nameof(input));

    if (input.StartsWith("0x"))
        input = input[2..];

    if (input.IsEmpty)
        return Array.Empty<byte>();

    var dest = new byte[input.Length >> 1];
    for (int i = 0, j = 0; j < dest.Length; j++)
        dest[j] = (byte) ((PerformModularArithmeticCalculation(input[i++]) << 4) +
            PerformModularArithmeticCalculation(input[i++]));

    return dest;
}
First, we ensure our string is of a proper length. Converting a byte array to a hexadecimal string effectively doubles the length of our data, as it requires two hexadecimal characters to represent each byte. This means, that in order for our hex string to be valid, its length must be a multiple of 2. If the length is invalid, we throw an ArgumentException.
Secondly, and as we mentioned earlier, to make our methods more general, we are supporting strings with and without a leading 0x (“hex marker”). In order to do that, after validating for proper length, we check for the hex marker and strip it off if it exists. Since we are using a ReadOnlySpan<char> here, all we need to do is reset our input to be the slice of the span after the hex marker.
Thirdly, we check for an empty string. In the case of an empty string, we can bail early, returning an empty array of bytes.
One important thing to note with this method is the lack of any other validation on the input. It assumes that the input data contains only valid hexadecimal strings. This is one drawback of this method.
Next, we allocate our destination array, which has a length that is exactly one-half of the hexadecimal string length.
Lastly, we iterate the string, converting each pair of characters into their associated byte representation.
Each character makes up a nibble, with the first character representing the high bits of our byte and the second character the low bits. For this reason, we bit shift the first character calculation by 4 before adding it to the second character calculation. And finally, we store the result in our destination array.
Every hand-written method in this article comes down to the same operation: it turns the first character of a pair into the high four bits, the second into the low four bits, and combines them.
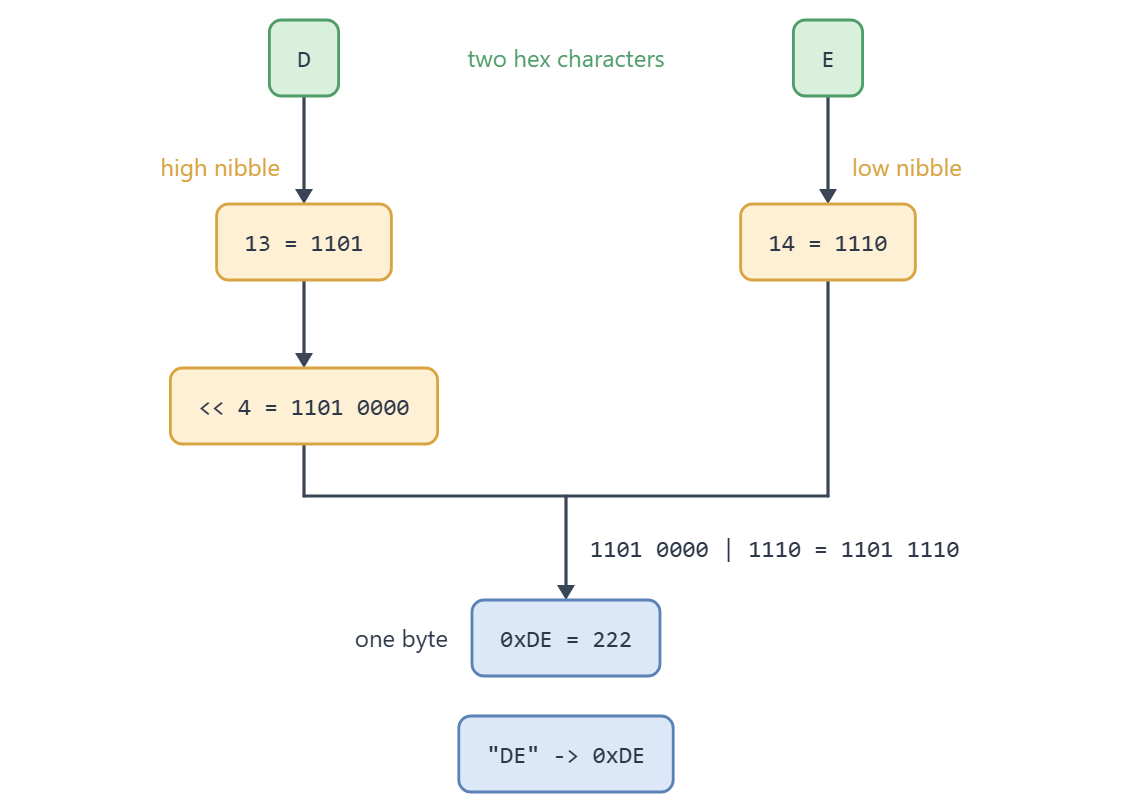
Two hex characters become one byte: the first is the high nibble, the second the low nibble.
Usage
Now, let’s take a look at our method in action:
ConversionHelpers.FromHexWithModularArithmetic("0xDEADBEEFDECAFBAD");
Which returns our expected array:
[222,173,190,239,222,202,251,173]
How Do We Convert Hex to Bytes With a Switch Expression?
Now, let’s look at performing the hex conversion using a switch expression.
Switch Computation
First, we need to define a helper method which will perform the main computation for us:
[MethodImpl(MethodImplOptions.AggressiveInlining)]
internal static byte ComputeNibbleFromHexChar(char hexChar) =>
    hexChar switch
    {
        >= '0' and <= '9' => (byte) (hexChar - '0'),
        >= 'A' and <= 'F' => (byte) (hexChar - 'A' + 10),
        >= 'a' and <= 'f' => (byte) (hexChar - 'a' + 10),
        _ => throw new ArgumentException($"Invalid hex digit: '{hexChar}'", nameof(hexChar))
    };
For performance reasons, we add the attribute MethodImpl(MethodImplOptions.AggressiveInlining) hinting to the JIT compiler that this method is a good candidate for inlining. This doesn’t guarantee inlining but rather instructs the JIT to consider it. For this attribute, our class file needs using System.Runtime.CompilerServices; at the top.
Next, we use a switch expression with pattern matching to convert the hex character to its decimal equivalent. If the hex char is a digit, we simply subtract the value of the ‘0’ from the digit character to convert it to decimal. For any of the values A-F and a-f, we perform the same type of subtraction, which will yield a value between 0 and 5, so we need to add 10 to compute the appropriate value.
Lastly, for any value that doesn’t match, we throw an ArgumentException, indicating that the value is not a valid hex digit.
Our Method
Now, let’s take a look at our main method:
public static unsafe byte[] FromHexWithSwitchComputation(ReadOnlySpan<char> input)
{
    // ...Initial checks removed for brevity...
    var dest = new byte[input.Length >> 1];
    fixed (char* s = input)
    fixed (byte* d = dest)
    {
        var destPtr = d;
        var srcPtr = s;
        var srcEnd = s + input.Length;
        while (srcPtr < srcEnd)
        {
            var result = (byte) (ComputeNibbleFromHexChar(*srcPtr++) << 4);
            result |= ComputeNibbleFromHexChar(*srcPtr++);
            *destPtr++ = result;
        }
    }

    return dest;
}
After the same initial checks as in our first method, we allocate our destination array. Next, for performance reasons, we pin both our input and our destination array (our article on pointers in C# explains fixed and pinning). Pointers make this unsafe code, so our project file needs <AllowUnsafeBlocks>true</AllowUnsafeBlocks> to compile it. In the next lines, we make a copy of the pointers to enable incrementing them within our loop, and we compute a pointer to the end of the input. Then we loop until our source pointer reaches that end.
Why not stop at the null terminator, the way C strings do? Because input is a ReadOnlySpan<char>, and a span is not always a whole string. A slice of a longer string ends in the middle of other characters, and a span over a char[] has no terminator at all. The length is the only end we can trust.
Inside the loop, we perform several actions. Our first line itself performs three actions. First, it computes the decimal value of the hex character. Second, it moves our srcPtr to the next character in the hex string. Last, since this is the high nibble of our resulting byte, it left-shifts the value by 4.
Our second line is similar to the first, only without the need to perform a bit shift since this is the low nibble of the resultant byte.
Lastly, we store the result in the destination array and increment the destPtr to the next element in the destination.
Usage
So, let’s see it in action:
ConversionHelpers.FromHexWithSwitchComputation("0xDEADBEEFDECAFBAD");
Again we see the method returns the expected result:
[222,173,190,239,222,202,251,173]
How Do We Convert Hex to Bytes With Bit Manipulation?
Our next conversion method involves performing a simple bit manipulation calculation.
Bit Manipulation Calculation
First, let’s take a look at our bit calculation:
[MethodImpl(MethodImplOptions.AggressiveInlining)]
private static int PerformBitManipulation(int charValue)
{
    charValue -= 'A';

    return charValue + 10 + ((charValue >> 31) & 7);
}
Let’s walk through our code to understand what our calculation is doing. In our first step, we subtract the value of the character ‘A’ (65) from our input. This will be important as we look at the next part of the calculation.
For the next step, we need to consider what the behavior is for the values A-F and 0-9 separately. First, let’s examine A-F. Since the value of A is 65, after our initial subtraction, our value is going to be between 0 and 5. This means that when we add 10 to it, our value will now be between 10 and 15. The following computation value >> 31 extracts the sign from the value, which in this case is 0. Of course a bitwise & of anything with 0 yields 0. So, for the values A-F, the calculation is equivalent to value - 65 + 10.
Now let’s consider the case of characters 0-9. When we subtract 65 from this we end up with a value in the range between -17 and -8. The next step of adding 10 shifts our range to between -7 and 2. Then in our last step, extracting the sign, we end up performing the calculation -1 & 7, which yields 7. Adding this to our value shifts it to the range 0 to 9.
Our Method
Now, let’s put it all together:
public static unsafe byte[] FromHexWithBitManipulation(ReadOnlySpan<char> input)
{
    // ...Initial checks removed for brevity...
    var dest = new byte[input.Length >> 1];
    fixed (char* srcPtr = input)
    fixed (byte* destPtr = dest)
    {
        var sPtr = &srcPtr[0];
        var dPtr = &destPtr[0];
        var sEnd = sPtr + input.Length;
        while (sPtr < sEnd)
        {
            var hi = PerformBitManipulation(*sPtr++);
            var lo = PerformBitManipulation(*sPtr++) & 0x0F;
            *dPtr++ = (byte) (lo | (hi << 4));
        }
    }

    return dest;
}
As we saw earlier, after our initial validation checks, we begin by allocating our destination array. This is followed by getting pointers into our input data and destination array. Next, we make copies of the pointers so we can increment them, compute where the input ends, and iterate up to that point.
For each character, we perform our bit manipulation, but for the low part of the byte, we also perform a bitwise & with 0x0F, which handles lowercase a-f. It is equivalent to conditionally subtracting 32 (the difference between the ASCII values of A and a) from the value when the input is lowercase.
Usage
Now, let’s watch it in action, but for fun, we’ll switch it up a bit and pass in lowercase hexadecimal digits:
ConversionHelpers.FromHexWithBitManipulation("0xdeadbeefdecafbad");
Once again the method returns the expected result:
[222,173,190,239,222,202,251,173]
How Do We Convert Hex to Bytes With Convert.FromHexString()?
Convert.FromHexString() turns a string of hex digits into the bytes they encode, two characters per byte. It has been part of the Convert class since .NET 5, so on any supported .NET version the whole conversion is a single call.
The method accepts uppercase, lowercase and mixed case, so DEADBEEF, deadbeef and DeAdBeEf all decode to the same four bytes. It does not accept a 0x prefix, dashes between pairs or spaces, which is why our wrapper below strips the prefix first.
On bad input it throws a FormatException, with one message for an odd number of characters and another for a character that is not a hex digit. An empty string returns an empty array.
Two newer forms sit beside it. Since .NET 9, an overload writes into a Span<byte> we pass in and returns an OperationStatus instead of throwing. Since .NET 10, both forms also accept UTF-8 bytes directly.
| Call | Input | On bad input | Earliest .NET |
|---|---|---|---|
FromHexString(string) | A string | Throws FormatException | .NET 5 |
FromHexString(ReadOnlySpan<char>) | A span of characters | Throws FormatException | .NET 5 |
FromHexString(string, Span<byte>, out int, out int) | A string, decoded into our buffer | Returns an OperationStatus | .NET 9 |
FromHexString(ReadOnlySpan<char>, Span<byte>, out int, out int) | A span of characters, decoded into our buffer | Returns an OperationStatus | .NET 9 |
FromHexString(ReadOnlySpan<byte>) | UTF-8 bytes | Throws FormatException | .NET 10 |
FromHexString(ReadOnlySpan<byte>, Span<byte>, out int, out int) | UTF-8 bytes, decoded into our buffer | Returns an OperationStatus | .NET 10 |
.NET 5 brought us a long-awaited addition to the Convert static class, the ToHexString() and FromHexString() methods. In our previous article, we saw how to use the ToHexString() method to convert a byte array to hex. Now, we can use the FromHexString() method to reverse that operation. Microsoft’s API documentation describes the input as a string “which encodes binary data as hex characters”, and lists a FormatException for a length that “is not zero or a multiple of 2”.
Let’s take a look at the code:
public static byte[] FromHexWithConvert(ReadOnlySpan<char> input)
{
    if (input.StartsWith("0x"))
        input = input[2..];

    return Convert.FromHexString(input);
}
There is almost nothing to this method. As we have seen in previous methods, we first check for the “hex marker” in the string and remove it if necessary. After that we only have one other step to perform, namely calling the built-in FromHexString() method. In our case, we are passing in a ReadOnlySpan<char>, but the method also has overloads for a string and, since .NET 10, for UTF-8 bytes. We don’t need to perform any additional validation on our input data, as the built-in method takes care of that, throwing a FormatException on invalid data.
One of the biggest advantages of calling a framework method is maintenance. We don’t have to worry about maintaining this method. We don’t have to add tests around it to protect ourselves from silly mistakes in future code updates. It is part of the framework so we can expect it to be correct and reasonably performant.
Usage
Let’s observe the built-in method in action:
ConversionHelpers.FromHexWithConvert("0xDEADBEEFDECAFBAD");
As expected, it returns the following array:
[222,173,190,239,222,202,251,173]
What Happens When FromHexString() Gets an Odd-Length String?
It throws a FormatException before it decodes anything. On .NET 10 the message reads “The input is not a valid hex string as its length is not a multiple of 2.” An even-length string with a stray character gets a different message that ends “as it contains a non-hex character.”
The length rule comes straight from the format. Every byte is exactly two hex digits, so in ABC the C has no partner, and the method refuses to guess whether a leading zero went missing.
Two everyday inputs trip it by accident. Output from BitConverter.ToString() keeps its dashes, so DE-AD-BE-EF fails the length check, and a 0x prefix fails the character check.
When throwing is the wrong tool, the .NET 9 overload that writes into a Span<byte> reports the problem instead: NeedMoreData for a leftover digit, InvalidData for a bad character, and DestinationTooSmall when our buffer runs out.
Here is the span overload handling the same odd-length input without an exception:
Span<byte> buffer = stackalloc byte[8];
var status = Convert.FromHexString("ABC", buffer, out var charsConsumed, out var bytesWritten);
The call returns OperationStatus.NeedMoreData, with charsConsumed at 2 and bytesWritten at 1: it decoded the AB it could and left the C for us to deal with.
How Do We Convert Hex to Bytes With a Lookup Table?
The last method we will consider is converting using a precomputed lookup table. In our previous article, we discussed the speed/space tradeoff and how we can often increase performance at the cost of using more memory. This is a prime example of that truth.
We precompute two lookup tables. One for the high bits and one for the low bits of our converted byte. For brevity’s sake, we are not listing the tables in the article, but both the tables and a method for computing them can be found in the GitHub repo for this article. When we copy LookupTables.cs into our project, we give it the same namespace as our ConversionHelpers class.
Now, let’s take a look at the code:
public static unsafe byte[] FromHexWithLookup(ReadOnlySpan<char> input)
{
    // ...Initial checks removed for brevity...
    var dest = new byte[input.Length >> 1];
    fixed (char* inputRef = input)
    fixed (byte* hiRef = LookupTables.FromHexHighBitsLookup)
    fixed (byte* lowRef = LookupTables.FromHexLowBitsLookup)
    fixed (byte* destRef = dest)
    {
        var s = &inputRef[0];
        var d = destRef;
        var end = s + input.Length;

        while (s < end)
        {
            byte lowValue;

            if (*s > 102 || (*d = hiRef[*s++]) == 255 ||
                *s > 102 || (lowValue = lowRef[*s++]) == 255)
                throw new ArgumentException("Input contains a non-hex character", nameof(input));

            *d++ += lowValue;
        }

        return dest;
    }
}
After the initial checks, we allocate the destination array. Following that, we get pointers to our input, to the lookup tables, and to our destination. Then, as we have seen before, we create two incrementable pointers to our input and our destination array, plus one that marks the end of the input.
Once all of our setup is done, we loop until we reach the end of the input, converting the hexadecimal character pairs to bytes as we go.
The Magic Inside the Loop
The real magic of our method occurs inside the loop. First, we have to create a variable to hold the low nibble of our final byte. The next step is a rather complicated-looking if statement, but this is the workhorse of the method, so let’s break it down step by step.
Our first check ensures the character is not too large to be a valid hex character (f is 102 in ASCII).
The next statement performs a table lookup for the high nibble using the character value as an index, while also incrementing the input pointer. This check also assigns the lookup result to the byte at the destination pointer. The equality check here ensures that the input character is a valid hexadecimal digit. In our lookup table, we set all invalid indices to the value 255. If a lookup returns 255, then we know the character is not valid.
The second half of the if statement performs the same operation, only now using the low-bit lookup table. The other main difference is that we also assign the lookup result to a temporary variable, which we add to the destination byte in the next step.
Assuming all was valid in the if block, we add the low nibble to the byte at the destination pointer and increment the pointer to the next location in the destination array.
Usage
Now, let’s put our method to work:
ConversionHelpers.FromHexWithLookup("0xDEADBEEFDECAFBAD");
As before, the method returns the expected array:
[222,173,190,239,222,202,251,173]
How Fast Is Each Conversion Method?
When comparing different ways of performing the same calculation, it is important to benchmark them, and our introduction to benchmarking in C# shows how BenchmarkDotNet works. This aids us immensely when choosing which method to implement in our own code. We will run benchmarks for different data sizes (64, 256, 8,192 and 2,097,152 character strings) as performance can vary based on the length of the input data. The 8,192-character string is the hex form of a 4,096-byte array, the same size our previous article benchmarks in the other direction.
On .NET 10, the built-in FromHexString() is the fastest at every size we measure. Among our own methods, the lookup table and bit manipulation take second and third place at every size, and the switch expression and modular arithmetic trail.
Our benchmarks are running on a Windows 10 PC with an AMD Ryzen 5 3600 and 6 physical cores:
BenchmarkDotNet v0.15.8, Windows 10 (10.0.19045.6466/22H2/2022Update)
AMD Ryzen 5 3600 3.60GHz, 1 CPU, 12 logical and 6 physical cores
.NET SDK 10.0.302
  [Host]     : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3
  DefaultJob : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3
Now let’s take a look at the results.
64-Character Hexadecimal String Results
| Method                 | source               | Mean            | Error         | StdDev        |
|----------------------- |--------------------- |----------------:|--------------:|--------------:|
| UsingConvert           | 3E17B(...)AB036 [64] |        38.43 ns |      0.822 ns |      0.913 ns |
| UsingLookup            | 3E17B(...)AB036 [64] |        52.51 ns |      1.089 ns |      1.070 ns |
| UsingBitManipulation   | 3E17B(...)AB036 [64] |        54.81 ns |      1.131 ns |      1.346 ns |
| UsingSwitchComputation | 3E17B(...)AB036 [64] |        76.22 ns |      1.565 ns |      1.607 ns |
| UsingModularArithmetic | 3E17B(...)AB036 [64] |        93.39 ns |      1.842 ns |      1.892 ns |
256-Character Hexadecimal String Results
| Method                 | source               | Mean            | Error         | StdDev        |
|----------------------- |--------------------- |----------------:|--------------:|--------------:|
| UsingConvert           | CFD6(...)5125 [256]  |       131.75 ns |      2.712 ns |      5.541 ns |
| UsingLookup            | CFD6(...)5125 [256]  |       183.57 ns |      3.728 ns |      8.933 ns |
| UsingBitManipulation   | CFD6(...)5125 [256]  |       208.46 ns |      4.194 ns |      6.277 ns |
| UsingSwitchComputation | CFD6(...)5125 [256]  |       284.57 ns |      5.771 ns |      6.175 ns |
| UsingModularArithmetic | CFD6(...)5125 [256]  |       365.38 ns |      3.972 ns |      3.521 ns |
8,192-Character Hexadecimal String Results
| Method                 | source               | Mean            | Error         | StdDev        |
|----------------------- |--------------------- |----------------:|--------------:|--------------:|
| UsingConvert           | 3577(...)6345 [8192] |     3,851.07 ns |     63.279 ns |    127.827 ns |
| UsingLookup            | 3577(...)6345 [8192] |     4,938.99 ns |     96.109 ns |    106.825 ns |
| UsingBitManipulation   | 3577(...)6345 [8192] |     6,454.93 ns |     41.794 ns |     34.900 ns |
| UsingSwitchComputation | 3577(...)6345 [8192] |    10,035.54 ns |    113.054 ns |    105.751 ns |
| UsingModularArithmetic | 3577(...)6345 [8192] |    11,284.70 ns |    200.571 ns |    253.658 ns |
2,097,152-Character Hexadecimal String Results
| Method                 | source               | Mean            | Error         | StdDev        |
|----------------------- |--------------------- |----------------:|--------------:|--------------:|
| UsingConvert           | 15(...)A3 [2097152]  | 1,126,567.55 ns | 20,373.819 ns | 17,013.062 ns |
| UsingLookup            | 15(...)A3 [2097152]  | 1,521,061.85 ns | 24,133.452 ns | 20,152.525 ns |
| UsingBitManipulation   | 15(...)A3 [2097152]  | 1,687,001.15 ns | 33,541.778 ns | 35,889.326 ns |
| UsingModularArithmetic | 15(...)A3 [2097152]  | 2,841,331.05 ns | 31,757.411 ns | 28,152.118 ns |
| UsingSwitchComputation | 15(...)A3 [2097152]  | 7,254,610.31 ns | 81,352.840 ns | 76,097.497 ns |
Which Method Should We Use?
We should use Convert.FromHexString() on any supported .NET version. It is one line, the runtime team maintains it, it validates every character, and in our .NET 10 benchmark it came out ahead of every hand-written method in this article at all four input sizes.
The manual methods earn their place in two situations. The first is a target the built-in method does not reach, such as .NET Framework or .NET Standard 2.0, where one of these techniques has to stand in. Of the four, the lookup table and bit manipulation are the fastest, and the switch expression is the easiest to read of the ones that still reject bad characters.
The second is a hot path where the new array is the cost. Every method here allocates a byte array half the length of the input, so if that allocation is what hurts, the fix is the .NET 9 overload that decodes into a buffer we own instead of allocating a new array.
| Method | Rejects bad input | Choose it when |
|---|---|---|
Convert.FromHexString() | Yes, throws FormatException | Always on .NET 5 or later, unless the next row applies |
Convert.FromHexString() into a Span<byte> | Yes, returns InvalidData | .NET 9 or later, in a hot path, or when bad input is expected and should not throw |
| Lookup table | Yes, throws ArgumentException | The built-in method is not available and speed matters |
| Bit manipulation | No, only the length | The built-in method is not available, speed matters and the input is already trusted |
| Switch expression | Yes, throws ArgumentException | We want a readable decoder that still checks every character |
| Modular arithmetic | No, only the length | We want to understand the arithmetic. It is the slowest up to 8,192 characters |
Still, the difference in performance between the built-in method and our two fastest methods is not so significant. For an average-sized hexadecimal string, it is a matter of nanoseconds, and unless we are performing a large amount of conversions in a tight loop, it will all but disappear.
So what does that mean? If we are using .NET 5 or later, we should use the built-in FromHexString() method, tight loop or not. This makes our code cleaner, more readable, and above all, more maintainable. At the end of the day, clear, concise, and maintainable code is a huge win for all involved in the project.
Conclusion
In this article, we have examined several different methods for converting a hexadecimal string into a byte array. We also benchmarked each of the implementations in order to have a better idea of the performance characteristics with different size data sets. From those results, we saw that on .NET 10 the framework-provided FromHexString() is both the simplest option and the fastest, and that our lookup table is the fastest of the methods we wrote ourselves. So, if we are able to use the newer framework-provided method, we should choose that option. Our future self will thank us for keeping the code clear and readable.
Tested with .NET 10.0.10.