Updated on
Convert.ToHexString() turns a byte array into an uppercase hex string in one line, and Convert.ToHexStringLower() does the same in lowercase. On .NET 5 and later, that is the answer.
The rest of this article is about the cases where that answer does not apply, and about what the runtime is doing for us. We build the conversion by hand six ways, from the BitConverter call everyone recommends to a precomputed lookup table, and we benchmark all of them.
Let’s dive in.
What Is a Hexadecimal String, and Why Convert Bytes to One?
A hexadecimal string represents binary data in base 16, so each byte becomes exactly two characters: the byte 255 becomes FF, and 42 becomes 2A.
That fixed two-characters-per-byte ratio is the whole appeal. An 8-byte array is always a 16-character string, the conversion loses nothing, and the result is made of characters a person can read aloud, type into a form, and paste into a bug report.
Binary data that has to cross a text boundary is where this turns up. A password hash, a file checksum, a license key, a certificate thumbprint: all of them are bytes that somebody eventually has to look at.
Case is the one decision the format leaves us. DEADBEEF and deadbeef carry identical values, and .NET provides a separate method for each, so we pick one and stay consistent across the application.
Every example in this article produces uppercase.
Those text boundaries are usually the point at which we already have the bytes in hand. If they started life as text, converting a string to a byte array is the step that produced them, and where the bytes came from, if they arrived on a stream covers the case where they reach us as a stream instead.
A common use case for converting between byte arrays and hexadecimal strings is password hashing and salting. You can see this in action in our article on Hashing and Salting Passwords.
Another common usage of hexadecimal strings is as license key values. Because they are easy for humans to read and type, they make great candidates for use as license keys. In general, if we want to represent binary data in a human-readable form, converting it to a hexadecimal string is a great option.
Before We Begin
Each of the examples in our article will be focusing on how to convert a byte array into an uppercase hexadecimal string. If you are interested in lowercase implementations and options, you can visit the source code repository for this article. There you will find lowercase implementations of each method.
While looking at several different algorithms and approaches, we will also benchmark each of the options. This is important so that we have at least some idea of how the code will perform in a real-world scenario. While performance is always an important consideration when choosing a method, we also need to bear in mind the platforms we are targeting and the future maintenance of our code base. Sometimes a slower, but easier-to-implement solution may be the correct one.
For each of the examples in this article, we will be using the following byte array:
var source = new byte[] {222, 173, 190, 239, 222, 202, 251, 173};
Except for the first BitConverter example, all the samples shown in our article will produce the following output:
DEADBEEFDECAFBAD
Now we are ready, so, let’s get started converting byte arrays to hexadecimal strings!
How Do We Convert Bytes to Hex With BitConverter?
One of the most common recommendations seen on the internet is using BitConverter to perform a byte-to-hex conversion. While this method is frequently recommended, as we will see later in our benchmarks, due to its lackluster performance, it is probably not a method we want to use.
Another issue with this method is that the resultant string will contain each pair of hex digits separated by a -. Let’s look at it in action:
BitConverter.ToString(source);
Which produces the following output:
DE-AD-BE-EF-DE-CA-FB-AD
To remove the dashes, we need to call String.Replace() on the result:
BitConverter.ToString(source).Replace("-", string.Empty);
How Do We Convert Bytes to Hex With a StringBuilder?
A StringBuilder loop is another popular method seen across the internet. The usual form calls StringBuilder.AppendFormat() once per byte with the format string "X2" (or "x2" if we want lowercase), and as we will see in the benchmarks, this family is one of the worst in terms of performance.
We can improve on it by taking advantage of Span, stackalloc and TryFormat(). TryFormat() allows us to perform the hex encoding into a pre-allocated (in our case, stack-allocated) buffer. This faster variant is the one we show and benchmark here, so the plain AppendFormat() loop is slower still than the benchmark row named after it.
This improves performance by reducing memory allocations and thus pressure on the garbage collector:
Span<char> buffer = stackalloc char[64];
var sb = new StringBuilder(source.Length * 2);
var bufferIndex = 0;
ref var srcRef = ref MemoryMarshal.GetReference(source.AsSpan());
for (var i = 0; i < source.Length; ++i)
{
    var b = Unsafe.Add(ref srcRef, i);
    b.TryFormat(buffer.Slice(bufferIndex, 2), out _, "X2");
    bufferIndex += 2;
    if (bufferIndex == buffer.Length)
    {
        sb.Append(buffer);
        bufferIndex = 0;
    }
}
if (bufferIndex > 0) sb.Append(buffer[..bufferIndex]);
sb.ToString();
Now, let’s take a look at what’s going on here. The first thing we do is stackalloc a small buffer for holding our hex-encoded strings. Next, we create a StringBuilder of appropriate size to hold our result. bufferIndex is used to track our location within the stack-allocated buffer, and lastly we get a reference to a Span over our input source.
Next, we iterate over the source byte array, getting a managed reference to each item in the source array:
var b = Unsafe.Add(ref srcRef, i);
For each byte, we call TryFormat() to convert it to a two-character hex string, storing it in a two-character slice of our buffer. After the conversion, we increment our buffer index. Next, we check to see if we have filled our buffer. If it is full, we append it to the StringBuilder and reset bufferIndex to 0.
The penultimate step, after iterating the source buffer, is to check if there is any unappended data in our buffer and append it if necessary.
if (bufferIndex > 0) sb.Append(buffer[..bufferIndex]);
Lastly, we call ToString() on our StringBuilder to get our converted string.
Performance Improvement Through TryFormat() and String.Create()
Related to the StringBuilder option above, we can combine both the TryFormat() and String.Create() methods to improve performance:
string.Create(source.Length * 2, source, (chars, src) =>
{
    ref var srcPtr = ref MemoryMarshal.GetArrayDataReference(src);
    var destIndex = 0;
    for (var i = 0; i < src.Length; ++i)
    {
        var b = Unsafe.Add(ref srcPtr, i);
        b.TryFormat(chars[destIndex..], out _, "X2");
        destIndex += 2;
    }
});
Here, instead of creating a StringBuilder, we create the string directly and modify it in place. This saves us both an extra buffer allocation for the StringBuilder and a copy operation, when calling StringBuilder.ToString(), to get the result. String.Create() gives us direct access to the underlying characters via a Span. This allows us to set each character directly.
How Do We Convert Bytes to Hex With Bit Manipulation?
Another approach we can take when converting a byte array into a hexadecimal string is bit manipulation. By performing some simple bit shifts and mathematical operations, we can compute the resulting characters needed for hexadecimal encoding.
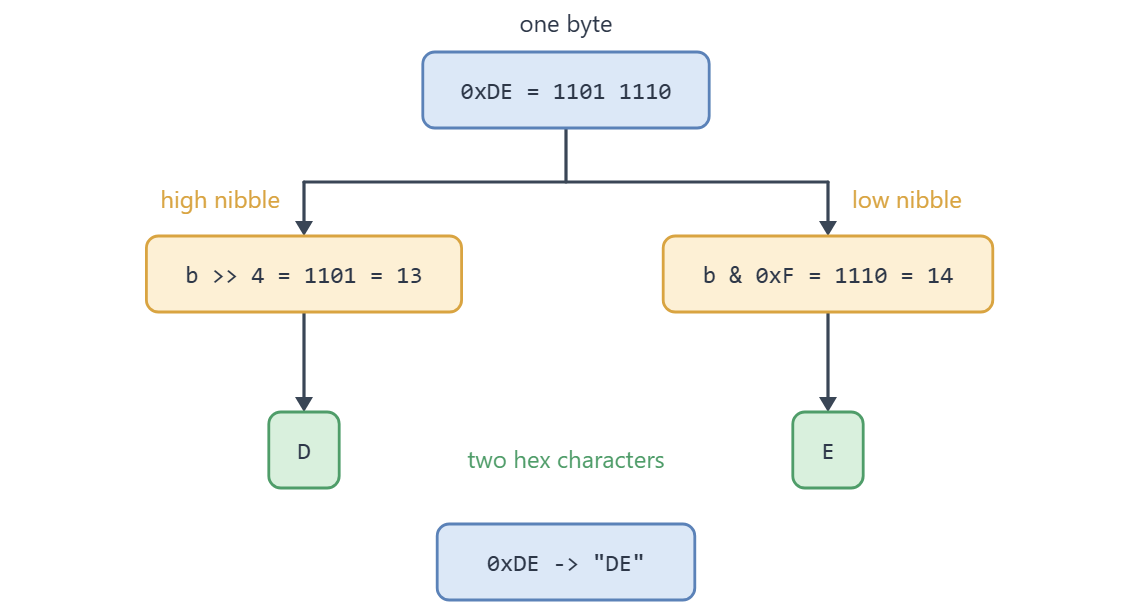
Every method below that is not a library call works the same way: split each byte into its high and low nibble, then turn each nibble into one character.
The Setup
First, we declare our offset constants, which we need when computing a character value. The letterOffset is the difference between the ASCII value of the letter A and the decimal value 10 (0xA). This offset is used to convert the numeric values 10-15 into the corresponding hexadecimal letters A-F. We also need a digit offset value for converting the digits 0-9 to the appropriate character values.
We can compute this by subtracting the letterOffset from the character 0:
const int letterOffset = 'A' - 0xA; // For lowercase: 'a' - 0XA
const int digitOffset = '0'-letterOffset;
The Magic
Next, we declare a simple helper method to make the code more readable. This method performs the actual computation to convert a nibble (4 bits) into the appropriate hex character:
static char ComputeCharFromNibble(int nibble, int letterOffset, int digitOffset)
{
    var digitCalculation = ((nibble - 10) >> 31) & digitOffset;
    return (char) (letterOffset + nibble + digitCalculation);
}
Let’s walk through this code so that we can understand how the magic happens.
First, let’s focus on digit calculation: (((nibble - 10) >> 31) & digitOffset). nibble-10 will be negative when nibble < 10 and positive when nibble >= 10. Shifting this value by 31 extracts the sign, resulting in either 0 or -1. We do this because when nibble >= 10, to compute the correct hex character, we need to add digitOffset. Instead of conditionally performing the addition, we use the fact that -1 in binary, has all bits set to 1 and 0 has all bits set to 0. This means that performing bitwise &, results in 0 when nibble < 10 and digitOffset when it is >= 10.
Lastly, we add this value to the result of the first calculation (letterOffset + nibble) and we get the proper hex character. It is the same base 16 arithmetic we use when converting a number between hexadecimal and decimal, applied four bits at a time.
The Complete Example
Now that we have computed our offsets and created our helper method to perform the bit manipulation, let’s put it all together:
return string.Create(source.Length * 2,
    (Source: source, LetterOffset: letterOffset, DigitOffset: digitOffset),
    (chars, args) =>
    {
        ref var srcPtr = ref MemoryMarshal.GetArrayDataReference(args.Source);
        ref var destPtr = ref MemoryMarshal.GetReference(chars);
        for (var i = 0; i < args.Source.Length; ++i)
        {
            var b = Unsafe.Add(ref srcPtr, i);
            destPtr = ComputeCharFromNibble(b >> 4, args.LetterOffset, args.DigitOffset);
            destPtr = ref Unsafe.Add(ref destPtr, 1);
            destPtr = ComputeCharFromNibble(b & 0xF, args.LetterOffset, args.DigitOffset);
            destPtr = ref Unsafe.Add(ref destPtr, 1);
        }
    });
First, we get references to the source array and our destination Span. Second, we iterate through the source one byte at a time. Then for each byte, we compute two characters, the first from the high nibble (b >> 4) and the second from the low nibble (b & 0xF). Between each of the calculations, we advance our reference pointer to the next location within the destination.
How Do We Convert Bytes to Hex With a Span Over an Alphabet String?
Another method we can use to convert a byte array into a hexadecimal string is by initializing a small array containing each hex character and then performing a lookup within the array to compute the proper hex character. Once again, we are using the high and low nibbles from each byte, but instead of performing bit manipulations and offset calculations, we use them directly to index into our string.
First, we need to declare our lookup array. For performance reasons (the explanation is outside the scope of this article), we will declare it as a ReadOnlySpan<byte> over a UTF8 string:
static ReadOnlySpan<byte> HexAlphabet => "0123456789ABCDEF"u8;
After the declaration of HexAlphabet, we can have a closer look at the implementation:
string.Create(source.Length * 2, source, (chars, src) =>
{
    ref var srcPtr = ref MemoryMarshal.GetArrayDataReference(src);
    ref var hexSpan = ref MemoryMarshal.GetReference(HexAlphabet);
    ref var destPtr = ref MemoryMarshal.GetReference(chars);
    for (var i = 0; i < src.Length; ++i)
    {
        var b = Unsafe.Add(ref srcPtr, i);
        destPtr = (char) Unsafe.Add(ref hexSpan, b >> 4);
        destPtr = ref Unsafe.Add(ref destPtr, 1);
        destPtr = (char) Unsafe.Add(ref hexSpan, b & 0xF);
        destPtr = ref Unsafe.Add(ref destPtr, 1);
    }
});
First, we get references to our source array, our hex alphabet array, and finally, our destination. Then iterating through the source bytes, we compute two characters for each byte. This is accomplished by calculating both the high and low nibbles from the byte and using those as indexes into the hex alphabet Span.
Lastly, using our destination reference, we store the returned character and increment the reference.
Why a ReadOnlySpan<byte> over a UTF8 literal costs nothing at runtime is explained in detail here.
How Do We Convert Bytes to Hex With a Lookup Table?
One of the most performant methods we can use involves using a precomputed lookup table to compute the hex characters two at a time. In this article, we are only showing how to do this in .NET 6 and greater. If you need a solution that can target an older framework, you can check out the source code for the article, where we present a solution that targets .NET Standard 2.0.
The Lookup Table
When talking about increasing our application performance, there is usually a tradeoff we have to make between memory usage and performance.
In our case, when converting bytes to hex, we get a significant performance boost at the cost of a few additional kilobytes of memory (~1k for our lookup tables). Our lookup table has 256 entries, allowing us to index directly into it from our byte value. This in turn allows us to map each byte to a uint that represents the two UTF16 hex characters needed to represent the byte:
public static class LookupTables
{
    internal static readonly uint[] HexLookupUpperLittleEndian = { /* Omitted for brevity */ };
    internal static readonly uint[] HexLookupUpperBigEndian = { /* Omitted for brevity */ };

    // The matching lowercase pair lives beside these in the source repository.
    public static uint[] GetLookupTable(bool toLower) =>
        BitConverter.IsLittleEndian ? HexLookupUpperLittleEndian : HexLookupUpperBigEndian;
}
One thing to notice is the fact that there are actually two lookup tables. Since our values are uint we must consider the endianness of the system where our code is running. This means that we have to have one lookup table for little-endian systems and one for big-endian. For clarity and readability, we add a simple helper method that returns the appropriate table based on the current system’s endianness.
For an example of how to compute the lookup tables, please check out the source code for this article.
The Code
Now that we have our lookup tables computed, let’s see how we can use them:
string.Create(source.Length * 2, source, (chars, src) =>
{
    ref var sPtr = ref MemoryMarshal.GetArrayDataReference(src);
    ref var lookupTable = ref MemoryMarshal.GetArrayDataReference(LookupTables.GetLookupTable(false));
    ref var cPtr = ref MemoryMarshal.GetReference(chars);
    for (var i = 0; i < src.Length; ++i)
    {
        var b = Unsafe.Add(ref sPtr, i);
        Unsafe.As<char, uint>(ref cPtr) = Unsafe.Add(ref lookupTable, b);
        cPtr = ref Unsafe.Add(ref cPtr, 2);
    }
});
This code may look a bit familiar, as we have already seen several of the techniques in our earlier examples.
First, we get references to the source array, the lookup table, and the destination. Next, as we have done previously, we iterate over the source array. This time, we don’t need to compute nibbles or anything like that, as our lookup tables map directly from byte to uint.
It’s crucial to note that when setting the character values, we treat our destination reference as a uint as opposed to a char. This enables us to set two character values in the destination string at once. This is possible because uint is twice the size of char. Because of this, we must also increment our destination reference by 2 on each loop iteration.
How Do We Convert Bytes to Hex With Convert.ToHexString()?
With the advent of .NET 5.0, we now have a built-in method for converting a byte array to a hexadecimal string.
This method takes advantage of hardware-level SIMD instructions where possible to gain even more performance. We can read the encoding path for ourselves in the runtime source, which takes a vectorized branch for any input of four bytes or more:
Convert.ToHexString(source);
Microsoft’s API documentation describes it as a method that “converts an array of 8-bit unsigned integers to its equivalent string representation that is encoded with uppercase hex characters”, which is the whole contract.
That’s all there is to it. Just a single line of code. That by itself is a big advantage. This method also has the advantage of being part of the core library, so we don’t have to worry about maintaining it or dealing with the implementation details.
For applications targeting .NET 5 or later, this is the recommended method. It does only produce uppercase, but since .NET 9 there is a matching method for the other case:
Convert.ToHexStringLower(source);
Which gives us:
deadbeefdecafbad
Both claims are checkable: the runtime source holds the vectorized encoding path, and the API documentation holds the contract.
On .NET 5 through .NET 8, where Convert.ToHexStringLower() does not exist, calling ToLowerInvariant() on the result works and costs a second string allocation, which on the same 4096-byte benchmark run below takes 2,422 ns against 1,120 ns for Convert.ToHexStringLower(). The lookup table method above avoids that allocation and is the better choice in a hot path.
Which .NET Versions Support Convert.ToHexString()?
Convert.ToHexString() arrived in .NET 5 and is in every release since, .NET 10 included. It accepts a byte[], a ReadOnlySpan<byte>, or an array with an offset and a length, and it always returns uppercase.
Convert.ToHexStringLower() is much newer. It arrived in .NET 9 with the same three overloads and returns lowercase, which removes the reason older code reached for a NuGet package or a hand-written table to get lowercase output.
The reverse direction, Convert.FromHexString(), also arrived in .NET 5.
Neither method exists on .NET Framework 4.8 or .NET Standard 2.0. Microsoft’s documentation lists .NET 5 as the earliest version for both and no .NET Framework version at all, so projects on those targets still need one of the manual methods from this article.
The source repository carries a .NET Standard 2.0 lookup implementation for exactly that case.
| API | Direction | Case | Earliest .NET | .NET Framework 4.8 and .NET Standard 2.0 |
|---|---|---|---|---|
Convert.ToHexString(byte[]), (ReadOnlySpan<byte>), (byte[], int, int) | Bytes to string | Uppercase | .NET 5 | Not available |
Convert.ToHexStringLower(byte[]), (ReadOnlySpan<byte>), (byte[], int, int) | Bytes to string | Lowercase | .NET 9 | Not available |
Convert.FromHexString(string), (ReadOnlySpan<char>) | String to bytes | Accepts either | .NET 5 | Not available |
BitConverter.ToString(byte[]) | Bytes to string | Uppercase, dash separated | Every version | Available |
Lookup table, bit manipulation, StringBuilder (this article) | Bytes to string | Either, our choice | Any | Available |
The reverse trip has an article of its own: converting a hexadecimal string back to a byte array covers Convert.FromHexString() and the manual equivalents for targets that do not have it.
How Fast Is Each Conversion Method?
Now that we have seen several ways to accomplish our goal of converting a byte array into a hexadecimal string, let’s look at some benchmarks. For our benchmarks, we are converting a 4096-byte buffer into a hex string.
Our benchmarks are running on a Windows 10 PC with an AMD Ryzen 5 3600 and 6 physical cores:
BenchmarkDotNet v0.15.8, Windows 10 (10.0.19045.6466/22H2/2022Update)
AMD Ryzen 5 3600 3.60GHz, 1 CPU, 12 logical and 6 physical cores
.NET SDK 10.0.302
  [Host]     : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3
  DefaultJob : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3

| Method                                     | Mean         | Error       | StdDev      | Median       |
|------------------------------------------- |-------------:|------------:|------------:|-------------:|
| ConvertToUpperHexUsingConvert              |  1,085.72 ns |   21.447 ns |   21.064 ns |  1,085.56 ns |
| ConvertToUpperHexUsingLookup               |  2,201.31 ns |   34.261 ns |   43.329 ns |  2,182.98 ns |
| ConvertToUpperHexUsingLookupNetStandard20  |  3,534.46 ns |   70.014 ns |   80.628 ns |  3,501.33 ns |
| ConvertToUpperHexUsingAlphabetSpanLookup   |  4,630.56 ns |   91.291 ns |  200.385 ns |  4,632.44 ns |
| ConvertToUpperHexUsingBitManipulation      |  6,592.61 ns |  123.897 ns |  142.680 ns |  6,591.12 ns |
| ConvertToUpperHexUsingBitConverter         |  8,970.70 ns |  179.289 ns |  366.240 ns |  8,924.14 ns |
| ConvertToUpperHexUsingTryFormatAndCreate   | 48,672.79 ns |  973.146 ns |1,678.630 ns | 48,301.55 ns |
| ConvertToUpperHexUsingStringBuilderAppend  | 61,523.66 ns |1,088.360 ns |  964.802 ns | 61,600.05 ns |
| ConvertToUpperHexUsingBitConverterNoDashes | 82,738.13 ns |1,629.665 ns |1,940.000 ns | 82,297.88 ns |
As we probably expected, the built-in Convert.ToHexString() is the fastest method, and it is the fastest at every input size the project measures, from 32 bytes up to a megabyte. Our lookup table method is a close second at about 2x, and the .NET Standard 2.0 variant of the same idea follows at about 3.3x.
Next up, at about 4.3x, is our conversion using a ReadOnlySpan<byte> created from a UTF8 string. Then comes bit manipulation at about 6x, and the plain BitConverter method at about 8.3x.
The last three rows belong to a different order of magnitude. Our method using TryFormat() and String.Create() is about 45x slower than the built-in, the StringBuilder method about 57x, and stripping the dashes off BitConverter.ToString() is the slowest option on the page at about 76x, roughly 34% slower than the next row up, because String.Replace() allocates a second string on top of the one we just built.
Those bytes have to come from somewhere, and often they arrive as a Stream, so it is worth knowing where the bytes came from, if they arrived on a stream before turning them into something a person can read. The Hex to String Converter shows that same byte-to-text boundary directly: paste the bytes or the text and see the hex on the other side, in UTF-8, UTF-16, ASCII or Latin-1.
Which Method Should We Use?
Convert.ToHexString() for uppercase and Convert.ToHexStringLower() for lowercase. On a supported .NET version there is little reason to write anything else: each is one line, each is maintained by the runtime team, and the benchmarks above put the built-in method ahead of every hand-written option in this article.
The other methods earn their place in two situations. The first is a target the built-in methods do not reach, such as .NET Framework or .NET Standard 2.0, where the lookup table is the fastest of the manual options and the span over an alphabet string is close behind without the extra kilobyte of tables.
The second is a hot path where the string itself is the cost. Every method here allocates a string twice the size of the input, so if that allocation is what hurts, the fix is to write hex into a buffer the caller owns rather than to pick a faster way of building a string.
| Method | Runs on | Case | Choose it when |
|---|---|---|---|
Convert.ToHexString() | .NET 5 and later | Uppercase | Always, unless a row below applies |
Convert.ToHexStringLower() | .NET 9 and later | Lowercase | We need lowercase and we are on .NET 9 or later |
| Lookup table | Any target, including .NET Standard 2.0 | Either | The built-in methods are not available and speed matters |
| Span over an alphabet string | Any target | Either | Same case as above, without the roughly 1 KB of lookup tables |
| Bit manipulation | Any target | Either | Same case again, with no tables at all |
StringBuilder with TryFormat() | Any target | Either | The hex is one part of a larger string we are already building |
BitConverter.ToString() | Any target, including .NET Framework | Uppercase, dash separated | We actually want the DE-AD-BE-EF form |
The method we choose to implement to convert a byte array to a hexadecimal string will depend on many factors. We have to consider where our code will be running. Is it an embedded system with limited resources, or are we running in the server room? We need to think about the size of the data we are expecting to process. Are we converting small 32-byte arrays, or are we processing a stream of data that we have to convert on the fly? All of these things play an important role when choosing which method we are going to use.
Conclusion
In this article, we looked at different ways to convert a byte array to a hexadecimal string. We also conducted benchmarks of each of these methods and discussed some factors that may impact which method we choose to implement.
Tested with .NET 10.0.10.