Updated on
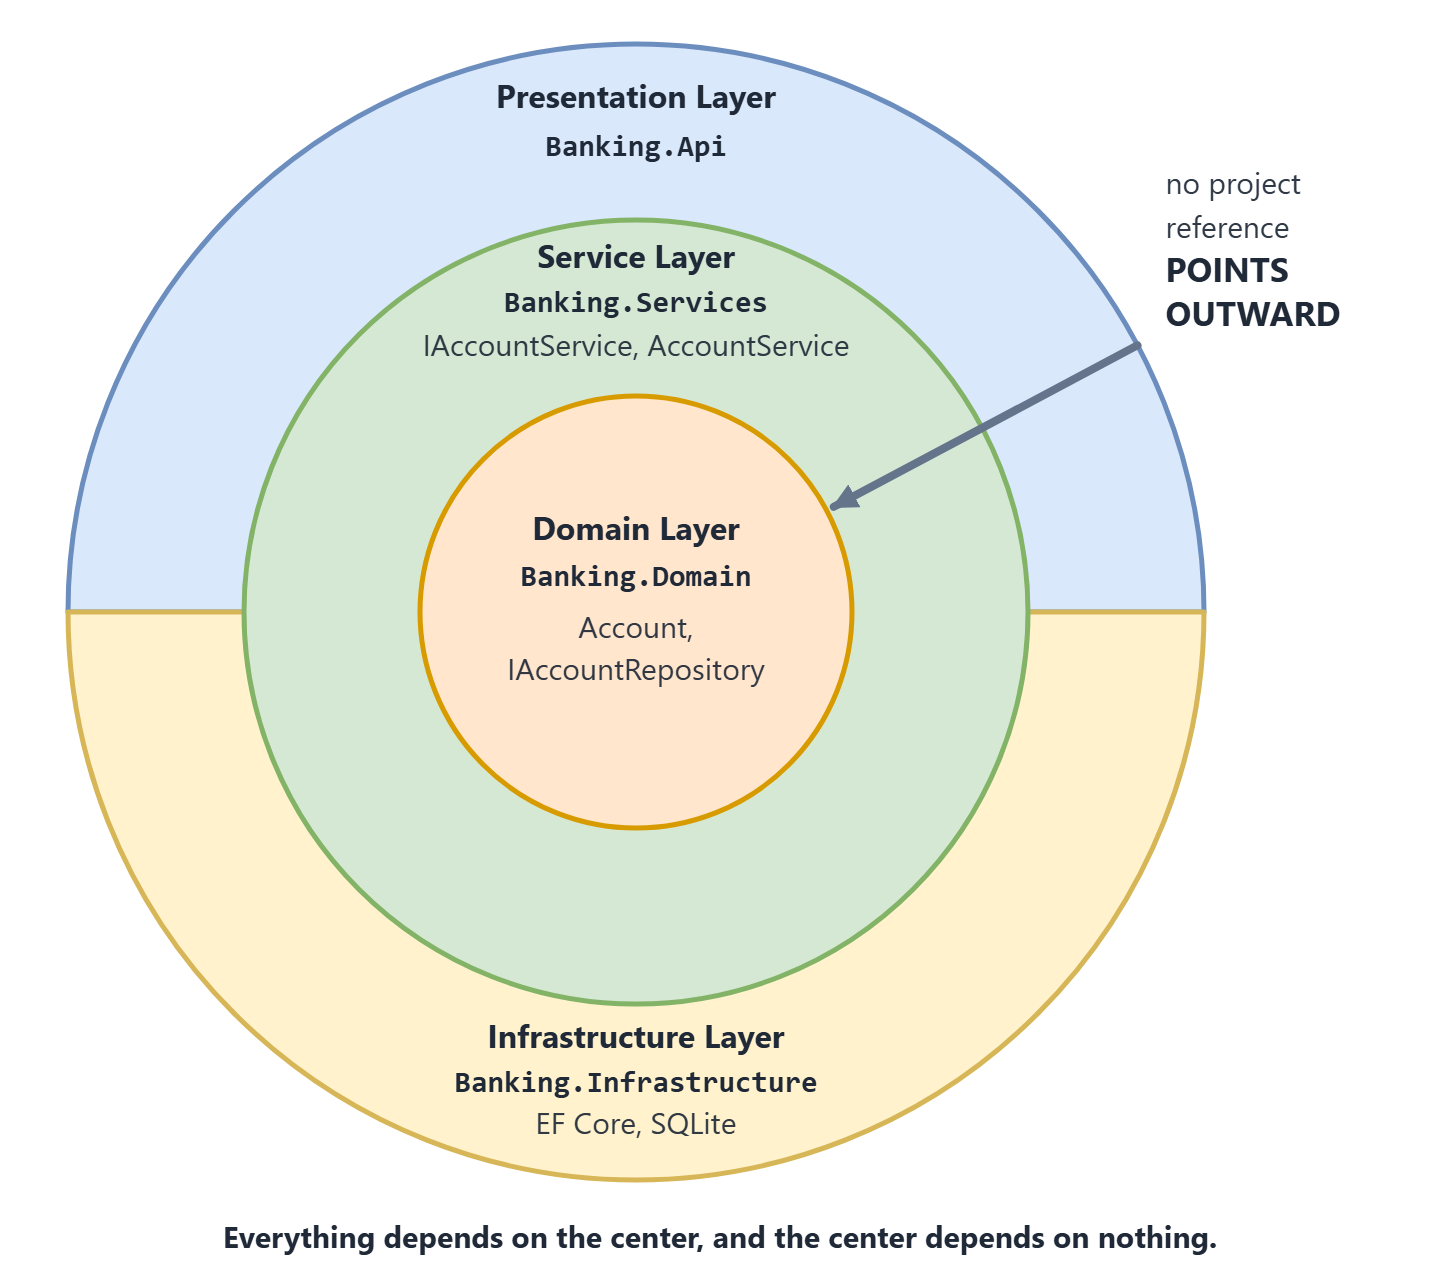
The Onion architecture organizes an application as layers in concentric circles. The domain model sits at the center, and every dependency points inward, toward it.
We will build a RESTful API that follows the Onion architecture, with ASP.NET Core and .NET, and see what its advantages are.
The Onion architecture is closely related to the Clean architecture and to Ports and adapters, also known as the Hexagonal architecture. These architectural approaches are variations of the same theme.
Our Onion vs Clean Architecture comparison puts the first two side by side, and the Hexagonal Architecture article shows ports and adapters in C#.
Let’s get started!
What is the Onion Architecture?
The Onion architecture is a form of layered architecture, and we can visualize these layers as concentric circles. Hence the name Onion architecture. The Onion architecture was first introduced by Jeffrey Palermo in 2008, to overcome the issues of the traditional N-layered architecture approach.
In a traditional N-layered application, the business logic depends on the data access layer. The Onion architecture turns that dependency around. The domain model sits at the center and depends on nothing. The core defines interfaces for what it needs, and the Infrastructure layer on the outside implements them.
The main rule is about direction. Code in any layer can depend on the layers closer to the center, and never on the layers further out.
That way, the database becomes a detail on the edge of our application, and we can test the business logic without it. The price is a few extra projects and interfaces, which pays off in long-lived applications with real business rules.
In his first post on the pattern, The Onion Architecture: part 1, Palermo wrote: “The fundamental rule is that all code can depend on layers more central, but code cannot depend on layers further out from the core.”
There are multiple ways that we can split the onion, but we are going to choose the following approach where we are going to split the architecture into 4 layers:
- Domain Layer
- Service Layer
- Infrastructure Layer
- Presentation Layer
Conceptually, we can consider that the Infrastructure and Presentation layers are on the same level of the hierarchy.
Now, let us go ahead and look at each layer with more detail to see why we are introducing it and what we are going to create inside of that layer:
Advantages of the Onion Architecture
Let us take a look at what are the advantages of Onion architecture, and why we would want to implement it in our projects.
All of the layers interact with each other through the interfaces and types defined in the layers below. The flow of dependencies is towards the core of the Onion. We will explain why this is important in the next section.
Using dependency inversion throughout the project, depending on abstractions (interfaces) and not the implementations, allows us to switch out the implementation at runtime transparently. We are depending on abstractions at compile-time, which gives us strict contracts to work with, and we are being provided with the implementation at runtime.
Testability is very high with the Onion architecture because the core depends on abstractions. The abstractions can be easily mocked with a mocking library such as NSubstitute, or replaced with a small hand-written fake, as we’ll do later in this article.
We can write business logic without concern about any of the implementation details. If we need anything from an external system or service, we can just create an interface for it and consume it. We do not have to worry about how it will be implemented. The higher layers of the Onion will take care of implementing that interface transparently.
These advantages aren’t free, though. We pay for them with extra projects and interfaces, and Palermo said so himself in that first post: “This architecture is not appropriate for small websites.”
For a small CRUD application, Vertical Slice Architecture is often a better fit, because it keeps a feature’s code together instead of spreading it over several projects.
Flow of Dependencies
The main idea behind the Onion architecture is the flow of dependencies, or rather how the layers interact with each other. The deeper the layer resides inside the Onion, the fewer dependencies it has.
The Domain layer does not have any direct dependencies on the outside layers. It is isolated, in a way, from the outside world. The outer layers are all allowed to reference the layers that are below them in the hierarchy.
We can conclude that all the dependencies in the Onion architecture flow inwards. But we should ask ourselves, why is this important?
The flow of dependencies dictates what a certain layer in the Onion architecture can do. Because it depends on the layers below it in the hierarchy, it can only call the methods that are exposed by the lower layers.
We can use lower layers of the Onion architecture to define contracts or interfaces. The outer layers of the architecture implement these interfaces. This means that in the Domain layer, we are not concerning ourselves with infrastructure details such as the database or external services.
Using this approach, we can encapsulate all of the rich business logic in the Domain and Service layers without ever having to know any implementation details. In the Service layer, we are going to depend only on the layer below, which is the Domain layer.
Enough theory, let us see some code. We are going to build a small bank account API from an empty folder, one project at a time, and talk about how each project fits into the Onion architecture.
Our API has one entity, Account, and one business rule: an account can’t be overdrawn. It exposes two endpoints, one that returns an account and one that withdraws money from it.
Solution Structure
The steps below assume the .NET 10 SDK, since they use its noun-first commands, such as dotnet reference add.
Older SDKs use dotnet sln add, dotnet add reference and dotnet add package instead.
Let’s start by creating the solution structure we are going to be using:
dotnet new sln -n Banking
dotnet new classlib -n Banking.Domain
dotnet new classlib -n Banking.Services
dotnet new classlib -n Banking.Infrastructure
dotnet new web -n Banking.Api
dotnet solution add Banking.Domain Banking.Services Banking.Infrastructure Banking.Api
As we can see, it consists of the Banking.Api project, which is our ASP.NET Core application, and three class libraries. The Banking.Domain project will hold the Domain layer implementation. The Banking.Services project is going to be our Service layer implementation. The Banking.Infrastructure project will be our Infrastructure layer, and the Banking.Api project will be the Presentation layer implementation.
Each class library starts with a placeholder Class1.cs file. We don’t need them, so let’s delete all three.
You’ll also notice Banking.slnx. That’s the XML solution format the .NET 10 SDK creates by default.
Project references decide which layer can see which. These three commands set up our flow of dependencies:
dotnet reference add Banking.Domain --project Banking.Services
dotnet reference add Banking.Domain --project Banking.Infrastructure
dotnet reference add Banking.Services Banking.Infrastructure --project Banking.Api
Both Services and Infrastructure point at Domain, the API points at those two, and Domain points at nothing:
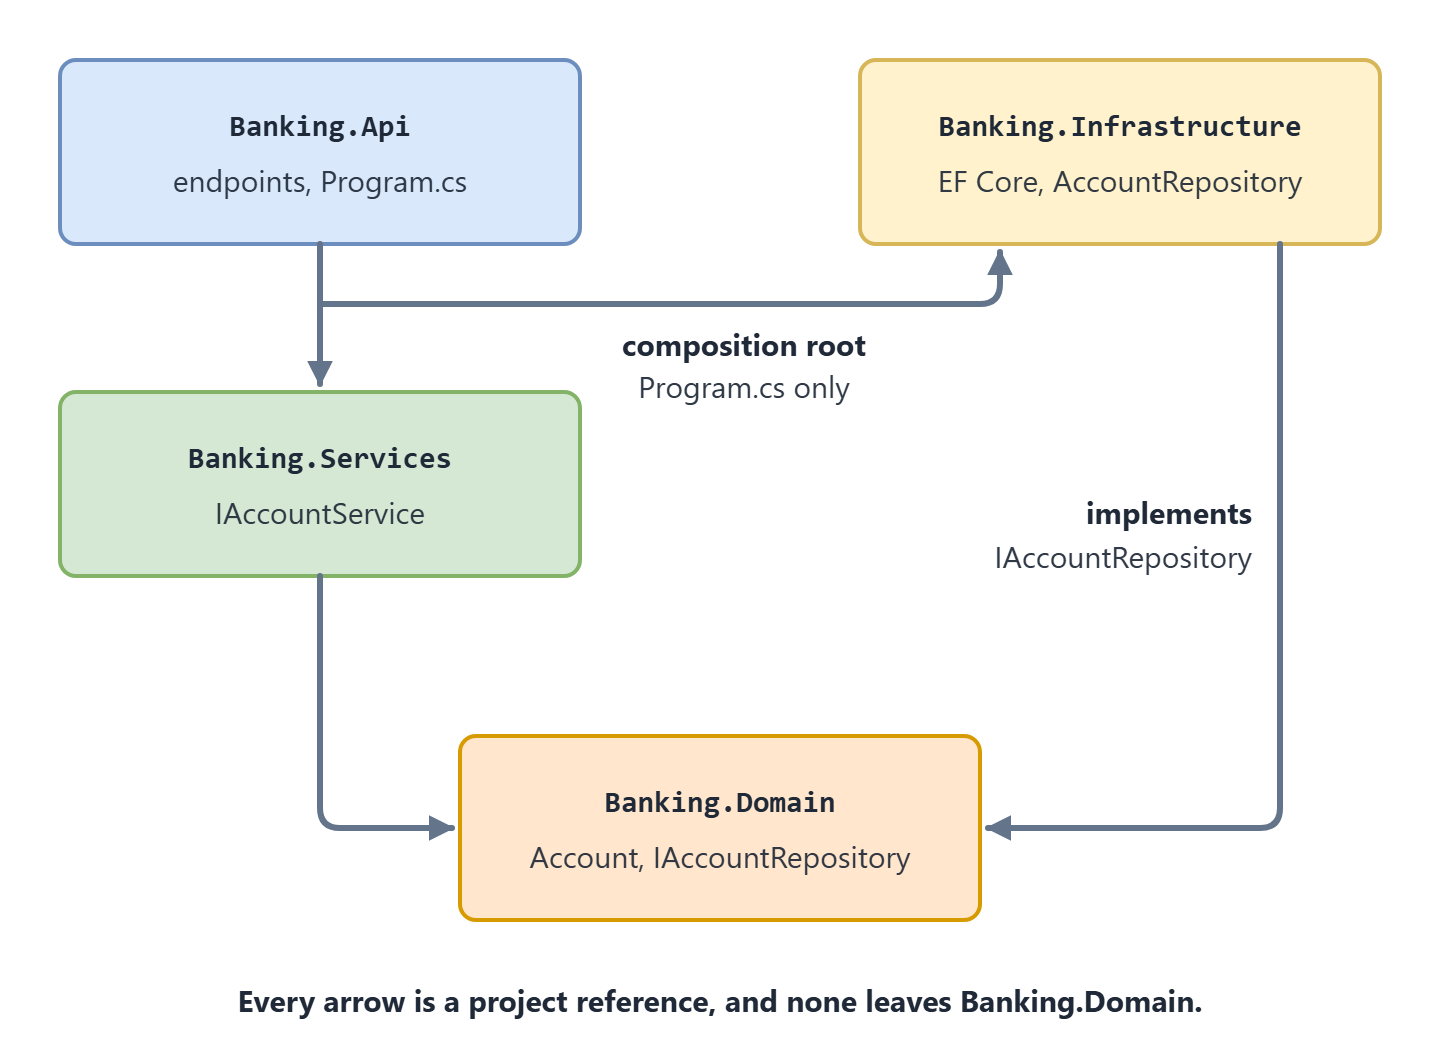
Why doesn’t Infrastructure reference Services? It doesn’t need anything from there. The interface it implements, IAccountRepository, lives in the Domain, next to the entity it loads and saves.
And isn’t the API reaching past the core when it references Infrastructure? It is, but only for one file. Program.cs has to register the EF Core classes behind the Domain’s interface, and that makes it the composition root: the single spot where every layer gets wired up. We’ll come back to this in the Presentation layer.
Finally, two projects get a package each:
dotnet package add Microsoft.Extensions.DependencyInjection.Abstractions --version 10.0.12 --project Banking.Services
dotnet package add Microsoft.EntityFrameworkCore.Sqlite --version 10.0.12 --project Banking.Infrastructure
The Services project only needs the dependency injection abstractions for its registration method. EF Core lands in Infrastructure, the one project that implements data access. We pin the versions to the ones this article was tested with.
Domain Layer
The Domain layer is at the core of the Onion architecture. In this layer, we are typically going to define the core aspects of our domain:
- Entities
- Repository interfaces
- Errors
- Domain services
These are just some of the examples of what we could define in the Domain layer. We can be more or less strict, depending on our needs. We have to realize that everything is a tradeoff in software engineering.
Let’s start by looking at the Account entity class. Create Banking.Domain/Account.cs:
namespace Banking.Domain;

public sealed class Account
{
    private Account(string owner, decimal balance)
    {
        Owner = owner;
        Balance = balance;
    }

    public int Id { get; private set; }
    public string Owner { get; private set; }
    public decimal Balance { get; private set; }

    public static Account Open(string owner, decimal initialDeposit)
    {
        ArgumentException.ThrowIfNullOrWhiteSpace(owner);
        ArgumentOutOfRangeException.ThrowIfNegative(initialDeposit);

        return new Account(owner, initialDeposit);
    }

    public Result Withdraw(decimal amount)
    {
        ArgumentOutOfRangeException.ThrowIfNegativeOrZero(amount);

        if (amount > Balance)
            return AccountErrors.InsufficientFunds(Id);

        Balance -= amount;

        return Result.Success();
    }
}
The entities defined in the Domain layer are going to capture the information that is important for describing the problem domain.
At this point, we should ask ourselves what about the behavior? Isn’t an anemic domain model a bad thing?
It depends. If you have complex business logic, it makes sense to encapsulate it inside of our domain entities. Our Account has only one rule, but that rule is the reason the application exists, so it lives inside the entity. All three setters are private, and money leaves the account only through Withdraw().
For many applications, it is usually easier to start with a simpler domain model, and only introduce complexity if it is required by the project.
Withdraw() returns a Result and uses AccountErrors. These are two small types we are going to create in the Domain Errors section below, so the project won’t build until they’re in place.
Next, the Domain needs a way to load and save an account without knowing anything about the database. So we define an interface for it. Create Banking.Domain/IAccountRepository.cs:
namespace Banking.Domain;

public interface IAccountRepository
{
    Task<Account?> GetByIdAsync(int accountId, CancellationToken cancellationToken = default);

    Task SaveChangesAsync(CancellationToken cancellationToken = default);
}
Palermo placed repository interfaces right here, in the first layer around the domain model, and the class that talks to the database out on the edge. Clean Architecture projects often move these interfaces one layer out. Both placements keep the rule intact.
There’s no separate IUnitOfWork interface in our Domain. SaveChangesAsync() sits on the repository, which is fine while each operation works with one repository. Once an operation writes through two, say accounts and an audit log, the save needs its own interface, and the unit of work pattern provides one.
Notice that we are setting the CancellationToken argument as an optional value, and giving it the default value. With this approach, if we don’t provide an actual CancellationToken value a CancellationToken.None will be provided for us. By doing this, we can ensure that our asynchronous calls that use the CancellationToken will always work.
Domain Errors
A withdrawal bigger than the balance isn’t a bug. Our customers will try it every day, and turning them down is the system working correctly.
If we threw an exception for it, we’d treat it like a crash. So our Domain returns a result that describes the failure, and we keep exceptions for bugs. Create Banking.Domain/Result.cs:
namespace Banking.Domain;

public enum ErrorType
{
    NotFound,
    Conflict
}

public sealed record Error(string Code, string Description, ErrorType Type);

public class Result
{
    protected Result(Error? error) => Error = error;

    public Error? Error { get; }
    public bool IsSuccess => Error is null;

    public static Result Success() => new(null);

    public static implicit operator Result(Error error) => new(error);
}

public sealed class Result<TValue> : Result
{
    private readonly TValue? _value;

    private Result(TValue? value, Error? error)
        : base(error) => _value = value;

    public TValue Value => IsSuccess
        ? _value!
        : throw new InvalidOperationException("A failed result has no value.");

    public static implicit operator Result<TValue>(TValue value) =>
        new(value, null);

    public static implicit operator Result<TValue>(Error error) =>
        new(default, error);
}
An Error carries a code, a readable description and a type. Later, the Presentation layer turns the type into an HTTP status code, and the Domain stays unaware of what a 404 is.
A successful Result has no Error, and a failed one has exactly one. Result<TValue> also holds the value of a success. We read Value only after checking IsSuccess, because a failed result throws.
Thanks to the implicit operators, a method that returns a Result<TValue> can return a value or an Error directly, and the conversion happens on its own.
There are also a couple of errors that describe specific scenarios that can occur in the application. Create Banking.Domain/AccountErrors.cs:
namespace Banking.Domain;

public static class AccountErrors
{
    public static Error NotFound(int accountId) =>
        new("Account.NotFound", $"Account {accountId} was not found.", ErrorType.NotFound);

    public static Error InsufficientFunds(int accountId) =>
        new("Account.InsufficientFunds", $"Account {accountId} doesn't have enough money for this withdrawal.", ErrorType.Conflict);
}
The code, such as Account.InsufficientFunds, is meant for programs and stays stable. The description is meant for people and may be reworded, so your client code should branch on the code.
Now Withdraw() makes sense. It refuses in two different ways. A zero or negative amount means the caller has a bug, so ThrowIfNegativeOrZero() throws. Asking for more than the balance is a normal customer mistake, so the method returns AccountErrors.InsufficientFunds and leaves the balance alone.
These errors will be handled by the higher layers of our architecture. We are going to use them in the Presentation layer, which will return the proper HTTP status code based on the type of error that was returned.
If you prefer exceptions, that works too. Many Onion samples throw exceptions such as AccountNotFoundException, and a global exception handler turns them into status codes.
We prefer results because an expected failure then shows up in the method’s signature, where we and the compiler can both see it. Our Result pattern article goes deeper into the pattern.
At this point, we know how to define the Domain layer. That said, we can move on to the Service layer and see how to use it to implement the operations of our application.
Service Layer
The Service layer sits right above the Domain layer, which means that it has a reference to the Domain layer. We keep the whole Service layer in one project, Banking.Services.
In it, we define the service interface that is going to encapsulate the operations on an account, and the Data Transfer Object (DTO) that we are going to consume with it.
Let’s first look at the IAccountService interface. Create Banking.Services/IAccountService.cs:
using Banking.Domain;

namespace Banking.Services;

public sealed record AccountDto(int Id, string Owner, decimal Balance);

public interface IAccountService
{
    Task<Result<AccountDto>> GetByIdAsync(int accountId, CancellationToken cancellationToken = default);

    Task<Result<AccountDto>> WithdrawAsync(int accountId, decimal amount, CancellationToken cancellationToken = default);
}
AccountDto is what the outside world sees of an account. Our endpoints return this record and never the Account entity, so the JSON stays the same when the entity changes.
Next, we are going to implement this interface inside of the Services project. Create Banking.Services/AccountService.cs:
using Banking.Domain;

namespace Banking.Services;

internal sealed class AccountService(IAccountRepository accounts) : IAccountService
{
    public async Task<Result<AccountDto>> GetByIdAsync(
        int accountId, CancellationToken cancellationToken = default)
    {
        var account = await accounts.GetByIdAsync(accountId, cancellationToken);
        if (account is null)
            return AccountErrors.NotFound(accountId);

        return ToDto(account);
    }

    public async Task<Result<AccountDto>> WithdrawAsync(
        int accountId, decimal amount, CancellationToken cancellationToken = default)
    {
        var account = await accounts.GetByIdAsync(accountId, cancellationToken);
        if (account is null)
            return AccountErrors.NotFound(accountId);

        var withdrawal = account.Withdraw(amount);
        if (!withdrawal.IsSuccess)
            return withdrawal.Error!;

        await accounts.SaveChangesAsync(cancellationToken);

        return ToDto(account);
    }

    private static AccountDto ToDto(Account account) =>
        new(account.Id, account.Owner, account.Balance);
}
WithdrawAsync() starts by fetching the account through the repository interface. An unknown ID ends right there, with Account.NotFound.
Then the account decides. If it refuses, the service hands that error back as it is. It saves only after a successful withdrawal, and it returns an AccountDto built by hand.
Can you spot the balance check in the service? There isn’t one. Account makes that call, and the service runs the steps in order.
What happens when the bank adds deposits? We add a Deposit() method to Account and a DepositAsync() method to this service. That’s how an Onion application grows: a new operation is a new method on an existing service.
And finally, the service registration, which stays inside the project too. Create Banking.Services/DependencyInjection.cs:
using Microsoft.Extensions.DependencyInjection;

namespace Banking.Services;

public static class DependencyInjection
{
    public static IServiceCollection AddServices(this IServiceCollection services)
    {
        services.AddScoped<IAccountService, AccountService>();

        return services;
    }
}
The API will call AddServices() and never learn which class implements IAccountService.
What is the motivation for splitting the Service layer?
Why are we going through so much trouble to split our service interface from its implementation?
As you can see, we mark the service implementation with the internal keyword, which means it will not be publicly available outside of the Services project. On the other hand, the service interface is public.
Do you remember what we said about the flow of dependencies?
With this approach, we are being very explicit about what the higher layers of the Onion can and can not do. They get IAccountService, and AddServices() decides what stands behind it.
This means that when a higher layer references the Services project, it will only be able to reach the service through the methods that IAccountService exposes. We are going to see why this is very useful later on when we get to the Presentation layer.
Many Onion solutions go a step further and move the service interfaces into a separate Services.Abstractions project, and the endpoints into a Presentation project that references only that one. Then the compiler stops the endpoints from using Infrastructure, but it costs two more projects, and later in this article we’ll get the same guarantee from one test.
Infrastructure Layer
The Infrastructure layer should be concerned with encapsulating anything related to external systems or services that our application is interacting with. These external services can be:
- Database
- Identity provider
- Messaging queue
- Email service
There are more examples, but hopefully, you get the idea. We are hiding all the implementation details in the Infrastructure layer because it is at the top of the Onion architecture, while all of the lower layers depend on the interfaces (abstractions).
First, we are going to create the Entity Framework database context, the BankingDbContext class. Create Banking.Infrastructure/BankingDbContext.cs:
using Banking.Domain;
using Microsoft.EntityFrameworkCore;

namespace Banking.Infrastructure;

public sealed class BankingDbContext(DbContextOptions<BankingDbContext> options)
    : DbContext(options)
{
    public DbSet<Account> Accounts => Set<Account>();

    protected override void OnModelCreating(ModelBuilder modelBuilder)
    {
        modelBuilder.Entity<Account>(builder =>
        {
            builder.Property(a => a.Owner).HasMaxLength(100);

            builder.HasData(
                new { Id = 1, Owner = "Anna Smith", Balance = 100m },
                new { Id = 2, Owner = "Mark Jones", Balance = 20m });
        });
    }
}
As you can see, the implementation is extremely simple. In the OnModelCreating() method, we configure the Account entity and seed the two accounts our requests will use: Anna Smith, who has 100, and Mark Jones, who has 20.
There isn’t a single EF Core attribute on Account, so the Domain has no idea how it’s stored. EF Core copes with the private constructor and the private setters, so we don’t give up encapsulation to use it.
Great, now that the database context is configured, we can move on to the repository.
The repository implements the interface that we defined in the Domain project. Create Banking.Infrastructure/AccountRepository.cs:
using Banking.Domain;
using Microsoft.EntityFrameworkCore;

namespace Banking.Infrastructure;

internal sealed class AccountRepository(BankingDbContext dbContext) : IAccountRepository
{
    public Task<Account?> GetByIdAsync(int accountId, CancellationToken cancellationToken = default) =>
        dbContext.Accounts.FirstOrDefaultAsync(a => a.Id == accountId, cancellationToken);

    public Task SaveChangesAsync(CancellationToken cancellationToken = default) =>
        dbContext.SaveChangesAsync(cancellationToken);
}
The class stays internal, like AccountService. Because GetByIdAsync() returns a tracked entity, EF Core sees the new balance after Withdraw(), and SaveChangesAsync() turns it into a single UPDATE.
Do we need a generic IRepository<T> as well? We don’t think so. Microsoft’s DbContext reference describes DbContext as the repository and unit of work patterns rolled into one, so a generic wrapper would mostly re-expose DbSet<T>.
Like the Service layer, the Infrastructure layer registers its own classes. Create Banking.Infrastructure/DependencyInjection.cs:
using Banking.Domain;
using Microsoft.EntityFrameworkCore;
using Microsoft.Extensions.DependencyInjection;

namespace Banking.Infrastructure;

public static class DependencyInjection
{
    public static IServiceCollection AddInfrastructure(
        this IServiceCollection services, string connectionString)
    {
        services.AddDbContext<BankingDbContext>(options => options.UseSqlite(connectionString));
        services.AddScoped<IAccountRepository, AccountRepository>();

        return services;
    }
}
AddInfrastructure() receives the connection string from its caller. Where the string is stored is the host’s business, and Infrastructure doesn’t need to know.
Great, we are done with the Infrastructure layer. Now we only have one more layer left to complete our Onion architecture implementation.
Presentation Layer
The purpose of the Presentation layer is to represent the entry point to our system so that consumers can interact with the data. We can implement this layer in many ways, for example creating a REST API, gRPC, etc.
We are using a Web API built with ASP.NET Core to create a set of RESTful API endpoints for modifying the domain entities and allowing consumers to get back the data.
By convention, the endpoints are defined inside of the Web application project, and ours are no different.
Why is this a problem? Because ASP.NET Core uses Dependency Injection everywhere, we need to have a reference to all of the projects in the solution from the Web application project. This allows us to configure our services inside of the Program class.
While this is exactly what we want to do, it introduces a big design flaw. What is preventing our endpoints from injecting anything they want, like the BankingDbContext? Nothing!
Clean Endpoints
With the standard ASP.NET Core approach, we can’t prevent anyone from injecting whatever they need inside an endpoint. So how can we impose some more strict rules about what the endpoints can do?
Do you remember how we split the service interface from its internal implementation? That was one piece of the puzzle. The other piece is an architecture test, and we’ll write it once the application runs.
For now, let’s create the endpoints. Create Banking.Api/AccountEndpoints.cs:
using System.ComponentModel.DataAnnotations;
using Banking.Services;

namespace Banking.Api;

public sealed record WithdrawRequest([property: Range(typeof(decimal), "1", "1000")] decimal Amount);

public static class AccountEndpoints
{
    public static void MapAccountEndpoints(this IEndpointRouteBuilder app)
    {
        var accounts = app.MapGroup("/api/accounts");

        accounts.MapGet("/{accountId:int}", async (
            int accountId,
            IAccountService service,
            CancellationToken cancellationToken) =>
        {
            var result = await service.GetByIdAsync(accountId, cancellationToken);

            return result.IsSuccess ? Results.Ok(result.Value) : result.ToProblem();
        });

        accounts.MapPost("/{accountId:int}/withdrawals", async (
            int accountId,
            WithdrawRequest request,
            IAccountService service,
            CancellationToken cancellationToken) =>
        {
            var result = await service.WithdrawAsync(accountId, request.Amount, cancellationToken);

            return result.IsSuccess ? Results.Ok(result.Value) : result.ToProblem();
        });
    }
}
Both endpoints do the same thing. They call one service method, return 200 with the DTO on success, and hand a failure to ToProblem(), an extension method we’re going to write in a moment.
WithdrawRequest describes the HTTP body. Its [Range] attribute accepts 1 to 1,000 per withdrawal, and the typeof(decimal) form makes it compare amounts as decimals, so 0.99 and 1000.01 are both rejected.
By now it should be obvious that our endpoints only talk to IAccountService. That’s a strict set of methods, but for now only by convention. The compiler would still let an endpoint take the BankingDbContext.
The obvious advantage of the Onion architecture is that our endpoints become very thin. Just a couple of lines of code at most. This is the true beauty of the Onion architecture. We moved all of the important business logic into the Domain and Service layers.
We wrote the endpoints as minimal APIs, which Microsoft’s APIs overview recommends for new projects. Prefer controllers? They would live in the same layer, and the core wouldn’t notice the difference.
Great, we have seen how to implement the Presentation layer.
But how is the application going to find our endpoints and services? Well, let us move on to the next section to find out.
Constructing the Onion
Congratulations if you made it this far. We’ve shown you how to implement the Domain layer, Service layer, and Infrastructure layer. Also, we’ve shown you the Presentation layer implementation, with thin endpoints that only talk to the Service layer.
There is only one little problem remaining. The application does not work at all! We did not see how to wire up any of our dependencies.
Configuring the Services
Let’s look at how all of the required service dependencies are registered inside of the Program class in the Banking.Api project. Replace Banking.Api/Program.cs with:
using Banking.Api;
using Banking.Infrastructure;
using Banking.Services;

var builder = WebApplication.CreateBuilder(args);

builder.Services.AddServices();
builder.Services.AddInfrastructure(builder.Configuration.GetConnectionString("Banking")!);

builder.Services.AddProblemDetails();
builder.Services.AddValidation();

var app = builder.Build();

app.UseExceptionHandler();

using (var scope = app.Services.CreateScope())
{
    var dbContext = scope.ServiceProvider.GetRequiredService<BankingDbContext>();
    dbContext.Database.EnsureCreated();
}

app.MapAccountEndpoints();

app.Run();
The most important part of the code is:
builder.Services.AddServices();
builder.Services.AddInfrastructure(builder.Configuration.GetConnectionString("Banking")!);
Without these two lines of code, the Web API would not work, because nothing would know which classes stand behind IAccountService and IAccountRepository. Each call pulls in one project’s registrations, so this file knows about every layer, and no other file has to.
Our ASP.NET Core dependency injection guide explains the registrations behind these calls.
Minimal APIs gained built-in validation in .NET 10, and AddValidation() turns it on, so the [Range] attribute on WithdrawRequest gets checked. MapAccountEndpoints() maps the endpoints we wrote in the Presentation layer.
Program.cs reads the connection string named Banking from the configuration and hands it to AddInfrastructure(), so let’s add it. Replace Banking.Api/appsettings.json with:
{
  "ConnectionStrings": {
    "Banking": "Data Source=banking.db"
  },
  "Logging": {
    "LogLevel": {
      "Default": "Information",
      "Microsoft.AspNetCore": "Warning"
    }
  },
  "AllowedHosts": "*"
}
Great, we saw how we wired up all of the dependencies of our application. However, there are still a couple of things to take care of.
Handling Errors and Exceptions
Remember that we have the ErrorType enum, with NotFound and Conflict, inside of the Domain layer? Let’s see how we can make good use of it.
We are going to write the ToProblem() extension method, which turns a failed Result into an HTTP response. Create Banking.Api/ResultExtensions.cs:
using Banking.Domain;

namespace Banking.Api;

public static class ResultExtensions
{
    public static IResult ToProblem(this Result result)
    {
        var error = result.Error
            ?? throw new InvalidOperationException("A successful result is not a problem.");

        var statusCode = error.Type switch
        {
            ErrorType.NotFound => StatusCodes.Status404NotFound,
            ErrorType.Conflict => StatusCodes.Status409Conflict,
            _ => StatusCodes.Status500InternalServerError
        };

        return TypedResults.Problem(statusCode: statusCode, title: error.Code, detail: error.Description);
    }
}
Notice that we create a switch expression around the error type and then perform a pattern matching based on it. Then, we are picking the response HTTP status code depending on what the specific error type is.
This is the only place where an ErrorType becomes a status code. The core talks about missing accounts and conflicts, and the Presentation layer decides that those mean 404 and 409.
TypedResults.Problem() answers in the problem details format that HTTP APIs use for errors, with our error code as the title. ProblemDetails in ASP.NET Core explains every field of that body.
That covers the errors we expect. For the ones we don’t, like a bug that throws, we use the global exception handler that ASP.NET Core already has. These two lines in Program.cs turn it on:
builder.Services.AddProblemDetails();

app.UseExceptionHandler();
With both in place, an unhandled exception comes back as a 500, in the same problem details format as our own errors. We don’t have to write any middleware for it.
Taking Care of the Database
We are going to look at one last improvement to the project, which makes it easier to use for everyone, and then we are done.
To make it straightforward to download the application code and be able to run the application locally, we are using SQLite. SQLite keeps the whole database in one file. That way, we won’t need to have a database server installed on our system.
However, how are we going to create the actual database for the application to use?
We could create an initialization script and execute it by hand. But this is a lot of manual work, and it is error-prone. Luckily, there is a better way.
To do this elegantly, we are going to let EF Core create the database from our code when the application starts. To see how we achieved this, take a look at these lines in the Program class:
using (var scope = app.Services.CreateScope())
{
    var dbContext = scope.ServiceProvider.GetRequiredService<BankingDbContext>();
    dbContext.Database.EnsureCreated();
}
The great thing about this approach is that EnsureCreated() builds the database and seeds it the first time the application starts. We do not have to think about it going forward.
It’s a demo shortcut, though. In production, we’d evolve the schema with migrations instead. To learn more about migrations and how to seed data, check out our article on EF Core migrations.
Running the Application
Amazing job! We have connected all of our Onion architecture implementation layers, and our application is now ready for use.
We can start the application from the solution folder. This command pins the API to port 5000, which our requests expect:
dotnet run --project Banking.Api -- --urls http://localhost:5000
Requests will work as soon as the console reports Now listening on: http://localhost:5000.
On that first start, EnsureCreated() writes Banking.Api/banking.db with Anna’s and Mark’s accounts. Deleting the file while the app is stopped gives you fresh balances.
Now we can test out our API endpoints and check if everything is working properly. Visual Studio and Rider can run the five requests below from an .http file without add-ons, and the REST Client extension adds the same to VS Code. Create Banking.Api/Banking.Api.http:
GET http://localhost:5000/api/accounts/1

###

POST http://localhost:5000/api/accounts/1/withdrawals
Content-Type: application/json

{ "amount": 30 }

###

POST http://localhost:5000/api/accounts/2/withdrawals
Content-Type: application/json

{ "amount": 50 }

###

POST http://localhost:5000/api/accounts/1/withdrawals
Content-Type: application/json

{ "amount": 0 }

###

GET http://localhost:5000/api/accounts/99
The first request reads Anna’s account:
{"id":1,"owner":"Anna Smith","balance":100.0}
Why 100.0 and not 100? SQLite has no decimal type, so EF Core stores the balance as text. The seed went in as '100.0', and that’s what comes back.
Withdrawing 30 returns the new balance:
{"id":1,"owner":"Anna Smith","balance":70.0}
Mark has 20, so asking his account for 50 breaks the rule. The API answers 409 Conflict, in the problem details format:
{
  "type": "https://tools.ietf.org/html/rfc9110#section-15.5.10",
  "title": "Account.InsufficientFunds",
  "status": 409,
  "detail": "Account 2 doesn't have enough money for this withdrawal.",
  "traceId": "00-db25fb61f96fd9ddb2b745cfa9a14d7f-f94d89bc50637b5d-00"
}
That refusal started in Account.Withdraw() and reached the endpoint as an ordinary return value, passing through the service untouched. No exception was thrown along the way, and EF Core’s log for this request shows one SELECT and no UPDATE.
A withdrawal of 0 doesn’t get that far. The [Range] check turns it away with a 400 before the endpoint runs:
{
  "type": "https://tools.ietf.org/html/rfc9110#section-15.5.1",
  "title": "One or more validation errors occurred.",
  "status": 400,
  "errors": {
    "Amount": [
      "The field Amount must be between 1 and 1000."
    ]
  },
  "traceId": "00-1c896064c9118396ad2f15f2a1ea022e-ffb5ca8ce2ad8b34-00"
}
Finally, account 99 doesn’t exist, which the service reports as Account.NotFound and the API as a 404:
{
  "type": "https://tools.ietf.org/html/rfc9110#section-15.5.5",
  "title": "Account.NotFound",
  "status": 404,
  "detail": "Account 99 was not found.",
  "traceId": "00-3720b229336004fb467b8f140ad65dac-90ae76f1a1c85453-00"
}
Everything works as expected. Next, let’s make sure the layers stay the way we built them.
Testing the Onion Architecture
Remember how we said that testability is very high with the Onion architecture? Palermo made it one of the tenets of the pattern: all the application core code can be compiled and run separately from the infrastructure.
Let’s check if ours can.
Testing the Core Without a Database
We need a test project:
dotnet new classlib -n Banking.UnitTests
dotnet solution add Banking.UnitTests
Nothing here needs Class1.cs, so delete it. The project file needs the test packages and a reference to Services, so replace Banking.UnitTests/Banking.UnitTests.csproj with:
<Project Sdk="Microsoft.NET.Sdk">

  <PropertyGroup>
    <TargetFramework>net10.0</TargetFramework>
    <ImplicitUsings>enable</ImplicitUsings>
    <Nullable>enable</Nullable>
    <IsPackable>false</IsPackable>
    <IsTestProject>true</IsTestProject>
  </PropertyGroup>

  <ItemGroup>
    <Using Include="Xunit" />
  </ItemGroup>

  <ItemGroup>
    <PackageReference Include="Microsoft.NET.Test.Sdk" Version="18.10.1" />
    <PackageReference Include="xunit.v3.mtp-off" Version="4.0.1" />
    <PackageReference Include="xunit.runner.visualstudio" Version="4.0.0" />
  </ItemGroup>

  <ItemGroup>
    <ProjectReference Include="..\Banking.Services\Banking.Services.csproj" />
  </ItemGroup>

</Project>
Its only project reference is Banking.Services, and the Domain comes along with it. Infrastructure, EF Core and ASP.NET Core are nowhere in sight.
We pick xunit.v3.mtp-off so xUnit v3 runs on the classic VSTest runner, which lets a plain dotnet test in the solution folder run the tests without any configuration.
AccountService is internal, so the test project needs permission to see it. Replace Banking.Services/Banking.Services.csproj with:
<Project Sdk="Microsoft.NET.Sdk">

  <ItemGroup>
    <ProjectReference Include="..\Banking.Domain\Banking.Domain.csproj" />
  </ItemGroup>

  <ItemGroup>
    <PackageReference Include="Microsoft.Extensions.DependencyInjection.Abstractions" Version="10.0.12" />
  </ItemGroup>

  <ItemGroup>
    <InternalsVisibleTo Include="Banking.UnitTests" />
  </ItemGroup>

  <PropertyGroup>
    <TargetFramework>net10.0</TargetFramework>
    <ImplicitUsings>enable</ImplicitUsings>
    <Nullable>enable</Nullable>
  </PropertyGroup>

</Project>
The InternalsVisibleTo item opens the project’s internals to one assembly, our tests, and to nothing else.
The domain tests only need Account. Create Banking.UnitTests/AccountTests.cs:
using Banking.Domain;

namespace Banking.UnitTests;

public class AccountTests
{
    [Fact]
    public void Withdraw_WhenTheBalanceCoversIt_TakesTheMoney()
    {
        var account = Account.Open("Anna Smith", initialDeposit: 100m);

        var result = account.Withdraw(30m);

        Assert.True(result.IsSuccess);
        Assert.Equal(70m, account.Balance);
    }

    [Fact]
    public void Withdraw_WhenTheBalanceIsTooLow_ReturnsAnErrorAndKeepsTheMoney()
    {
        var account = Account.Open("Mark Jones", initialDeposit: 20m);

        var result = account.Withdraw(50m);

        Assert.False(result.IsSuccess);
        Assert.Equal("Account.InsufficientFunds", result.Error!.Code);
        Assert.Equal(20m, account.Balance);
    }
}
Each test opens an account and calls Withdraw(), with no database and no setup code.
For the service, we replace the repository with a fake: a hand-written class that implements IAccountRepository in a few lines. Create Banking.UnitTests/AccountServiceTests.cs:
using Banking.Domain;
using Banking.Services;

namespace Banking.UnitTests;

public class AccountServiceTests
{
    [Fact]
    public async Task WithdrawAsync_WhenTheBalanceCoversIt_SavesOnce()
    {
        var accounts = new FakeAccountRepository(Account.Open("Anna Smith", initialDeposit: 100m));
        var service = new AccountService(accounts);

        var result = await service.WithdrawAsync(
            accountId: 1, amount: 30m, TestContext.Current.CancellationToken);

        Assert.True(result.IsSuccess);
        Assert.Equal(70m, result.Value.Balance);
        Assert.Equal(1, accounts.SaveCount);
    }

    [Fact]
    public async Task WithdrawAsync_WhenTheBalanceIsTooLow_SavesNothing()
    {
        var accounts = new FakeAccountRepository(Account.Open("Mark Jones", initialDeposit: 20m));
        var service = new AccountService(accounts);

        var result = await service.WithdrawAsync(
            accountId: 2, amount: 50m, TestContext.Current.CancellationToken);

        Assert.False(result.IsSuccess);
        Assert.Equal("Account.InsufficientFunds", result.Error!.Code);
        Assert.Equal(0, accounts.SaveCount);
    }
}

internal sealed class FakeAccountRepository(Account? account) : IAccountRepository
{
    public int SaveCount { get; private set; }

    public Task<Account?> GetByIdAsync(int accountId, CancellationToken cancellationToken = default) =>
        Task.FromResult(account);

    public Task SaveChangesAsync(CancellationToken cancellationToken = default)
    {
        SaveCount++;
        return Task.CompletedTask;
    }
}
The fake returns the account we give it and counts the saves. That lets the first test assert that a 30 withdrawal from 100 saved exactly once, and the second that a 50 withdrawal from 20 saved nothing.
dotnet test in the solution folder runs all four:
dotnet test
The output ends with the test summary:
Test summary: total: 4, failed: 0, succeeded: 4, skipped: 0, duration: 2.8s
Build succeeded in 4.6s
The whole command took 4.6 seconds on our machine, build included, and neither a database nor a web server was involved.
What these tests can’t show is whether the layers fit together at runtime, such as the EF Core mapping and the DI registrations. Integration tests cover that, and we leave them out here.
Keeping the Endpoints Clean With Architecture Tests
For the inner layers, the compiler is already on guard. To see it, add this using line to the top of Account.cs. It points outward, so you’ll undo it right after:
using Banking.Services;
The build fails:
Account.cs(1,15): error CS0234: The type or namespace name 'Services' does not exist in the namespace 'Banking' (are you missing an assembly reference?)
The Domain project doesn’t reference Services, so as far as the compiler knows, that namespace doesn’t exist. For the inner layers, breaking the rule is a compile error, as long as no one adds a project reference that points outward. Delete the line again.
The Presentation layer is another story. Remember the question from the Clean Endpoints section? What stops an endpoint from taking a BankingDbContext and skipping the service? At compile time, nothing.
Here’s an endpoint that does exactly that. It’s the kind of code we don’t want, so add it only to watch it get caught, then remove it. Create Banking.Api/SneakyEndpoints.cs:
using Banking.Infrastructure;

namespace Banking.Api;

public static class SneakyEndpoints
{
    public static void MapSneakyEndpoints(this IEndpointRouteBuilder app) =>
        app.MapGet("/api/sneaky/{accountId:int}", async (int accountId, BankingDbContext dbContext) =>
            await dbContext.Accounts.FindAsync(accountId));
}
The build succeeds with no warnings. As far as the compiler can tell, nothing is wrong.
That’s the gap an architecture test fills. Add one more test project:
dotnet new classlib -n Banking.ArchitectureTests
dotnet solution add Banking.ArchitectureTests
Like the unit test project, this one starts with a Class1.cs you can delete. It needs NetArchTest as well as the test packages, so replace Banking.ArchitectureTests/Banking.ArchitectureTests.csproj with:
<Project Sdk="Microsoft.NET.Sdk">

  <PropertyGroup>
    <TargetFramework>net10.0</TargetFramework>
    <ImplicitUsings>enable</ImplicitUsings>
    <Nullable>enable</Nullable>
    <IsPackable>false</IsPackable>
    <IsTestProject>true</IsTestProject>
  </PropertyGroup>

  <ItemGroup>
    <Using Include="Xunit" />
  </ItemGroup>

  <ItemGroup>
    <PackageReference Include="Microsoft.NET.Test.Sdk" Version="18.10.1" />
    <PackageReference Include="NetArchTest.Rules" Version="1.3.2" />
    <PackageReference Include="xunit.v3.mtp-off" Version="4.0.1" />
    <PackageReference Include="xunit.runner.visualstudio" Version="4.0.0" />
  </ItemGroup>

  <ItemGroup>
    <ProjectReference Include="..\Banking.Api\Banking.Api.csproj" />
  </ItemGroup>

</Project>
This project references the API, so it can see the assemblies of all four layers. The package is NetArchTest.Rules, which inspects compiled assemblies and tells you which types depend on what. Create Banking.ArchitectureTests/LayerTests.cs:
using Banking.Api;
using Banking.Domain;
using Banking.Services;
using NetArchTest.Rules;

namespace Banking.ArchitectureTests;

public class LayerTests
{
    [Fact]
    public void Domain_DependsOnNoOtherLayer()
    {
        var result = Types.InAssembly(typeof(Account).Assembly)
            .ShouldNot()
            .HaveDependencyOnAny("Banking.Services", "Banking.Infrastructure", "Banking.Api")
            .GetResult();

        Assert.True(result.IsSuccessful, "Offending types: " + string.Join(", ", result.FailingTypeNames ?? []));
    }

    [Fact]
    public void Services_DoNotDependOnTheOuterRing()
    {
        var result = Types.InAssembly(typeof(IAccountService).Assembly)
            .ShouldNot()
            .HaveDependencyOnAny("Banking.Infrastructure", "Banking.Api",
                "Microsoft.EntityFrameworkCore", "Microsoft.AspNetCore")
            .GetResult();

        Assert.True(result.IsSuccessful, "Offending types: " + string.Join(", ", result.FailingTypeNames ?? []));
    }

    [Fact]
    public void Endpoints_GoThroughTheServices()
    {
        var result = Types.InAssembly(typeof(AccountEndpoints).Assembly)
            .That()
            .ResideInNamespace("Banking.Api")
            .ShouldNot()
            .HaveDependencyOnAny("Banking.Infrastructure", "Banking.Domain.IAccountRepository")
            .GetResult();

        Assert.True(result.IsSuccessful, "Offending types: " + string.Join(", ", result.FailingTypeNames ?? []));
    }
}
Two of the tests guard the inner layers. The Domain uses no other layer, and the Services use neither the outer layers nor EF Core and ASP.NET Core.
The third test is the one we promised in the Clean Endpoints section. Types in the Banking.Api namespace may use the services, but never Infrastructure or the repository interface. Program.cs isn’t in that namespace, so our composition root stays free to register everything.
Let’s run the tests with the sneaky endpoint still in place:
dotnet test
The unit tests pass, and one architecture test fails and names the culprit:
  Banking.ArchitectureTests test net10.0 failed with 1 error(s) (3.2s)
    ...\Banking.ArchitectureTests\LayerTests.cs(43): error TESTERROR:
      Banking.ArchitectureTests.LayerTests.Endpoints_GoThroughTheServices (40ms): Error Message: Offending types: Banking.Api.SneakyEndpoints
      ...

Test summary: total: 7, failed: 1, succeeded: 6, skipped: 0, duration: 4.0s
Build failed with 1 error(s) in 6.1s
Delete SneakyEndpoints.cs, and all seven tests pass again. Run them in CI, and every pull request gets that check, whether or not a reviewer spots the leak.
A note on the library before you depend on it: its latest version, 1.3.2, is from May 2021. It handled our .NET 10 assemblies without trouble.
Conclusion
In this article, we have learned about Onion architecture. We have explained our take on the architecture by splitting it into the Domain, Service, Infrastructure, and Presentation layers.
Here is the finished solution, one project per layer plus the two test projects:
Banking.slnx
Banking.Domain/
    Account.cs, AccountErrors.cs, IAccountRepository.cs, Result.cs
Banking.Services/
    AccountService.cs, DependencyInjection.cs, IAccountService.cs
Banking.Infrastructure/
    AccountRepository.cs, BankingDbContext.cs, DependencyInjection.cs
Banking.Api/
    AccountEndpoints.cs, Banking.Api.http, Program.cs, ResultExtensions.cs, appsettings.json
Banking.UnitTests/
    AccountServiceTests.cs, AccountTests.cs
Banking.ArchitectureTests/
    LayerTests.cs
We started with the Domain layer, where we saw the definitions for our entity, the repository interface and the errors.
Then we saw how the Service layer was created, where we are encapsulating the operations of our application.
Next, we looked at the Infrastructure layer, where the implementation of the repository interface is placed, as well as the EF database context.
And finally, we saw how our Presentation layer stays thin. Then, we explained how we can connect all of the layers using an ASP.NET Core Web API.
On top of that, we tested the core without a database, and wrote an architecture test that keeps the endpoints away from the Infrastructure layer.
As your domain grows, the layers stay where they are. New entities and repository interfaces go in the Domain, new operations become service methods, and new infrastructure implements interfaces the core already declares.
The same inward rule runs through our Clean Architecture in .NET course: a complete event ticketing app with four full test suites, architecture tests among them.
If you’re moving an existing app to the Onion architecture, write the architecture tests first. Each failure names the types that depend the wrong way today.
Until the next article,
All the best.
Tested with .NET 10.0.10, EF Core 10.0.12, xUnit v3 4.0.1 and NetArchTest.Rules 1.3.2.
Amazing article, been using your example repository as a basis for refactoring my current project.
Could you help me understand the choice behind adding validation logic to some of the DTOs in the Contracts solution? I thought that DTOs shouldn’t have behaviour attached to them.
Shouldn’t there be a folder for ViewModals within the presentation layer, at least for MVC with a front end side to it? These are then validated in the controllers, mapped to a DTO -> sent to the service layer to again be mapped to the domain objects for the repositories to send them to the datastore?
Would love to hear your opinion on this.
Hi Sam. If you refer to ForCreation and ForUpdate DTOs, then those are validated with the attributes because we use them inside the request in our actions. There is no need for any additional validation layer because your API will automatically validate these DTOs as they reach your actions and return proper error responses to the client if the request body is invalid.
Thanks for the reply Marinko. The problem I’m facing is there is I have a lot of additional validation that often requires calling a service. For example if one of the DTO in the view takes in say a ProductID I might want to call _productService.Get(id) to verify it’s an existing product, and if not, add in a custom ModelState error message. So while I can do simple validation automatically with attributes I often need to do a lot more in the controller before I’m happy passing those user supplied data into the Service layer.
Well, that’s a completely different thing, something like that shouldn’t be placed inside a DTO, but a simple request validation is perfectly fine.
Thank you for this tutorial! I am currently implementing Onion Architecture in an ASP.NET Core app that uses Identity Framework. I see you have mentioned that an “Identity” project would be included under the “Infrastructure” layer. Part of my “Presentation” project, the part focusing on user account functionality such as login/logout/confirm password, will use the “Microsoft.AspNetCore.Identity” package to access the “UserManager” and “SignInManager” objects. Would you recommend abstractions be created to prevent a dependency on the “Microsoft.AspNetCore.Identity” package within the “Presentation” layer? And, do you recommend that “Identity” is it’s own project?
Hi Zenka. Your presentation layer shouldn’t have any contact with the Identity lib. You can extract it as a separate project and have all the work there, but also, as we did in our book, you can extract all the work to the service layer by creating another service class, and then the Presentation layer can communicate with the service layer with the service interfaces (abstractions).
Marinko, I see in the book that the Identity functionality is extracted into an “AuthenticationService”. However, this service returns and “IdentityResult” in its “RegisterUser” method. It looks like the controller “RegisterUser” method uses the “var” keyword when retrieving the result to get around the dependency on Identity Framework. What are your opinions on creating an adapter for the “IdentityResult”, such that your “AuthenticationService” returns an “IResult”, or something, and then you can be more explicit about the type of result in your controller method?
Yes, basically the complete Identity business logic is extracted into a service layer and we accept only the result back inside the action. It is the easiest way to handle those situations without introducing additional complexity to the project. For me, having that additional complexity is not necessary thus the solution is as is. But if you want it, you can create that adapter and process the result before even returning it to the presentation layer.
Makes complete sense. Thank you!
Hi
I wish to create this project and class libraries, but using .NET 7.0.
There is no longer a Startup.cs file generated since .NET 6.0.
Instead of in memory, I will be using a database – Adventureworks 2017.
What issues do I need to be aware of please ?
Well, there is nothing that special. Just, you don’t have those ConfigureServiecs and Configure methods, but a builder object that you use to access the Services collection or to register a middleware inside the pipeline. Our Web API book is completely updated with .NET 7, using Onion Architecture, with the SQL database, so you might give it a look, it will help you for sure.
Where would you put AutoMapper Profiles in this architecture?
Which layer is appropriate for that and why?
I use most of Map() methods within Controllers’ actions.
To be honest, this is not an important part that could affect any of the layers. But of course, you don’t want to keep it in the Repository as there you hardly want to map something, you want to work with entities. So, you can have it either in the main project or in the service. If you use mappings in both the main project and the service layer, then having it in the main projects is a better option. After all, it is a single file. In our API book, we keep it in the main.
Thank you for fast reply but I’m still confused. What do you mean by “main”? Web or Presentation where i hold Controllers or anything else? Where should I install AutoMapper nuget package?
The main project, not the Presentation layer. Also, since you reference a service layer in the main project and if you use mappings in the service layer as well, then install it in the service layer. This really depends on your project structure. But, I think, you shouldn’t be doing any mappings inside the Presentation layer (controllers). Keep all the mappings in the service layer and return the required results to your controllers.
Hi.
I have question about complex queries that you want to return fields of multiple tables. for example you want to return models of product based on modelid and lang also want to join it with some other tables to have some other useful properties.
1 – So what repository you choose to put this query and what domain model you pick for it to return?
2- also what service you pick for it?
Hi. Both for 1 and 2 choose the repo/servise of the main entity from your response.
If I have a class A and a class B, where class A contains a collection of class B, and this is created from the information of A, to comply with the single responsibility principle, who should I assign responsibility for create B?
To the controller of A, at the service of A.
Thank you in advance for your help!
Thanks for the article and the detailed explanation. The coding is very clean. I have a query though, why the scope of ExceptionHandlingMiddleware is transient and not scoped?
Hi Purba B. To be honest, you can register that service in any way you fill like it would fit your application. The author has chosen to register it as a transient service, but I am pretty sure you won’t make any mistake if you do the same but as a scoped service.
Could you share source code for this?
Please check the beginning of the article.
Oh, I removed all of the EF nastiness and Repository Junk. I use NHibernate so makes sense 🙂
Very Cool.
I threw in a DI Layer for AutoFac works great.
builder.Host.UseServiceProviderFactory(new AutofacServiceProviderFactory())
    .ConfigureContainer<ContainerBuilder>(containerBuilder =>
    {


        DI.AutoFac.AutoFacDiLoader.BuildContainer(containerBuilder, applicationConfiguration.DefaultConnection);


        /* All of these dependencies are tied to ASP.NET  */
        containerBuilder.RegisterType<ApplicationConfiguration>().As<IApplicationConfiguration>().InstancePerLifetimeScope();
        containerBuilder.RegisterType<EmailConfiguration>().As<IEmailConfiguration>().InstancePerLifetimeScope();
        containerBuilder.RegisterType<HttpContextAccessor>().As<IHttpContextAccessor>().SingleInstance();
        containerBuilder.RegisterType<ViewRenderService>().As<IViewRenderService>().SingleInstance();
    });
public static class AutoFacDiLoader { public static ContainerBuilder BuildContainer(ContainerBuilder containerBuilder, string? connectionString) { /* AutoFac Module Registration */ containerBuilder.RegisterModule(new NHibernateModule { ConnectionString = connectionString, }); containerBuilder.RegisterType<EmailConfiguration>().As<IEmailConfiguration>().InstancePerLifetimeScope(); containerBuilder.RegisterType<AccountManager>().As<IAccountManager>().InstancePerLifetimeScope(); containerBuilder.RegisterType<UserService>().As<IUserService>().InstancePerLifetimeScope(); containerBuilder.RegisterType<ProfileService>().As<IProfileService>().InstancePerLifetimeScope(); containerBuilder.RegisterType<RoleService>().As<IRoleService>().InstancePerLifetimeScope(); containerBuilder.RegisterType<EmailService>().As<IEmailService>().InstancePerLifetimeScope(); containerBuilder.RegisterType<Argon2PasswordHasher>().As<IArgon2PasswordHasher>().InstancePerLifetimeScope(); return containerBuilder; } }Which time use this pattern in the projects?
What projects is this pattern suitable for?
Thanks.
Well, we used it for small/large projects and it always worked. So, I can’t say use this architecture only with “that” type of project or anything similar.
A very comprehensive and pragmatic approach to implement a robust architecture. The inclusion of some new features of C# and net core 6 besides tips for using middlewares and docker solutions made the essay very useful and elegant.
Great work!
Thanks a lot. It is always great to hear something like that from a reader. I’m glad you find it useful.
Thanks for writing this article.
How to use service in other services for example use account service in owner service?
You shouldn’t be doing that. Use the Account repository to fetch what you need in the Owner service class and add the business logic you need. Or, for example, if you need any result from the Account service in your Owner service, you can always call that method first in the controller, and then pass it to the method inside the Owner service. After all, in your controllers, you should be calling your service layer methods.
Thanks for helping me.
Is it wrong to new the service in another service as well?
because I can’t use the above suggestions for me
Well, let me put it this way. It is not the best practice to do so as you should get access to your services through the IServiceManager interface. But if there is no other way in your app, you’ll do what you have to do.
Regarding the step of implmenting “Clean Controllers” , where you divied the Presentation (UI) Layer into 2 project . how can i do the same for Razor Pags as (Presentation Layer)?
To be honest, I didn’t use Razor Pages a lot, almost none, so I am really not sure how to do it there. Probably there is a way, but as I didn’t do it personally, I can’t provide an answer to your question.
Thank you Marinko , really appreciate your reply
Hi, would it be possible to get an example unit test with MOQed IServiceManager and ICustomerService so I can test against the controllers?
Hi. We have couple of articles about testing. I even think that one of those are about testing repo from the project similar to this one, so you can just reuse the knowledge. Just search for testing articles in the search box
Hi MarinkoSpasojevic, thank you SO much for the speedy reply!! It’s for an assignment and i’m up against it. I’ve used your other examples, but they don’t seem to work with this hierarchy. Its the MOQ of IServiceManager and the Lazy loaded CustomerService I can’t get to work – please help!
Try using this article: https://code-maze.com/testing-repository-pattern-entity-framework/ You also have the source code there. If you have issues with lazy-loaded elements, just instantiate them as you will see in the linked article, but I am not sure why that would be the case at all. The bottom line is that in the same way you mock repo, you can do with the service layer as they follow the same implementation.
Great article. I learned a lot from this! One thing I don’t quite understand is why the interface of repository is put in the domain layer, and that the Infrastructure directly references the domain layer because of that? Shouldn’t the infrastructure repository layer only reference the one layer below it which is the service layer?
Hi,
Thanks for the article.
I dont’t use Entity Framework (like many other people I know). I use Dapper as my favourite Orm; I always design the database prior to start programming also. Since you’re using RepositoryDbContext (EF), creating a tecnology dependency through the whole project (that’s my humble opinion), how would I implement a ‘RepositoryDapperDbContext’? Does it make any sense, or do I need to read the article more closely?
Thanks in advance,
Fausto
Hello Fausto Luis. Let’s just first explain this: “creating a technology dependency through the whole project” – this is not correct. The very purpose of this architecture is to have different layers that know only what they need to know. That said, only the repository layer has an idea about the EF Core and the context object. No other layer knows anything about that. So I wouldn’t agree that we create dependency throughout the whole project. The service layer is consuming the repository layer but knows nothing about the ef core and how the repository layer fetches the data from db. Also, the presentation layer has no idea about the repo layer so it knows nothing about the EF Core implementation. So as you can see, the EF is used only in a single layer and it stays there.
Now regarding your question about DapperContext, you may want to read our Dapper with ASP.NET Core Web API article. I didn’t create a repository as complex as this one, but it serves the purpose, so it might give you an idea.
Also, when you say that you always create the db first, I have nothing against that, whatsoever I even support that, for me, this is equally good as using migrations. But just to be clear here, you can use migrations with dapper as well, and you can read more about that in our Migration with Dapper and Fluent Migrator article.
I hope, I’ve provided some useful info for you here.
BR.
Hi Marinko,
Thank you for your clarifications.
I will read the articles you proposed, for better enlightment.
My past experience with EF was not the best, hence perhaps the animosity I may have shown. I should have read the article more carefully.
My apologies for that.
Have a nice day.
Fausto.
Hi Fausto. You have nothing to apologize for. You didn’t insult anyone, you’ve just shared your opinion and question. I did the same. EF Core is now a pretty good tool (well to be more precise it is a great tool and it is like that for a while now), it is fast – with every new version even faster. But I understand that developers like to write their own SQL queries, and I have nothing against that, whatsoever I support that idea a lot. Just, we have been doing a lot of work with EF Core and it proved to be a great tool for us, so we are using it mostly in our articles and our books.
Dear Marinko,
Thanks for the perfect information you have sharing, the question is, (maybe it is the amateur question) is this helpful architecture for the MVC project as well?
Thanks
To be honest, I didn’t use this architecture, in this very form, with MVC. But I really believe that the idea could be used in the MVC apps as well. Maybe that presentation part would be a slight issue, maybe not, as I said I didn’t use it. But overall, it could be used in any type of app.
Hi Marinko, thank you for this article.
I see you put Update method (Task UpdateAsync) in service layer.
Why you did not put in the Repository ?
Hello Freesix. This is more of an EF Core thing. It is about tracking changes. You can read more about it here: https://code-maze.com/efcore-modifying-data/
Amazing article, Thanks
You are most welcome. I’m glad you like it.
How to implement logging in the service layer. for ex, I want to add logging to OwnerService.
But since OwnerService is wrapped with ServiceManager class, How I can inject ILogger<OwnerService> in the OwnerService constructor from ServiceManager class?
Just inject it into the Service Manager class. For example like we do it in our Web API book:
public ServiceManager(IRepositoryManager repositoryManager, ILoggerManager logger, IMapper mapper) { _companyService = new Lazy<ICompanyService>(() => new CompanyService(repositoryManager, logger, mapper)); _employeeService = new Lazy<IEmployeeService>(() => new EmployeeService(repositoryManager, logger, mapper)); }Hi Marinko,
I am getting the following exception if I inject generic ILogger to the OwnerService class.
My Code:
public ServiceManager(IRepositoryManager repositoryManager,ILogger logger )
{
_lazyOwnerService = new Lazy<IOwnerService>(() => new OwnerService(logger, repositoryManager));
}
Exception:
cannot convert from ‘Microsoft.Extensions.Logging.ILogger’ to ‘Microsoft.Extensions.Logging.ILogger<Services.OwnerService>’
public ServiceManager(IRepositoryManager repositoryManager, ILogger<OwnerService> logger)
Just modify the access level of the OwnerService if it is internal in your app.
Hi Marinko,
OwnerService class has following Constructor:
public OwnerService (ILogger<OwnerService > logger, IRepositoryManager repositoryManager)
{
_logger = logger;
_repositoryManager = repositoryManager;
}
Service Manager Class:
public ServiceManager(ILogger logger, IRepositoryManager repositoryManager)
{
_lazyOwnerService = new Lazy<IOwnerService>(() => new OwnerService(logger, repositoryManager));
_lazyAccountService = new Lazy<IAccountService>(() => new AccountService(logger, repositoryManager));
}
If you can see I need to inject the specific Logger into the Individual Service classes like OwnerService and AccountService from the Service Manager class.
Issue is with the ServiceManager class. If we directly consume the individual Service i.e. OwnerService then DI will work smoothly but since there is additional abstraction of ServiceManager, I could not inject specific logger.
Any solutoin on it?
Yes, I can see, and I showed it exactly how to do it in the service manager class. Your code, the one you’ve shown in the last comment is not the one I presented in my reply. Also, you have another option to create a custom logger, which I always prefer doing since I have better control over logging: https://code-maze.com/net-core-web-development-part3/ Then you can inject it easily for any service. This is the same approach that we use in our book.
I have a one question. Can I use DTOs classes in my Blazor wasm project? Or is it better for me to create models?
Since Blazor WASM is a client app, you should be using DTOs.
thanks.
How could .net core identity be implemented in this architecture?
Of course, it can. In our book Ultimate ASP.NET Core Web API, we are doing exactly that. You can find more info on this link: https://code-maze.com/ultimate-aspnetcore-webapi-second-edition/ You can even find a preview of that exact part.
Also in our security book, which you can find on the same link we combine ASP.NET Core Identity with IdentityServer4/Duende so everything is covered there as well.
Hello, which layer are you going to add pagination, sorting etc to, services layer or infrastructure layer?
Hello. You will spread it a bit between the layers. The query should go in the Repository Layer since you want to create such a query that is as fast as possible. That’s why we in our book create extensions on IQueryable which allows us to implement all the conditions and execute that query on the database completely. If you have some additional validations and you have to repack the result for additional headers and stuff, you can do that in the service layer. Again, the entire process is well described in our Ultimate ASP.NET Core Web API book.
Would I also add MVC controllers in the presentation layer? I am trying to avoid to add the MVC controllers and views to the web project but adding them to the presentation class library gives me a bunch of errors. Could you maybe show how to add them along with the api controllers in the presentation layer? Thanks so much in advance!
Hello there. To be honest, I didn’t try to do that with the MVC project but as with Web API, you have to tell your main project where to find your controllers. Maybe this can help you: https://stackoverflow.com/questions/401376/asp-net-mvc-put-controllers-into-a-separate-project
I actually tried it with that StackOverflow article but it doesn’t work unfortunately..
It is possible to deploy an api with this architecture in Azure Static Web Apps?
Hey Yassert, Azure Static Web Apps are used for the deployment of static applications. That includes most of the client-side applications including Blazor WebAssembly.
Hi Marinko, thank you for your great article.
I have few questions :
1. In your ebook “Ultimate ASP.Net Core Web API”, did you use Onion Architecture or Layered architecture ? and why you choose that architecture in that project.
2. In this article you said The Onion architecture was first introduced by Jeffrey Palermo, to overcome the issues of the traditional N-layered architecture approach. Can you please list some of the problem faced when using the traditional N-layered architecture?
Hello Johnson.
You are most welcome. To be honest, this was written by one of our authors, but it’s all the same – article is on our site 🙂
1) In our first version of the book we’ve used Onion architecture because as we said in the article: “All of the layers interact with each other strictly through the interfaces defined in the layers below.” This is a great way to create a solution.
2) Well in N-Layered architecture the sentence I quoted in the answer under 1is not true. There, the UI/Presentation layer can interact with the domain layer directly not through abstractions, and even more, it shouldn’t be interacting with the domain layer at all. I can write about that a lot but you can read here what more experienced people have to say on that topic 🙂
Good article, agree with most of the points. Only concern: “Managers”:
As for “yet another abstraction over already abstracted EF” – agree with you, we should not expose EF or any other DB provider and make strict methods for each case.
Regarding managers, in the repository layer, it acts as a UoW. So basically you only inject your manager class, which wraps all your repository user classes, and then you can work with a single class to call all your user repository classes and call a single Save method to wrap all the executions inside a single transaction. In the repository manager class, we like using the Lazy class since it is creating an instance of the repo class only when that one is needed, but you can use DI here as well if you want to go DI all the way.
The same thing goes for the ServiceManager just it doesn’t have any connection to the save method from EF Core.
Regarding the “yet another abstraction…” thing, I stopped replying to that a long time ago. There will always be two sides to everything in this world, so this is no exception as well. I’ve read tons of articles having pros and cons, and it is always on a developer to decide. We know why we are doing things this way and we will keep propagating that for sure. To be honest, this shouldn’t be important at all. The architecture is the main thing here, and if someone doesn’t want to use the repository layer, then they shouldn’t use it, and that is it 🙂
Hello.
Thanks for the article!
At the bottom, where it says
We can then open the browser at the
https://localhost:50001/swaggeraddress, where we can find theSwaggeruser interface:Shouldn’t it be 5001?
Thanks,
André.
Yeah, that’s a typo. Thanks for that.
Great post!!! What do you recommend if the service manager or repository manager grows too much? could be partial classes?
Regards
Hello Alejandro. Thank you for your comment. Yes, it could be partial classes but basically, these classes are just simple wrappers around individual repos/services. So, you can make them as small as possible but IMO you don’t get anything much from that because there is nothing in these classes that you have to maintain in the long term or anything similar because you are just creating individual service/repo instances in a lazy manner, and that logic is straight forward.
Excellent article, could you help me, where should I add the calculable properties in this architecture. Thank you!
Hello Yassert. What do you mean by Calculable properties, I’m not sure that I understand? Basically, any business logic should be moved to the service layer, so yes, calculations go there as well.
Thanks for your answer, I mean the invoice total, for example, currently these calculations are made in the entity class, thanks!
Hi
Can you share code github url
The source code is linked at the top of the article
Thank-you for this article. I have implemented a Repo + UnitOfWork pattern for many years over several projects and have never run into any issues. It’s a solid pattern. Many want to change and continually improve but I always say just because you can change something doesn’t mean you should. This is not at you OP this is more at the dev community as a whole. Once again thanks for the refresher and reflection on onion architecture.
You are most welcome, John. Also, thank you too for reading the article and your comment.
Would you publish another article about DDD concepts? We really need something clean about this from you!!
We still don’t have any plans to go into the DDD area with our articles, but we will cover it eventually for sure.
Great article..
Thanks. I’m glad you like it.
Should very good article, and then blazor webassemly adopt a similar architecture?
In my opinion, implementing something like this on the client side is overkill. You can always use folders in the same app to split some responsibilities but I would use different projects only if I want to reuse some components or to introduce lazy loading.
Thank you very much,One more question ,Should the blazor assembly share some libraries with the server ?such as DTO and verification
Of course, the main advantage of creating the client app in C# is the possibility to share the code between the client and the server app.
Thank you for this great and useful article.
It was very helpful.
You are most welcome. Thank you too for reading it and for the comment.
Thanks for this article. I have a question. Can I use action filters in services?
There is no point in doing that. Use it as a global filter configured inside the Startup file or use it inside of your controllers. If you want to use AF just to remove code duplications, in the service just create another method and extract the repeating logic.
it would be greatly appreciated if you share git repo link.
Link is already in the article. Please check the start of the article in the red box.
Great article. Recently I’ve noticed there is a lot of error-prone demos and videos where people report about onion, but it can have lots of violations 🙂
The idea with split of service layer – makes great sense. It’s a big question, how to avoid violations in onion type of architecture, so that’s a step ahead.
Couple of things to propose also:
Cheers.
Hello Eugene. Thank you for the comment and your suggestions, I am pretty sure our readers will benefit from them.
Have a great day and all the best.
Thanks for writing the article.
Good coding, clean approach and splitting of responsibilities.
Unfortunately I see these kind of repository-architectures all the time, they are very problematic on the long term.
– the repository pattern takes the power of Entity Framework completely away. (relational queries, advanced sorting, filtering, everything)
– abstracting EF (Core) away is wishful thinking. I saw it many times, it is usually impossible to replace EF with something else after a few years of coding.
– if you want to use a pattern like this you shouldn’t return IEnumerable, you should return IQueryable.
– the REST service shouldn’t return all database records at once.
– the repository pattern gives you a false idea that the repositories are not related to each other and can be used individually. This is not the case. With complex data models this leads to all kind of problems.
ASP.NET Core OData actually fixes most of the problems by default.
Thank you for the comment. I must say that we have developed large projects using these repository steuctures and it never failed, not a single time. Also in our book we implement paging filtering sorting using this pattern and it works pretty well on large amount of data. About IQueriable, you should use it while fetching data from db, once you want to use that data, outside the repository layer, I will always return IEnumerable. You can filter everything out on the repo layer. Again, architecture is a tricky stuff and people should use it as it fits the project, there is no one single way. At least, that is my opinion. But again, thank you for this comment, I always enjoy having constructive talks 🙂
Thank you 😉
It depends on the project, developers, indeed. There is no one size fits all.
I just think that the repository pattern (splitting repositories per entity class) is overrated. It lacks the fact that the data from the repositories are highly related, at least if you are using a complex datamodel with lots of relationships.
Obviously, I support the idea to share queries between logic, when necessary.
But I saw quite some implementations where filtering and sorting still ends up outside the repository. Or, alternatively you end up with functions like: GetUsers, GetUsersSortedByName, GetUsersFilteredByAgeAndSortedBy…AndGroupedBy. Because this gets messy and blown up, sometimes devs then start to create their own query format like GetUsers(userquery).
Then why not use the powerful Linq queries and IQueryable 🙂
Like I said, abstracting away EF is wishful thinking in a complex solution, even with things like repository pattern.
“Then why not use the powerful Linq queries and IQueryable”
This is the main point, in our case you would see action for example like this: GetAllOwners(OwnerParameters params)… And then all the way down in the repository you would find:
_context.Owners
.Skip(param.Skip)
.Take(param.Take)
.Filter(param.Name..)
.Sort(param.SortTerm)… all executed on top of IQueriable, so it will be executed inside the database returning only what you want in the most optimized way.
If the tool is well used, we all can do a lot with it, that is at least the true thing 🙂
I understand, your example is what I mentioned as “Because this gets messy and blown up, sometimes devs then start to create their own query format like GetUsers(userquery).”
It is possible, but how far do you go to support all kind of queries. In the end, you are just competing with Linq 🙂
Hello Tom.
Please, share a repo with an example of your way to work with EF, it’s always interesting saw the both sides.
The main problem returning of IQueryable is that UnitTesting no longer will be working. Because the query which is send to database is no longer controllable with IQueryable. Query code can be contained in Repository, or Service layer, or Controller. In very bad projects it will be contained in client (my colleagues have written some magic code to write queries in WPF-client).
Using IQueryable will speed up your initial development cycle. But maintenance will be a masacre. Why you ask? Because you never knew in which layer your query is contained. It could be possible that your query is splitted. Some parts in Repository, some parts in Controllers. Maybee some parts in a helper class.
If you are using UnitTests and hav IQueryable then you no longer need to wirte UnitTest because they don’t make sense if you use IQueryable.
Do not use IQueryable, except you are the only developer on the project!
Thank you Andreas.
I agree that spreading IQueryable over multiple layers is more complicated, also for Unit Tests.
But the question is: how would you implement use-cases where mutiple layers are extending IQueryable. What is the alternative?
For example:
– UI requests all orders for Customer X with status Open, user wants to sort by Amount.
– Security layer adds filtering to return only orders that the user is allowed to see.
– Another layer adds filtering to return only orders larger than $1000 since the user configured that somewhere in the settings.
– Another layer adds filtering to return only orders that are not Deleted and not older than 5 years.
Well, you get the idea.
We have scenarios like this implemented with IQueryable and it works amazing. In the end, only 1 query is executed by the database and only the data that is needed is returned. Also, layers don’t have to know about each others query logic.
Do you have a repo where you implement .Skip(param.Skip)
.Take(param.Take) ?
Yes, you can search for our Paging article. Also in our WebAPI book we talk in detail about these techniques.
Thank you Andreas.
I agree that spreading IQueryable over multiple layers is more complicated, also for Unit Tests.
But the question is: how would you implement use-cases where mutiple layers are extending IQueryable. What is the alternative?
For example:
– UI requests all orders for Customer X with status Open, user wants to sort by Amount.
– Security layer adds filtering to return only orders that the user is allowed to see.
– Another layer adds filtering to return only orders larger than $1000 since the user configured that somewhere in the settings.
– Another layer adds filtering to return only orders that are not Deleted and not older than 5 years.
Well, you get the idea.
We have scenarios like this implemented with IQueryable and it works amazing. In the end, only 1 query is executed by the database and only the data that is needed is returned. Also, layers don’t have to know about each others query logic.
Hello all! Firstly, thanks for this very nice onion archtiecture guide. I am a big fan of clean architectures because at the end it will be easier to maintain. However, I also understand Marinko’s concern. Sometimes queries are not as easy as getting a list or a single entity model. Instead, they can have numerous joins and other complex queries involved. Often, you end up with a model that looks different than your entity model. As of right now, your OwnerRepository and AccountRepository only return entity models. How would you solve a scenario for which the query would alter the structure of the entity model?
To give you a concrete example, lets say that you need to make a query in the AccountRepository that groups by the DateCreated propery. Essentially, you would end up with a model where each DateCreated would map to a list of accounts. How would you handle that?
You don’t modify the entity model, it should be the representation of your database table. What you do is creating a new DTO which fits your needs and use the service layer to do some business logic to populate that DTO and return it as a result to the controller and to the client. How you are going to execute your business logic is up to you, but that’s exactly why you have the service layer.
That is not going to be performant at all. You want to harness the power of sql queries. Some queries join different tables based on some conditions and do some additional work on top of that. Making individual queries and piecing that together by code could end up in really bad performance.
I don’t agree with that. You can execute your SQL statements in a very proeficient way on top of your existing entity model and then just do some business logic to pack the result in the correct DTO. The bottom line is that your entiries shouldn’t be changed. You can use them to get the data from the db but once the data is fetched, you should use DTO to manipulate your result and send it to the presentation layer.
Okay, quick example based on your article. Let’s say the frontend team wants all accounts where the owner’s date of birth is greater than 18 (DateOfBirth > 18). The Account model can stay as is but instead of the OwnerId property, they want an OwnerName property inside the Account model (replacing the id with the name of the owner).
This is adding a fair amount of complexity that can definetly occur in real life project. How would you do that?
With EF I can just fire off one query than can do exactly that. If I would have to do this in the service layer, I would need to fire off 2 queries, one to get all accounts and one to get all owners and then I need to do some matching to find the Owner for each account.
With n FKs, I would need n queries, plus the computational overhead to piece everything together the way I want the DTO to look like. In EF however, I can do a single query that can do all of that at once. Performance wise, there is a huge difference. Code will always be less performant than a perfect query. That is why we have database engineers, otherwise they would be useless.
What is your solution to that?
The way I handle this is to have a searchcreate parameter to define my searchable terms and allow me to apply validation expressions to the model that is given as a parameter to the controller, and a dto to transfer the search terms to my app service. From my service, I build an expression<func<T,bool>> that can be passed to my repository and used in the .Where. the benefit of this is that the generated query in my app service (business logic on how to search) can be unit tested. My Repo is still responsible for getting the data, but the service is now the thing that defines how to search the data.
FYI: I am not trying to complain about the onion architecture in general. I love the look of the architecture and your detailed article! They are great. I would also like to use it in my next project but I am trying to think of a solution for the type of problem I am seeing here.
Well, I am thinking exactly the same. You can use a single query where you would filter out all the owners older than 18 and then include their accounts. The EF Core would translate that as a single efficient query. So, there are no multiple queries. Just, this happens on the repository layer, on the service layer you would map your result to a proper DTO and return that to a client. For me, this is always a way to go, trying to execute a query as fastest as it can be executed and then maooing that result to a required DTO so it could be transferred to FE. Of course, it is your oroject and you will do it as you like 🙂
Definitely, the Include statement will evaluate the query properly. But I have a question in my mind, is it good as performance? As I know, the include statement selects all fields in the second table (the Account table in this case). Is there a solution to select specific fields from the account table?
From EF Core 5, you can have filtered Include:
context.Owners
.Include(a => a.Accounts.Where(condition))
I agree with you Tom. I think it al depends on the amount of (query) flexibility you need to have from a front-end perspective.
If you have relatively fixed queries that won’t change easily, this architecture would work very well. Obviously you can add some simple sorting and filtering.
If you want a powerful user-interface where the end-user can construct queries easily (filter, sort, include and group on any field), then this won’t really work. Unless you create a query model that is as rich as the IQueryable interface/filter expressions.
Maybe I am a bit biased because I saw this whole DTO architecture imlemented in a project where the end-user needed “free” querying possibilities. It was a total disaster, with an enormous amount of DTO’s and data collection methods. The end-users where frustrated that the architecture couldn’t answer their questions, the devs where frustrated because they spend all their time on creating data collection methods and mapping DTO’s…
Don’t Use EF!! Its a hell trap.