Updated on
XPath is a path language for XML, and .NET exposes it through two methods on XmlNode: SelectSingleNode() returns the first node an expression matches, and SelectNodes() returns every one of them.
An expression reads like a file path. /catalog/book walks down from the root, //book finds books at any depth, and a predicate in square brackets filters what a step returned, as in /catalog/book[price<50.00].
XML Overview
XML (eXtensible Markup Language), as the name suggests, is a markup language. It uses a hierarchical organization to describe and store data.
Another characteristic of the XML language is that it doesn’t have predefined tags and the users create their own. The number of tags is also unlimited. In this way, XML is flexible and suitable for describing any kind of information.
XML Syntax
The XML document has a hierarchical model composed of one root element, the higher-level element, and its branches.
We can define an element as everything between (and including) an opening tag (<tagName>) and its respective closing tag (</tagName>), being that each of these building blocks can contain text, attributes, or even other nested elements:
<?xml version="1.0" encoding="utf-8" ?>
<catalog>
  <book id="1">
    <author>King, Stephen</author>
    <title>IT</title>
    <genre>Horror</genre>
    <price>40.00</price>
  </book>
  <book id="2">
    <author>Assis, Machado De</author>
    <title>Dom Casmurro</title>
    <genre>Romance</genre>
    <price>50.00</price>
  </book>
  <book id="3">
    <author>Calaprice, Alice; Lipscombe, Trevor</author>
    <title>Albert Einstein: A Biography</title>
    <genre>Biography</genre>
    <price>30.00</price>
  </book>
  <book id="4" xmlns="urn:example-schema">
    <author>Fowler, Martin; Beck, Kent</author>
    <title>Refactoring: Improving the design of existing code</title>
    <genre>Scientific</genre>
    <price>60.00</price>
  </book>
</catalog>
In this example, we have an XML file representing a catalog of books, where the catalog is the root element and holds all the information that we will handle.
Each book’s author, title, genre, and price are represented by nested elements inside the parent tag book. This structure uses an attribute to define each book index.
The lower-level elements, like author, have their values represented by text, a string placed between its starting and closing tags.
What Is XPath, and Which Version Does .NET Support?
XPath is a query language for XML. An expression describes a path through the document tree, and .NET evaluates it against a loaded document and hands back whatever nodes it matched.
The syntax reads like a file path. A leading / starts at the root, // searches at any depth, a name is one step down, and @ reaches an attribute. Square brackets hold a predicate that filters whatever the step in front of them returned.
.NET implements XPath 1.0, and only XPath 1.0. Microsoft’s reference for SelectNodes() cites the W3C XPath 1.0 recommendation, and the LINQ to XML extensions describe their result ordering against that same recommendation.
Everything XPath 2.0 and 3.1 added is simply absent. upper-case(), matches(), the except operator and if/then/else expressions all throw an XPathException. The message for a missing function blames a namespace manager rather than the version, which sends people looking for the wrong problem entirely.
These expressions are similar to those used to navigate through the folders in an operating system, which makes XPath familiar to anyone starting work with it. Every expression in this article is built from those four pieces:
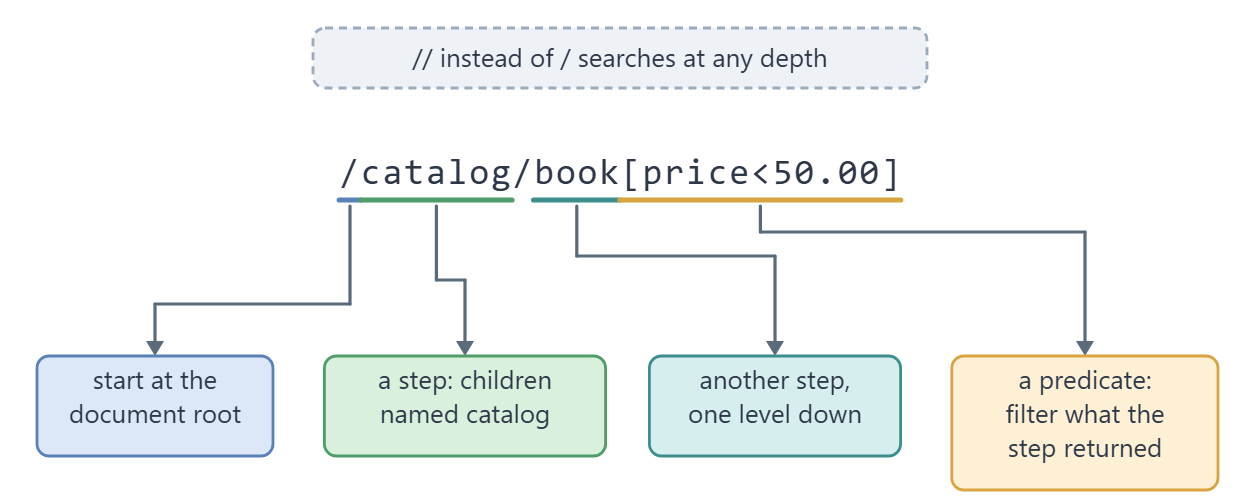
Here is what a handful of expressions match, and how many nodes each one returns against the catalog above:
| Example expression | What it matches | Against the sample catalog |
|---|---|---|
/catalog | the root catalog element | 1 node |
/catalog/book | every book child of catalog that is in no namespace | 3 of the 4 books |
/catalog/book[1] | the first book child of catalog | 1 node |
/catalog/book[last()] | the last such book | 1 node |
/catalog/book[@id='3'] | the book whose id attribute is 3 | 1 node |
/catalog/book[price<50.00] | every such book priced under 50.00 | 2 nodes |
/catalog/book[price>10.00]/author | the author of every such book priced over 10.00 | 3 nodes |
//book | every book at any depth, still in no namespace | 3 nodes |
//book/@id | the id attribute of each of those | 3 nodes |
//catalog/*[local-name()='book'] | every book child whatever its namespace | all 4 books |
In summary, the XPath’s expressions allow us to combine various criteria to select a node or a set of nodes. The snippets inside squared brackets are called predicates.
Project Setup and Configuration
To understand how XPath works in action, let’s create a project to experience different alternatives for navigating through an XML file.
As it is a simple example project, let’s create a simple .NET console project. If we need to produce the document rather than read one, creating XML files in C# covers that side of the job.
Adding the XML File to the Project
First, let’s add our XML file to the project by adding a new file called BooksCatalog.xml. Next, let’s use a previous code with book samples and paste it into this file.
After creation, we need to configure the XML file to be copied to the output folder on building the application. Rather than setting that through a file’s properties in one IDE, let’s declare it in the project file, which behaves the same way in Visual Studio, Rider, Visual Studio Code and the command line:
<ItemGroup>
  <Content Include="..\Resources\BooksCatalog.xml" Link="BooksCatalog.xml">
    <CopyToOutputDirectory>Always</CopyToOutputDirectory>
  </Content>
</ItemGroup>
The Always value replaces the XML file in the output folder on every build, which ensures that the application will always handle the most recent catalog data.
How Do SelectSingleNode() and SelectNodes() Differ?
SelectSingleNode() returns the first node an expression matches, as a single XmlNode. SelectNodes() returns all of them, as an XmlNodeList. That is the entire difference in behaviour between the two.
Both are declared on XmlNode rather than on XmlDocument, so we can call either one on the document, on the document element, or on any node further down the tree.
Whichever node we call them on becomes the context node, the starting point for a relative expression. From the catalog element, book means “the book children of this element”.
An expression beginning with / or // ignores the context node and starts at the document instead. Every expression in this article begins with //, so the root we keep passing around makes no difference to any of these results.
Both methods also take an optional second argument, an XmlNamespaceManager, which the section after this one needs.
| Method | Declared on | Returns | When nothing matches |
|---|---|---|---|
SelectSingleNode() | XmlNode | XmlNode?, the first match | null |
SelectNodes() | XmlNode | XmlNodeList?, every match | an empty list, Count 0 |
XPathSelectElement() | XNode, extension | XElement?, the first match | null |
XPathSelectElements() | XNode, extension | IEnumerable<XElement>, every match | an empty sequence, never null |
XPathEvaluate() | XNode, extension | object: a double, string, bool or node sequence | depends on the expression |
XPathNavigator.Select() | XPathNavigator | XPathNodeIterator | an iterator with Count 0 |
Before we start to read specific data from the file, let’s see what we need to do to load the file into memory:
var path = Path.Combine(AppContext.BaseDirectory, "BooksCatalog.xml");

var doc = new XmlDocument();
doc.Load(path);
var root = doc.DocumentElement!;
We create an instance of the XmlDocument class to represent the data in memory. Next, we pass the file path as an argument to the Load() method, which will load the specified document. We build that path from AppContext.BaseDirectory so it points at the copy sitting beside the executable, which is what makes the sample run under dotnet run as well as from an IDE.
Furthermore, we access the base element through the DocumentElement property and set a new variable, root. That property is declared as nullable, and the null-forgiving ! operator states something we can prove here: a well-formed document that has just loaded has a document element. In front of SelectSingleNode(), as we will see, the same operator would be hiding a value that really can be null.
We are now ready to perform our queries on our data. So, let’s create a method to perform this action:
public static string? SelectSingleBook(XmlNode root)
{
    var node = root.SelectSingleNode("//catalog/book[position()=2]");

    return node is null ? null : FormatXml(node.OuterXml);
}
The SelectSingleBook() method receives the root element as a parameter and queries the book at the second position in the catalog. It returns null when the query matches nothing, which is why its return type is string?. However, the OuterXml property, which holds the entire information inside the selected element, uses an inline representation of the data.
To make the text prettier, as we see in the example file, we must create a formatter method:
public static string FormatXml(string unformattedXml)
{
    return XElement.Parse(unformattedXml).ToString();
}
The string returned from the FormatXml() method will, subsequently, be output in the console with all the element information:
Selected book:
<book id="2">
  <author>Assis, Machado De</author>
  <title>Dom Casmurro</title>
  <genre>Romance</genre>
  <price>50.00</price>
</book>
Following this, let’s create another method to select a group of items:
public static List<string> SelectBooks(XmlNode root)
{
    var nodes = root.SelectNodes("//catalog/book[price<50.00]");

    if (nodes is null)
    {
        return [];
    }

    return nodes
        .Cast<XmlNode>()
        .Select(x => FormatXml(x.OuterXml))
        .ToList();
}
In the same way, the SelectBooks() method takes the root element as a parameter. But, at this time, we are querying for all elements with price less than 50.00.
Once we get the query result (an XmlNodeList object), we convert it to a string list containing the formatted OuterXml for each element. The compiler treats SelectNodes() as returning a nullable list, so we hand back an empty list in that case instead of silencing the warning with !.
Finally, the result is returned and printed in the console:
Selected books:
<book id="1">
  <author>King, Stephen</author>
  <title>IT</title>
  <genre>Horror</genre>
  <price>40.00</price>
</book>
<book id="3">
  <author>Calaprice, Alice; Lipscombe, Trevor</author>
  <title>Albert Einstein: A Biography</title>
  <genre>Biography</genre>
  <price>30.00</price>
</book>
How Do We Query XML That Uses Namespaces?
In another scenario, we face XML models that contain namespaces. The idea behind the namespaces is to enable applications to handle or validate elements differently, even if they have the same name.
Fortunately, the XPath language also supports namespaces in the string path. As we noted, the last book in the catalog has one more attribute to indicate a namespace:
<book id="4" xmlns="urn:example-schema">
Microsoft’s reference for XmlNode.SelectNodes() states the rule that decides what an expression without a prefix matches: “If the XPath expression does not include a prefix, it is assumed that the namespace URI is the empty namespace.” That is why //book returns three of our four books and misses the one that declares a default namespace.
Now, let’s create our selection method to query the book containing the namespace:
public static List<string> SelectBooksUsingNamespaces(XmlDocument doc)
{
    var nsmgr = new XmlNamespaceManager(doc.NameTable);
    nsmgr.AddNamespace("ex", "urn:example-schema");

    var nodes = doc.SelectNodes("descendant::ex:book", nsmgr);

    if (nodes is null)
    {
        return [];
    }

    return nodes
        .Cast<XmlNode>()
        .Select(x => FormatXml(x.OuterXml))
        .ToList();
}
As we can see, the SelectBooksUsingNamespaces() method takes an XmlDocument as a parameter, while its two siblings take an XmlNode. That is because XmlNamespaceManager needs an XmlNameTable, and the NameTable property lives on XmlDocument. Following, in the initial part of the function, we create an instance of XmlNamespaceManager using the data provided from the argument variable.
Next, the AddNamespace() method creates an association with the expected namespace. Then, we execute the SelectNodes() method, but, now, using the nsmgr variable in addition to the query expression.
Finally, we convert the result before return. So, the method outcome is printed to the console:
Selected books:
<book id="4" xmlns="urn:example-schema">
  <author>Fowler, Martin; Beck, Kent</author>
  <title>Refactoring: Improving the design of existing code</title>
  <genre>Scientific</genre>
  <price>60.00</price>
</book>
What Happens When an XPath Query Matches Nothing?
The two methods answer that differently, and the difference is where most NullReferenceExceptions in XML code start.
SelectSingleNode() returns null. There is no empty node to hand back, so the caller has to check before reaching for OuterXml or InnerText.
SelectNodes() returns an empty XmlNodeList instead. Running //catalog/book[price>1000] against our catalog gives back a list with a Count of 0, so a foreach over it does nothing and nothing throws. Finding no match is an ordinary result for either method, never an error, so neither of them throws on the way out.
Both methods are declared as returning nullable types, XmlNode? and XmlNodeList?, which is why our code needs the null-forgiving ! operator to compile with nullable reference types switched on.
That operator is worth being honest about. It silences the compiler, but it does not make a value non-null. In front of SelectSingleNode() it is standing between us and a real crash, so a null check earns its place there.
A query that finds nothing is not an error, so the check belongs in our code rather than in a try block:
var node = root.SelectSingleNode("//catalog/book[price>1000]");

if (node is null)
{
    Console.WriteLine("No book matched the query.");
    return;
}

Console.WriteLine(FormatXml(node.OuterXml));
Notice that nothing here catches an exception. SelectSingleNode() returns null rather than throwing, and the if is the whole of the handling.
How Do We Run XPath Over an XDocument?
XDocument is LINQ to XML’s document type, and XPath reaches it through extension methods rather than instance methods. They live in the System.Xml.XPath namespace, so the using directive has to be there or the methods never appear on the type.
XPathSelectElement() returns the first matching XElement, or null. XPathSelectElements() returns an IEnumerable<XElement> that is empty, never null, when nothing matches. XPathEvaluate() covers expressions returning something other than nodes, so count(//book) comes back as a double.
The expressions are the same XPath 1.0, and the namespace rule is the same too. An overload of each takes an IXmlNamespaceResolver, and XmlNamespaceManager implements that interface, so one namespace manager serves both APIs. The elements come back in document order, which is a promise the extension methods make and the raw recommendation does not.
Reach for these when the surrounding code is already LINQ to XML and one particular query reads better as a path than as a chain of Elements() calls.
If the job is to read a document rather than to query one, reading XML documents in C# covers the loading side, and LINQ to XML covers the query syntax these extension methods sit beside.
The same predicate we used with SelectNodes(), this time against an XDocument:
public static List<string> SelectBooksWithLinqToXml(XDocument doc)
{
    return doc
        .XPathSelectElements("//catalog/book[price<50.00]")
        .Select(x => x.ToString())
        .ToList();
}
Notice there is no ! anywhere: XPathSelectElements() returns a non-nullable sequence, so there is nothing for the compiler to complain about.
Its console output, produced by running the project:
Selected books with LINQ to XML:
<book id="1">
  <author>King, Stephen</author>
  <title>IT</title>
  <genre>Horror</genre>
  <price>40.00</price>
</book>
<book id="3">
  <author>Calaprice, Alice; Lipscombe, Trevor</author>
  <title>Albert Einstein: A Biography</title>
  <genre>Biography</genre>
  <price>30.00</price>
</book>
Conclusion
XPath gives us one string that describes exactly which nodes we want, and .NET hands it to us through SelectSingleNode() for the first match and SelectNodes() for all of them, or through XPathSelectElement() and XPathSelectElements() when we are already working with an XDocument.
Two things catch people out, and both are worth remembering: .NET speaks XPath 1.0 only, and an unprefixed name in an expression means “in no namespace”, so a document with a default namespace needs an XmlNamespaceManager and a prefix. When walking nodes by hand is more work than it is worth, deserialising the whole document into objects is the other way to read one.
Tested with .NET 10.0.10.