Updated on
A line break in C# is not one character. It is any of seven sequences, and ReplaceLineEndings() is the one method that matches all of them: text.ReplaceLineEndings("\n") normalises a mixed string in a single call.
String.Replace() and Regex.Replace() also do the job, but only for the sequences we name ourselves, and only in the right order. Which of the three to reach for depends on whether we know what is in the text.
What Counts as a Line Break in C#?
A line break in C# is not one character but any of seven sequences, and which ones we have to handle depends entirely on where the text came from.
Three of them appear in everyday code. Line feed, written \n, is U+000A and is what Unix, Linux, and modern macOS write. Carriage return, \r, is U+000D. The carriage return and line feed pair, \r\n, is what Windows writes, and it counts as one break rather than two.
Four more are rarer and turn up in text that arrived from somewhere else: form feed at U+000C, next line at U+0085, line separator at U+2028, and paragraph separator at U+2029.
Environment.NewLine is the sequence the current platform writes. It returns "\r\n" on Windows and "\n" on Linux and macOS, which makes it the right value to write with and the wrong value to search for.
That gap is the whole problem. Writing needs one sequence. Reading has to survive all seven.
Mixed endings are the normal case rather than an edge case: a file written on Windows, a string returned by a Linux service, and a paste from a web form can all end up in the same variable. Reading files is where mixed line endings usually come from, and anything that has to count the lines in a file has to agree on what a line break is before it can start counting.
How Do We Replace Line Breaks With String.Replace()?
String.Replace() swaps every occurrence of one substring for another and returns a new string. Replacing line breaks with it means calling it twice, and the order the two calls run in decides whether the result is right.
We replace \r\n first, then \r. Reversing that order breaks the Windows pair: replacing \r on its own leaves the \n behind it untouched, so every Windows line break becomes two line feeds instead of one.
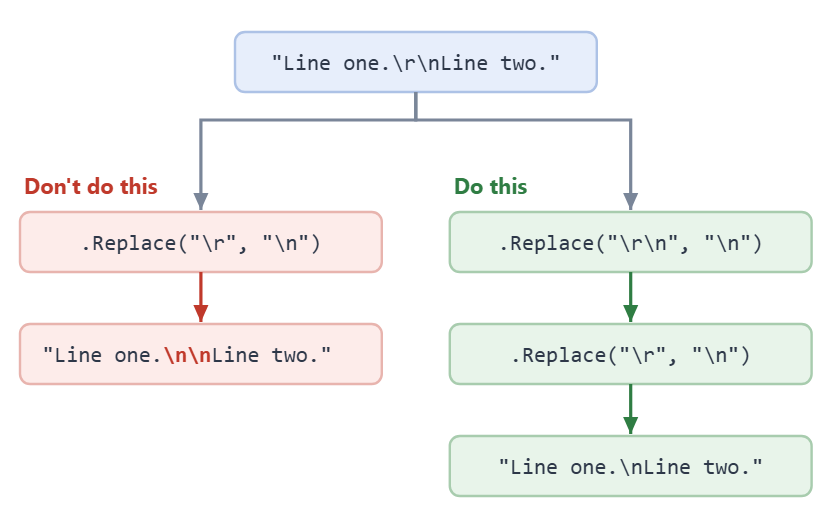
The method is a plain substring search. It knows nothing about line breaks, so it matches only the sequences we name and nothing else. The four Unicode separators pass straight through, and so does any sequence we forgot.
Replace() returns the original string instance when it finds no match, so a call that misses costs nothing. That is worth knowing before reading any benchmark that measures this chain on text with only one kind of line break in it.
Reach for it when we know exactly what is in the text.
Here is the chain in the correct order:
const string text = "Line one.\r\nLine two.\nLine three.\rLine four.";
var newText = text.Replace("\r\n", "\n").Replace("\r", "\n");
The fixture carries all three common sequences, so both calls have something to do. This gives us the result:
Line one.\nLine two.\nLine three.\nLine four.
Swapping the two calls around would turn the first \r\n into \n\n and leave the string with one line more than it started with.
How Do We Replace Line Breaks With ReplaceLineEndings()?
ReplaceLineEndings() arrived in .NET 6 and is current on .NET 10. It replaces every newline sequence with the text we hand it. One call, no ordering to get wrong.
It recognises seven sequences from the Unicode Standard: carriage return, line feed, the two of them as a pair, next line, form feed, line separator, and paragraph separator. The pair counts as a single break, which is why a Windows line break never doubles here as it can with String.Replace().
The parameterless overload replaces all seven with Environment.NewLine, which normalises mixed text to whatever the platform writes. That is the call to reach for when the text is about to be written out.
Passing "\n" takes a dedicated path in the runtime, so normalising to Unix endings is the fast case rather than the general one.
One caveat matters: never use it in a protocol parser. HTTP mandates CRLF, and a method that treats U+2028 as a line break is too permissive for that job.
For instance, we can normalise everything to the Unix line feed:
const string text = "Line one.\r\nLine two.\nLine three.\rLine four.";
var newText = text.ReplaceLineEndings("\n");
One call handles the Windows pair, the bare carriage return, and the line feed that was already correct. We get the result:
Line one.\nLine two.\nLine three.\nLine four.
The protocol-parser caveat is not ours. Microsoft’s String.ReplaceLineEndings reference says: “It is not recommended that protocol parsers utilize this API.”
The table lists every sequence the method recognises, and what each of the other two approaches in this article does with it:
| Sequence | Code point | Name | Matched by ReplaceLineEndings() | Matched by the Replace() chain | Matched by the regex |
|---|---|---|---|---|---|
\n | U+000A | Line feed (LF) | Yes | No | Yes |
\r | U+000D | Carriage return (CR) | Yes | Yes | Yes |
\r\n | U+000D U+000A | CRLF, as one break | Yes | Yes | Yes |
\u0085 | U+0085 | Next line (NEL) | Yes | No | No |
\f | U+000C | Form feed (FF) | Yes | No | No |
\u2028 | U+2028 | Line separator (LS) | Yes | No | No |
\u2029 | U+2029 | Paragraph separator (PS) | Yes | No | No |
How Do We Replace Line Breaks With a Regular Expression?
Regular Expressions enable precise pattern matching and character pattern replacement in strings. This makes the Regex.Replace() method a valid choice for handling line breaks, though rarely the best one.
The current idiom is a source-generated regex, declared as a partial method on a partial class:
[GeneratedRegex(@"\r\n|\r|\n")]
private static partial Regex LineBreakRegex();
The pattern names all three ASCII sequences, and it names \r\n first so that a Windows pair is consumed as one match rather than as two. Then we call it with the input string and the replacement:
const string text = "Line one.\r\nLine two.\nLine three.\rLine four.";
var newText = LineBreakRegex().Replace(text, "\n");
Here Regex.Replace() matches the three ASCII line break sequences and rewrites each as \n. The four Unicode separators in the table above are not in the pattern, so they survive untouched. And again, we get the result:
Line one.\nLine two.\nLine three.\nLine four.
A regular expression is the right tool when the line break is part of a bigger pattern we are matching anyway. On its own it does nothing the two methods above do not already do, and it costs the most to run.
Which Line Break Replacement Method Should We Use?
Correctness decides this before speed does, and correctness points at ReplaceLineEndings(). It matches all seven sequences, has no ordering rule to get wrong, and its name says what it does.
Speed no longer separates it from String.Replace(). On a paragraph of mixed line endings the two run within a few nanoseconds of each other and swap places between runs, so neither is reliably faster than the other on either input we measured.
Allocation does separate them. The Replace() chain makes two passes and allocates a string on each, twice the memory of the single pass ReplaceLineEndings() makes over the same text.
Regex.Replace() is the slowest of the three by a wide margin on both inputs, and it buys nothing when the line break is all we are matching.
Reach for String.Replace() when we know exactly which sequences the text contains and want nothing else touched. Text we generated ourselves is that case; text from a user or an API is not.
To measure this, we rely on the BenchmarkDotNet library, running each method over two inputs: the short single break string the article used to measure, and a paragraph carrying \r\n, \n, and \r mixed together:
[Params("Short", "Mixed")]
public string Input { get; set; } = "Short";

[GlobalSetup]
public void GlobalSetup() => _text = Input == "Short" ? ShortText : MixedText;

[Benchmark]
public string StringReplace() =>
    ReplaceLineBreak.ReplaceLineBreaksUsingTheStringReplaceMethod(_text);

[Benchmark]
public string StringReplaceLineEndings() =>
    ReplaceLineBreak.ReplaceLineBreaksUsingTheStringReplaceLineEndingsMethod(_text);

[Benchmark]
public string RegexReplace() =>
    ReplaceLineBreak.ReplaceLineBreaksUsingTheRegularExpressionReplaceMethod(_text);
The [Params] attribute runs the whole set twice, once per input, so the two cases sit side by side in one table. Now we can run the benchmark and assess the results:
| Method                   | Input | Mean      | Error    | StdDev   | Gen0   | Gen1   | Allocated |
|------------------------- |------ |----------:|---------:|---------:|-------:|-------:|----------:|
| StringReplace            | Mixed | 213.71 ns | 4.150 ns | 4.613 ns | 0.2275 | 0.0002 |    1904 B |
| StringReplaceLineEndings | Mixed | 202.75 ns | 2.508 ns | 2.094 ns | 0.1137 |      - |     952 B |
| RegexReplace             | Mixed | 486.05 ns | 6.806 ns | 6.034 ns | 0.1135 |      - |     952 B |
| StringReplace            | Short |  33.16 ns | 0.717 ns | 1.158 ns | 0.0114 |      - |      96 B |
| StringReplaceLineEndings | Short |  32.69 ns | 0.411 ns | 0.384 ns | 0.0114 |      - |      96 B |
| RegexReplace             | Short |  98.23 ns | 0.892 ns | 0.745 ns | 0.0114 |      - |      96 B |
On the short string the two String methods are a tie at roughly 33 ns, and on the mixed paragraph they are a tie again at roughly 200 to 215 ns. That ordering is not stable: across three runs of this benchmark on the same machine, StringReplace came out ahead of StringReplaceLineEndings on the mixed input once and behind it twice, by margins smaller than the spread between runs. Neither method is meaningfully faster than the other, and any article that reports one of them as the winner is reporting noise or an unrepresentative fixture.
Memory is the honest difference. On the mixed paragraph the Replace() chain allocates 1904 bytes to ReplaceLineEndings()‘s 952, exactly double, because two chained calls build two strings where one call builds one. On the short string all three allocate the same 96 bytes, because the chain’s first call finds no \r\n at all and returns the original instance without allocating.
Regex.Replace() is the outlier in both directions: about 2.4 times the cost of either String method on the mixed paragraph, and about 3 times on the short one.
| Method | Matches | Ordering trap | Reach for it when |
|---|---|---|---|
ReplaceLineEndings() | All seven sequences | None, one call | We do not control the text, or it came from a file, an API, or a user |
String.Replace() | Only the sequences we name | Yes: replace \r\n before \r | We know exactly which sequences the text contains and want no others touched |
Regex.Replace() | Only what the pattern names | Yes: same alternation order | The line break is part of a larger pattern we are matching anyway |
How Do We Remove Line Breaks Instead of Replacing Them?
Pass an empty string. text.ReplaceLineEndings("") removes every newline sequence and joins the lines with nothing between them. That is documented behaviour rather than a side effect of an empty replacement.
It usually reads badly, though. Two sentences that ended on separate lines run together into one, so replacing with a single space is the more useful default: text.ReplaceLineEndings(" ") gives text that can still be read.
Removing line breaks is not the same as removing whitespace. ReplaceLineEndings("") leaves every tab, every space, and all the indentation at the start of each line exactly where it was.
String.Replace() can do the same job in two calls, removing \r and then \n. The ordering trap disappears when the replacement is empty, since both halves of a Windows pair are being deleted anyway, but the four Unicode separators still slip through.
Neither approach trims the result. A string that ended in a line break loses the break and keeps whatever spaces came before it.
In code, that is one call:
const string text = "Line one.\r\nLine two.\nLine three.\rLine four.";
var newText = text.ReplaceLineEndings(string.Empty);
Which gives us every line run together:
Line one.Line two.Line three.Line four.
If what we actually want is the lines themselves rather than one long string, it is cheaper to split the text into lines instead of rewriting the breaks. And if the goal is to remove every whitespace character rather than only the line breaks, that is a different job with a different method.
Conclusion
In this article, we have replaced line breaks in a string in C# three ways. The one to reach for by default is ReplaceLineEndings(): it matches all seven line break sequences the Unicode Standard defines, treats a Windows \r\n as one break rather than two, and needs a single call with no ordering rule to remember.
String.Replace() is the right choice when we know exactly which sequences the text contains and want nothing else touched. It matches only what we name, so we have to name \r\n before \r, and it allocates a string per call.
Regex.Replace() is worth its cost only when the line break is one part of a larger pattern we are already matching. On its own it is comfortably the slowest of the three.
Removing line breaks needs no separate method: ReplaceLineEndings("") deletes them all, and a single space is usually the more readable replacement.
Tested with .NET 10.0.302.