Updated on
A CSV file is text, but it is not simple text. A field can hold a comma, a quote, or a line break, and any of the three breaks string.Split(','). CsvHelper reads all of them correctly and maps each row onto a class of ours.
Three lines do the work: open a StreamReader on the file, wrap it in a CsvReader, and call GetRecords<Person>().
Everything after that is configuration, and it is where the traps are: files with no header row, a semicolon where we expected a comma, comment lines, files too large to hold in memory, and rows that refuse to parse. We finish by reading the same file with no library at all, because sometimes that is the requirement.
Let’s start.
VIDEO: Working With CSV Files in C#.
How Do We Read a CSV File Into a List of Objects?
CsvHelper reads a CSV file into objects in three steps. We open a StreamReader on the file, wrap it in a CsvReader, and call GetRecords<T>() with the class each row should become.
The class carries the mapping. A property named Name matches a column headed Name, and CsvHelper converts each field into the property’s type on the way in.
GetRecords<T>() does not read the file when we call it. It hands back an IEnumerable<T> that pulls one row at a time, so nothing is parsed until we enumerate it.
That single fact is the first thing most people trip over. Return the sequence out of the using block, enumerate it later, and the reader is already disposed: we get an ObjectDisposedException whose message asks whether we did exactly that.
So we enumerate inside the block, or we call ToList() while the reader is still open.
In a previous article, we had already shown how to write to a CSV file. That said, we strongly recommend reading that article first because the reading operation is very similar to writing, and we won’t explain the same concepts here.
So again, we are going to create a new console project and will try reading the same CSV file, that we created in the previous article.
That makes the whole read three lines:
using var reader = new StreamReader("filePersons.csv");
using var csv = new CsvReader(reader, CultureInfo.InvariantCulture);

var persons = csv.GetRecords<Person>().ToList();
As we can compare with writing to a CSV file, we use a StreamReader instead of a StreamWriter, and use the CsvReader instead of the CsvWriter. If the stream side of that is new, we have a separate article on how StreamReader reads a file. We then map the data in the CSV file to our own Person class:
public class Person
{
    public int Id { get; set; }
    public string? Name { get; set; }
    public bool IsLiving { get; set; }
    public DateTime DateOfBirth { get; set; }
}
Dates are parsed with the CultureInfo we handed the CsvReader, not with a format guessed from the file. The field 03/05/2006 becomes 5 March under InvariantCulture and 3 May under en-GB, so passing CultureInfo.InvariantCulture is what keeps a file readable on someone else’s machine.
How Do We Read a CSV File Without a Header Row?
A file with no header row needs two separate things, and the example above supplies only one of them.
First, the configuration has to say so. We set HasHeaderRecord to false on a CsvConfiguration and pass that configuration to the CsvReader. Handing the reader a CultureInfo instead leaves HasHeaderRecord at its default of true, and the first row of real data is quietly consumed as a header. No exception, one record short.
Second, something has to say which column feeds which property. [Index(0)] attributes on the properties are the short way. A ClassMap<Person> registered through csv.Context.RegisterClassMap<PersonMap>() is the fuller way, and it is the one that works when the class belongs to somebody else.
Neither is strictly required. Without them CsvHelper falls back to the order the properties are declared in, which is a silent dependency on how the class happens to be written.
So we build the configuration first, and hand it to the reader:
var configuration = new CsvConfiguration(CultureInfo.InvariantCulture)
{
    HasHeaderRecord = false
};

using var reader = new StreamReader("filePersons.csv");
using var csv = new CsvReader(reader, configuration);

var persons = csv.GetRecords<Person>().ToList();
There are two methods for mapping columns to properties in our class.
The first is to use annotations to specify the index. We add them to the same Person class, one per property, without dropping any:
public class Person
{
    [Index(0)]
    public int Id { get; set; }
    [Index(1)]
    public string? Name { get; set; }
    [Index(2)]
    public bool IsLiving { get; set; }
    [Index(3)]
    public DateTime DateOfBirth { get; set; }
}
Without an index the mapping falls back to the order the properties are declared in. That works right up until somebody reorders the class, at which point the file maps onto the wrong properties or fails to convert. The index attributes make the mapping explicit, which is why they belong here even when the order already matches.
The second, and more powerful way, is to use a mapping:
public class PersonMap : ClassMap<Person>
{
    public PersonMap()
    {
        Map(p => p.Id).Index(0);
        Map(p => p.Name).Index(1);
        Map(p => p.IsLiving).Index(2);
    }
}
We can create a mapping by deriving from ClassMap<T>, which is in the CsvHelper.Configuration namespace. By using a mapping, we don’t need to annotate the fields in our Person class. This can be handy, when said class is outside of our control and when we can’t make changes to it. In our mapping code, we map the first index (index 0) to the Id field, the second index to the Name field etc.
To use this map, we need to register it in the context, and hand the reader the configuration rather than a bare CultureInfo:
var configuration = new CsvConfiguration(CultureInfo.InvariantCulture)
{
    HasHeaderRecord = false
};

using var reader = new StreamReader("filePersons.csv");
using var csv = new CsvReader(reader, configuration);

csv.Context.RegisterClassMap<PersonMap>();

var persons = csv.GetRecords<Person>().ToList();
How Do We Set the Delimiter and Skip Comment Lines?
The CSV file can contain comments and can use a different delimiter than the comma. Of course, this can be specified in the CsvConfiguration as well:
var configuration = new CsvConfiguration(CultureInfo.InvariantCulture)
{
    Delimiter = ";",
    Comment = '%',
    AllowComments = true
};
Both live on CsvConfiguration, and both defaults are worth knowing before we override them.
Delimiter is not hard-coded to a comma. CsvConfiguration takes it from the culture we hand it, straight from cultureInfo.TextInfo.ListSeparator. Under InvariantCulture, en-US and en-GB that is a comma. Under de-DE and fr-FR it is a semicolon. That is the real reason every CsvHelper example passes CultureInfo.InvariantCulture: it pins the delimiter as well as the number and date formats.
Comment defaults to #, and setting it is not enough by itself. Comment lines are only skipped when AllowComments is true, and AllowComments is false by default. Leave it alone and the commented line reaches the parser as data, where it fails on the first field that will not convert.
So the two settings travel together, and a lone Comment does nothing at all.
How Do We Read a Large CSV File Row by Row?
We drop the ToList() and iterate the sequence GetRecords<T>() already returns. Each turn of the loop reads one row, builds one object, and lets the previous one go.
The difference is what stays in memory, not how fast it runs. On an 18 MB file of 500,000 rows, streaming holds effectively nothing above the baseline heap. Calling ToList() on the same file holds about 38 MB, because every record stays reachable for as long as the list does.
GetRecordsAsync<T>() is the same loop written with await foreach, for a file arriving over a network stream.
One unconvertible field stops everything, and that surprises people. By default a bad value throws a TypeConverterException and the enumeration ends part way through, so we keep the rows before it and lose the rest. Giving ReadingExceptionOccurred a handler that returns false skips the offending row and carries on, which is what a nightly import usually wants.
Streaming works because of the deferred execution an IEnumerable<T> gives us, so the loop is the thing that pulls each row out of the file:
using var reader = new StreamReader("filePersons.csv");
using var csv = new CsvReader(reader, CultureInfo.InvariantCulture);

foreach (var person in csv.GetRecords<Person>())
{
    Console.WriteLine(person.Name);
}
The two lanes below are the same file read both ways: one Person alive at a time on the streaming lane, and all 500,000 records held at once on the ToList() lane.
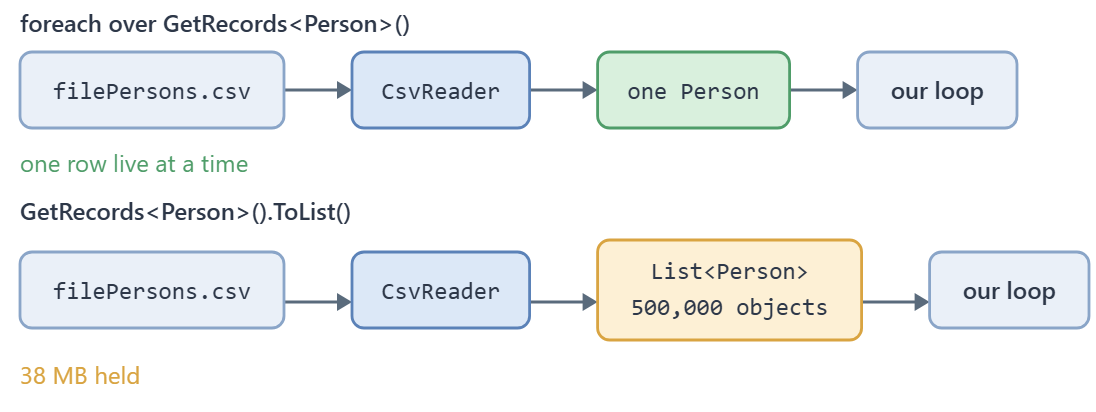
For a file arriving over a network stream, GetRecordsAsync<T>() gives us the same loop written with await foreach over an IAsyncEnumerable<T>. To keep a nightly import running past a row it cannot convert, we hand the configuration a handler instead:
var configuration = new CsvConfiguration(CultureInfo.InvariantCulture)
{
    ReadingExceptionOccurred = args => false
};
How Do We Read a CSV File Without a Library?
There are two dependency-free options and they are not equivalent.
File.ReadLines() with string.Split(',') is the one everybody reaches for first. It works exactly as long as no field contains a comma, a quote, or a line break. Given the row 1,"Close, Josh",true, Split hands back five fields instead of four and cuts the name in half.
TextFieldParser, from the Microsoft.VisualBasic.FileIO namespace, is a real delimited-text parser and it ships inside .NET. We set TextFieldType to Delimited, call SetDelimiters(","), set HasFieldsEnclosedInQuotes, then pull rows with ReadFields(). It reads quoted commas and quoted line breaks correctly, and throws MalformedLineException on a row it cannot parse.
The Visual Basic namespace puts people off. It is a namespace, not a language: C# calls the class like any other type in the shared framework, and there is no package to install.
For a CSV file, TextFieldParser is the dependency-free option that parses the row instead of splitting it:
using var parser = new TextFieldParser("filePersons.csv");

parser.TextFieldType = FieldType.Delimited;
parser.SetDelimiters(",");
parser.HasFieldsEnclosedInQuotes = true;

while (!parser.EndOfData)
{
    var fields = parser.ReadFields();

    Console.WriteLine(fields[1]);
}
File.ReadLines() is still the right tool when the file is plain text rather than delimited data, and we have measured the fastest way to read a plain text file on its own.
Microsoft’s documentation for TextFieldParser introduces it as a class that “provides methods and properties for parsing structured text files”, which is what separates it from splitting a line on commas.
Which Way of Reading a CSV File Should We Choose?
For almost every file, CsvHelper with GetRecords<T>(). It maps rows onto classes, it handles quoting and escaping correctly, and one line of configuration covers the awkward files.
Iterate that sequence instead of calling ToList() once the file is large enough that holding every row at once matters. It is the same code with one method call removed.
Reach for csv.Read() with GetField<T>() when we want the columns as values rather than as a class, and for CsvDataReader when the destination is a DataTable, remembering that every column arrives as a string.
Use TextFieldParser when a NuGet dependency is genuinely not allowed. It parses correctly and costs nothing, but it hands back string[], so the mapping is our job.
Use File.ReadLines() with Split only for a file we generated ourselves and know has no quoted fields. It is fine there and wrong everywhere else.
| Approach | Reach for it when | Quoted commas and line breaks | Dependency |
|---|---|---|---|
csv.GetRecords<T>().ToList() | mapping rows onto a class, which is most of the time | Handled | CsvHelper |
csv.GetRecords<T>() iterated with foreach | the file is large enough that holding every row matters | Handled | CsvHelper |
csv.Read() with GetField<T>() | we want the columns as values, not as a class | Handled | CsvHelper |
CsvDataReader into a DataTable | the destination is a DataTable; every column arrives as string | Handled | CsvHelper |
TextFieldParser with ReadFields() | a NuGet dependency is not allowed; returns string[] | Handled | None, ships in .NET |
File.ReadLines() with Split(',') | a file we generated ourselves with no quoted fields | Breaks | None |
CsvHelper is at version 33.1.0 and is dual licensed under MS-PL or Apache 2.0, so it is safe to take into commercial work.
The CsvDataReader row is the one to read twice: it fills a DataTable straight from the reader, and every column in it arrives as a string, so any typing is ours to do afterwards.
Conclusion
In this article, we’ve seen how easy it is to read from a CSV file using CsvHelper. We also saw how to read a file with no header row, how to set a different delimiter and skip comment lines, how to stream a large file one row at a time, and how to read a CSV file with no library at all.
Tested with .NET 10.0.10 and CsvHelper 33.1.0.
Thanks!
You are most welcome.
i did not work man
Hi Eric. Have you tried using our source code? Then you can compare your solution with ours. Also, if you solve the issue, and you should find the difference as our source code must work, you can write here your solution or how you resolved your issue.