Updated on
A concurrent dictionary is a key-value collection several threads can read and write at the same time without a lock statement around it. In .NET that type is ConcurrentDictionary<TKey, TValue>, and it lives in the System.Collections.Concurrent namespace alongside the other concurrent collections.
Unlike a Dictionary with one lock bolted on, it reads without taking a lock and gives each write one of many fine-grained locks. Two threads writing to different parts of the dictionary usually do not wait for each other.
Two separate calls are still not atomic. Reading a value and then writing it back is a race, which is why the type ships compound methods such as AddOrUpdate(), GetOrAdd() and TryUpdate() that do both halves in one operation.
What Is a ConcurrentDictionary in C#?
ConcurrentDictionary<TKey, TValue> is a thread-safe key-value collection in the System.Collections.Concurrent namespace. Any number of threads can add, read, update and remove entries at the same time, and none of them needs a lock statement.
Keys are unique and unordered, exactly as in a plain Dictionary, but the cost model is different. Reads take no lock at all, and a write takes one of many fine-grained locks chosen by the key’s bucket, so two threads writing different keys usually proceed together.
Five compound methods exist because a single call is the only thing the type can make atomic. TryAdd(), which a plain Dictionary also has, adds only if the key is absent. GetOrAdd() returns the existing value or creates one. AddOrUpdate() inserts or recomputes in one call. TryUpdate() replaces a value only when it still matches the one we last read. TryRemove() removes an entry and hands the value back.
When keys are not what we need, the same namespace holds ConcurrentQueue<T>, ConcurrentStack<T> and ConcurrentBag<T> for first-in-first-out, last-in-first-out and unordered work.
Why Does a Plain Dictionary Break in Parallel Code?
Even the simplest examples of real-life concurrent solutions are usually pretty complex and threaten to take the focus to the subject of parallel programming. To avoid this, we will focus on the critical components and reduce everything else.
So, our examples will have:
- shared state in the dictionary
- concurrent processing steps that update the shared state
Let’s first try the naive approach:
public class NaiveExampleUnsized
{
    public const int MaxIterations = 100;
    public const int MaxStateEntries = 10;
    public const int ProcessingSteps = 40;
    private Dictionary<int, int> _sharedState = new();

    public void Run()
    {
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);

        PrintState();
    }

    private void ProcessingStep(int stepNumber)
    {
        for (int iteration = 0; iteration < MaxIterations; iteration++)
        {
            var entryKey = iteration % MaxStateEntries;
            if (!_sharedState.TryGetValue(entryKey, out int entryValue))
            {
                entryValue = 0;
            }
            _sharedState[entryKey] = entryValue + 1;
        }
    }

    private void PrintState()
    {
        foreach (var entry in _sharedState)
        {
            Console.WriteLine($"{entry.Key}\t{entry.Value}");
        }
    }
}
This class has an internal state represented by a simple Dictionary. Its processing requires multiple steps which can execute concurrently, and Parallel.ForEach() runs them that way. Each step needs to modify the state based on its current value (in this example it increments the entry value).
When we execute this example there is a high probability that we’ll see an exception such as this one:
Unhandled exception. System.AggregateException: One or more errors occurred. (Destination array was not long enough.
Check the destination index, length, and the array's lower bounds. (Parameter 'destinationArray')) ...
A little later in that very long string, we can also see the call stack of the inner exception:
System.ArgumentException: Destination array was not long enough. Check the destination index, length, and the array's lower bounds. (Parameter 'destinationArray')
   at System.Array.CopyImpl(Array sourceArray, Int32 sourceIndex, Array destinationArray, Int32 destinationIndex, Int32 length, Boolean reliable)
   at System.Array.Copy(Array sourceArray, Array destinationArray, Int32 length)
   at System.Collections.Generic.Dictionary`2.Resize(Int32 newSize, Boolean forceNewHashCodes)
   at System.Collections.Generic.Dictionary`2.TryInsert(TKey key, TValue value, InsertionBehavior behavior)
   at System.Collections.Generic.Dictionary`2.set_Item(TKey key, TValue value)
So what happens here is we try to insert an item into the dictionary and if there’s no room for another entry, the dictionary needs to resize. However, in the middle of the resize operation, some other task gets CPU time. It finds some of the internal structures already updated. This results in inconsistent internal array bounds.
Can We Avoid Resizing the Dictionary?
We may be tempted to size the dictionary properly to avoid this situation in the first place. Let’s change just the first highlighted line in our previous example:
private Dictionary<int, int> _sharedState = new(MaxStateEntries);
And execute to see the output similar to this:
0       361
1       355
2       350
3       351
4       350
5       352
6       355
7       340
8       344
9       354
Now, since we have 40 processing steps that increment each of the 10 entries 10 times, we would expect each entry to end at 400 (40 x 10 = 400).
However, not one of the entries has that value.
We suspect that from the time the value is read from the dictionary (_sharedState.TryGetValue(entryKey, out int entryValue)), before the new value is calculated and stored with the same key (_sharedState[entryKey] = entryValue + 1), another processing step manages to update the value, and that change is lost.
What Else Can We Try?
Surely we could avoid this problem if we reduce the time between reading and updating the value.
Let’s change our example to use the increment operator (++) to update it. We’ll even initialize the entries to reduce the chance of overwriting when the processing steps add the initial value:
public class SecondExample
{
    public const int MaxIterations = 100;
    public const int MaxStateEntries = 10;
    public const int ProcessingSteps = 40;
    private Dictionary<int, int> _sharedState = new(MaxStateEntries) { { 0, 0 }, { 1, 0 }, { 2, 0 },
                                                                       { 3, 0 }, { 4, 0 }, { 5, 0 },
                                                                       { 6, 0 }, { 7, 0 }, { 8, 0 },
                                                                       { 9, 0 }, };

    public void Run()
    {
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);

        PrintState();
    }

    private void ProcessingStep(int stepNumber)
    {
        for (int iteration = 0; iteration < MaxIterations; iteration++)
        {
            var entryKey = iteration % MaxStateEntries;
            _sharedState[entryKey]++;
            Thread.Sleep(1);
        }
    }

    private void PrintState()
    {
        foreach (var entry in _sharedState)
        {
            Console.WriteLine($"{entry.Key}\t{entry.Value}");
        }
    }
}
Alas, this approach didn’t help either because we still get a similar output. All or most of the entries have a value of less than 400.
ConcurrentDictionary to the Rescue
But we are not naive. We know that these attempts are futile. The right solution is either to synchronize the access to the dictionary or to use ConcurrentDictionary:
public class BetterApproach
{
    public const int MaxIterations = 100;
    public const int MaxStateEntries = 10;
    public const int ProcessingSteps = 40;
    private ConcurrentDictionary<int, int> _sharedState = new();

    public void Run()
    {
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);

        PrintState();
    }

    private void ProcessingStep(int stepNumber)
    {
        for (int iteration = 0; iteration < MaxIterations; iteration++)
        {
            var entryKey = iteration % MaxStateEntries;
            _sharedState.AddOrUpdate(
                entryKey,                                   // the key that we want to update
                key => 1,                                   // initial value factory, in case the key is not found
                (key, currentValue) => currentValue + 1);   // updated value factory, in case the key already exists
        }
    }

    private void PrintState()
    {
        foreach (var entry in _sharedState)
        {
            Console.WriteLine($"{entry.Key}\t{entry.Value}");
        }
    }
}
We see that we needed to adjust how we used the shared state. The if statement that decides when to initialize and when to update seems to be inside the ConcurrentDictionary – now we provide the initial value factory and updated value factory. We don’t even set the initial size.
This time around, however, we get consistent results each time:
0       400
1       400
2       400
3       400
4       400
5       400
6       400
7       400
8       400
9       400
Every entry has the expected value which is just what we wanted to accomplish.
How Does a ConcurrentDictionary Ensure Internal Consistency?
A single lock around the whole dictionary would keep it consistent, but every thread would queue behind every other one. The program would behave like a single-threaded one and pay for the locking on top.
The type splits the locking instead. Entries live in buckets, buckets are grouped, and each group has its own lock. A write usually locks only the group its key falls into, so two threads writing keys in different groups do not wait for each other.
Reads take no lock at all. A reader walks the bucket it needs and returns, which is why TryGetValue() and the indexer stay cheap no matter how many writers are running.
The number of locks is the concurrency level, and by default it is the processor count. Pass a value to the constructor and that number is fixed for the life of the dictionary. Use the parameterless constructor and the lock array doubles each time the dictionary grows, until it reaches 1,024 or more.
With eight buckets and four locks, two writers and one reader look like this:
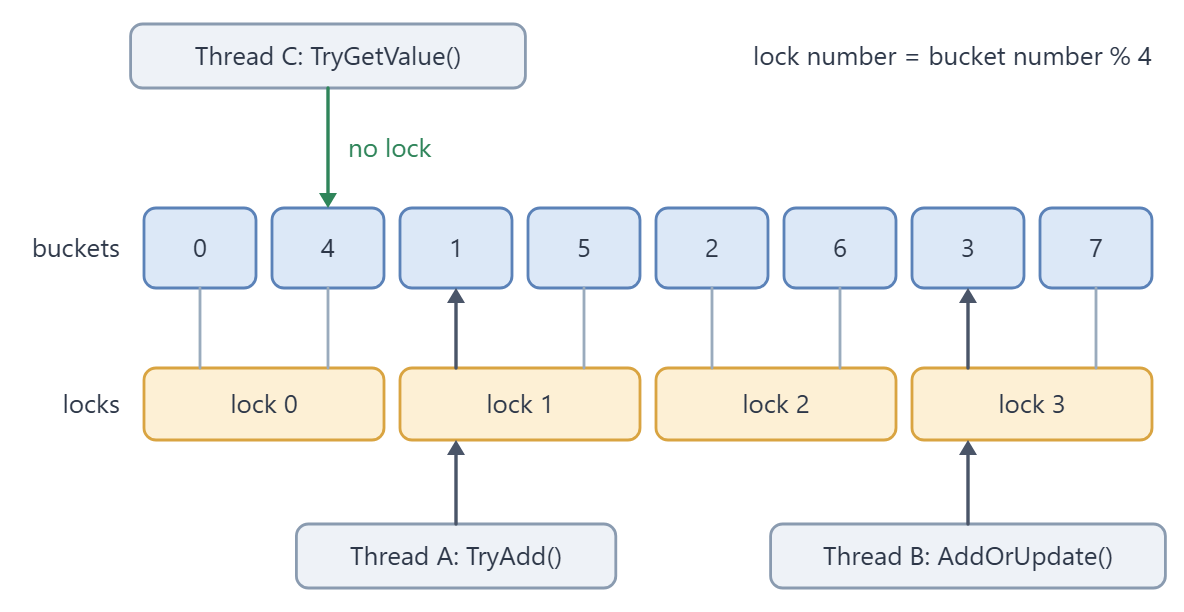
The frequency of these situations (without blocking) depends on the number of locks, which can change during the lifetime of the ConcurrentDictionary. If we do not set it explicitly via the concurrencyLevel constructor parameter, it will create the same number of locks as there are processors on the system. With the parameterless constructor, every time the dictionary decides to resize, it will double the number of locks until it reaches 1024 or more.
By locking one or more of these locks, ConcurrentDictionary ensures the consistency of its state and internal structures, but still allows a certain number of concurrent operations where possible.
But, enough of these details. If you want to read more about it, head out to the reference source.
Why Are Two Operations on a ConcurrentDictionary Still Unsafe?
Now that we know how ConcurrentDictionary protects its inner state, we can also think of some scenarios in which it can’t help us. Any action that would take two operations on a ConcurrentDictionary will still suffer from the same issues.
Let’s pretend we didn’t follow through, and that we still use the same method to update values:
public class AntipatternExample
{
    public const int MaxIterations = 100;
    public const int MaxStateEntries = 10;
    public const int ProcessingSteps = 40;
    private ConcurrentDictionary<int, int> _sharedState = new();

    public void Run()
    {
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);

        PrintState();
    }

    private void ProcessingStep(int stepNumber)
    {
        for (int iteration = 0; iteration < MaxIterations; iteration++)
        {
            var entryKey = iteration % MaxStateEntries;
            if (!_sharedState.TryGetValue(entryKey, out int entryValue))
            {
                _sharedState[entryKey] = 0;
            }
            _sharedState[entryKey]++;
            Thread.Sleep(1);
        }
    }

    private void PrintState()
    {
        foreach (var entry in _sharedState)
        {
            Console.WriteLine($"{entry.Key}\t{entry.Value}");
        }
    }
}
The output will demonstrate that some updates get overwritten:
0       303
1       279
2       310
3       309
4       308
5       318
6       287
7       306
8       286
9       288
A similar thing happens in other scenarios that may not be so obvious. For example, if we first call Count and assert it is greater than 0, a successive call to First() may throw an exception. Another example is calling ContainsKey() for a particular key: even when it returns true, another thread can remove that key before we read it, and the indexer then throws a KeyNotFoundException. TryGetValue() is the one-call form that cannot be caught out this way.
This is why a ConcurrentDictionary offers methods that take this into account, such as TryRemove() and TryUpdate(), which underline the possibility that the given key may not be present anymore. This is also why it sometimes needs to take all locks for some operations.
Which ConcurrentDictionary Method Should We Use to Add or Update?
Each compound method is one thread-safe call, and picking the wrong one puts us back in the two-call race the previous section describes.
TryAdd() is for inserting when we want to know whether we won. It returns false if the key was already there, and it leaves the existing value alone.
GetOrAdd() is for caches. It returns whatever is stored, creating a value first when nothing is.
AddOrUpdate() is for counters and accumulators, which is what this article’s example needs. It takes a key, a way to produce the first value, and a way to compute the next one from the current one.
TryUpdate() is for optimistic updates. It writes only when the stored value still equals the one we pass as the comparison, which is how we learn that somebody else got there first.
TryRemove() removes an entry and returns its value in a single call.
The table lists each method with what it returns and what to watch out for:
| Method | Use it when | Returns | Watch out for |
|---|---|---|---|
TryAdd(key, value) | The key should not already exist and we want to know if it did | false if the key was present; the stored value is untouched | Nothing. There is no factory to run twice |
GetOrAdd(key, value) | We have the value already and just want it stored once | The existing value, or the one we passed | The value is built even when it is not needed |
GetOrAdd(key, valueFactory) | Building the value is expensive, so we want it built only on a miss | The existing value, or the one the factory produced | The factory runs outside the lock and can run more than once for the same key |
GetOrAdd(key, valueFactory, arg) | The same, without capturing a variable into a closure | As above | As above |
AddOrUpdate(key, addValue, updateFactory) | The first value is a constant and later values depend on the current one | The new value | The update factory runs outside the lock and can run more than once |
AddOrUpdate(key, addFactory, updateFactory) | Both the first value and later values need computing | The new value | Both factories run outside the lock; this is the overload this article's example uses |
TryUpdate(key, newValue, comparisonValue) | We read a value, computed a new one, and will retry if it moved | false if the stored value no longer equals comparisonValue | Needs a retry loop to be useful |
TryRemove(key, out value) | We want the entry gone and its value back | false if the key was not there | Nothing |
ContainsKey(key) then the indexer | Never, from more than one thread | Two operations | Another thread can remove the key in between; the indexer throws KeyNotFoundException. Use TryGetValue() |
For the counter in this article, the answer is AddOrUpdate() with two factories, and the rest of the article sticks with it.
Which ConcurrentDictionary Members Take All the Locks?
Most of the type is cheap. A handful of members are not, because they cannot answer truthfully without freezing the whole dictionary first.
Count, Keys, Values, ToArray(), Clear() and the explicit CopyTo() implementations all take every lock the dictionary owns before they do their work. While one of them runs, no other thread can write anywhere in the dictionary.
foreach does not. The enumerator walks the buckets without taking a lock, which is why iterating is cheap and why the sequence we see may include writes made after we started. It is not a moment-in-time snapshot, and ToArray() is the method to call when we need one.
IsEmpty sits between the two. It checks the buckets without a lock first and returns immediately when it finds anything, so on a dictionary that has entries it takes no lock at all. Only a dictionary that really is empty makes it take the locks to confirm.
Let’s imagine that we need to detect which processing step finds the empty shared state. There are many ways to do this, but let’s suppose we’ve chosen LINQ method Any():
public class ContentionExample
{
    public const int MaxIterations = 100000;
    public const int MaxStateEntries = 10;
    public const int ProcessingSteps = 20;

    public IEnumerable<int> State => _sharedState.Values;

    private ConcurrentDictionary<int, int> _sharedState = new();

    private Func<bool> CheckStateIsEmpty = () => false;

    public void Run()
    {
        var stopwatch = Stopwatch.StartNew();
        RunWithEntryCheck();

        Console.WriteLine($"\nChecking entries processing took {stopwatch.Elapsed.TotalSeconds:N2} s.\n");

        stopwatch.Restart();
        RunWithKeysCheck();

        Console.WriteLine($"\nChecking keys processing took {stopwatch.Elapsed.TotalSeconds:N2} s.\n");
    }

    public void RunWithKeysCheck()
    {
        _sharedState = new();
        CheckStateIsEmpty = () => !_sharedState.Keys.Any();
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);
    }

    public void RunWithEntryCheck()
    {
        _sharedState = new();
        CheckStateIsEmpty = () => !_sharedState.Any();
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);
    }

    private void ProcessingStep(int stepNumber)
    {
        for (int iteration = 0; iteration < MaxIterations; iteration++)
        {
            var entryKey = iteration % MaxStateEntries;

            CheckStateIsEmpty();

            _sharedState.AddOrUpdate(
                entryKey,
                key => 1,
                (key, currentValue) => currentValue + 1);
        }
    }
}
Highlighted lines show the most important changes. We’ve increased the number of iterations and we measure and print running times for two very similar approaches. One approach checks are there Any() entries in the dictionary and other checks for Any() keys.
We can expect an output similar to this:
Checking entries processing took 1.22 s.

Checking keys processing took 1.38 s.
Results may vary, but most of the time we can see that the approach that checks the keys collection takes more time.
If we inspect the ConcurrentDictionary source in dotnet/runtime, we find a call to the AcquireAllLocks() method behind both checks. In .NET 10, LINQ’s Any() sees that the dictionary is an ICollection<T> and only reads its Count, which takes every lock. Keys takes every lock too, and then copies every key into a new array, which is the extra work the second approach pays for.
The full list of members that always take all the locks is Clear(), ToArray(), Count, Keys, Values, and the two explicit CopyTo() implementations. IsEmpty is the exception. It reads the buckets without a lock and returns as soon as it finds an entry, and it takes the locks only to confirm that the dictionary really is empty.
As with any other contention scenario, the slowdown this can cause greatly depends on the number of threads competing for the dictionary. So before you make any decisions about using or avoiding some of these methods, make sure you thoroughly test them with similar conditions that you expect in the production environment.
Can the AddOrUpdate Factories Leak Memory?
As we have already seen, to fully use the ConcurrentDictionary we should rely on its compound AddOrUpdate() method. It takes into account that until the very last moment, it’s not sure whether it will use the initial value or new value based on some existing. That’s why it expects us to provide a factory method for both scenarios.
Both factories run outside the dictionary’s locks, which is why more than one thread can be inside the same factory for the same key at once. Microsoft Learn documents it in the remarks for AddOrUpdate(): “The addValueFactory and updateValueFactory delegates may be executed multiple times to verify the value was added or updated as expected.”
This example uses both factories and counts how often each one runs:
public class MemoryLeakExample
{
    public const int MaxIterations = 100;
    public const int MaxStateEntries = 10;
    public const int ProcessingSteps = 20;

    public IEnumerable<int> State => _sharedState.Values;

    public int[] NewValueCreated { get; private set; } = new int[MaxStateEntries];

    public int[] UpdateValueCreated { get; private set; } = new int[MaxStateEntries];

    private ConcurrentDictionary<int, int> _sharedState = new();

    public void Run()
    {
        Parallel.ForEach(Enumerable.Range(0, ProcessingSteps), ProcessingStep);

        PrintState();
    }

    private void ProcessingStep(int stepNumber)
    {
        for (int iteration = 0; iteration < MaxIterations; iteration++)
        {
            var entryKey = iteration % MaxStateEntries;
            _sharedState.AddOrUpdate(
                entryKey,
                InitialValueFactory,
                UpdatedValueFactory);
        }
    }

    private int UpdatedValueFactory(int key, int currentValue)
    {
        Thread.Sleep(3);
        Interlocked.Increment(ref UpdateValueCreated[key]);
        return currentValue + 1;
    }

    private int InitialValueFactory(int key)
    {
        Thread.Sleep(3);
        Interlocked.Increment(ref NewValueCreated[key]);
        return 1;
    }

    private void PrintState()
    {
        foreach (var entry in _sharedState)
        {
            Console.WriteLine($"{entry.Key}\t{entry.Value}");
        }

        Console.WriteLine(new string('-', 20));

        for (int key = 0; key < MaxStateEntries; key++)
        {
            Console.WriteLine($@"Initial value for key [{key}] created {NewValueCreated[key]} times.");
        }

        Console.WriteLine(new string('-', 20));

        for (int key = 0; key < MaxStateEntries; key++)
        {
            Console.WriteLine($@"Update value for key [{key}] created {UpdateValueCreated[key]} times.");
        }
    }
}
We’ve extracted these factory methods and added counters to track the number of created values. We also added Thread.Sleep(3) to simulate some work required to construct the value. If you are not familiar with the Interlocked.Increment() function don’t worry. It will increment the given value atomically without any locking.
When we run this example we can see a lot more text on the output:
0       200
1       200
2       200
3       200
4       200
5       200
6       200
7       200
8       200
9       200
--------------------
Initial value for key [0] created 20 times.
Initial value for key [1] created 1 times.
Initial value for key [2] created 2 times.
Initial value for key [3] created 1 times.
Initial value for key [4] created 1 times.
Initial value for key [5] created 1 times.
Initial value for key [6] created 1 times.
Initial value for key [7] created 1 times.
Initial value for key [8] created 1 times.
Initial value for key [9] created 1 times.
--------------------
Update value for key [0] created 615 times.
Update value for key [1] created 424 times.
Update value for key [2] created 441 times.
Update value for key [3] created 453 times.
Update value for key [4] created 434 times.
Update value for key [5] created 449 times.
Update value for key [6] created 424 times.
Update value for key [7] created 432 times.
Update value for key [8] created 454 times.
Update value for key [9] created 449 times.
The first block shows us that the processing steps still complete all updates as expected. The second block, however, shows us that they invoked the initial value factory method more than once for some keys. Finally, the third block is the most surprising. We can see that the processing steps created more than twice the number of update values we expected.
In an example such as this, that’s not a problem, since we create initial values easily and unused values do not require additional work for disposal. But, in more complex examples in which we need to create unmanaged resources, we need to pay additional attention to properly dispose of unused values created by these factory methods. Otherwise, we can cause other problems with memory (handle) leaks.
Conclusion
As we have seen, ConcurrentDictionary in C# is a very straightforward alternative to a classic Dictionary when there is a shared state that we access from multiple concurrent threads. It minimizes the locking scope to allow greater concurrency while still keeping its internal state consistent. However, it does not solve all issues that arise in concurrent programming.
That’s why in some cases it may be simpler to protect the classic Dictionary by some other means, be it mutex, ReaderWriterLockSlim, or something else.
Tested with .NET 10.0.10.