Updated on
Base64 encoding rewrites binary data as text using a 64-character alphabet, so bytes can travel through channels that only carry text. In C# it is two static methods: Convert.ToBase64String() going out, and Convert.FromBase64String() coming back.
A string needs one extra step in each direction, because Base64 encodes bytes and a string is not bytes yet. We pick an encoding, usually UTF-8, on the way in, and we use the same one on the way out.
Everything else is a variation. Files and streams change how we feed the bytes in, Base64Url changes two characters of the alphabet so the output is safe in a URL, and the Try… methods change what happens when the input is malformed.
What Is Base64 Encoding?
Base64 encoding rewrites binary data as text, using a 64-character alphabet so bytes survive a channel that only carries text. That alphabet is the letters, the digits, + and /, with = reserved for padding.
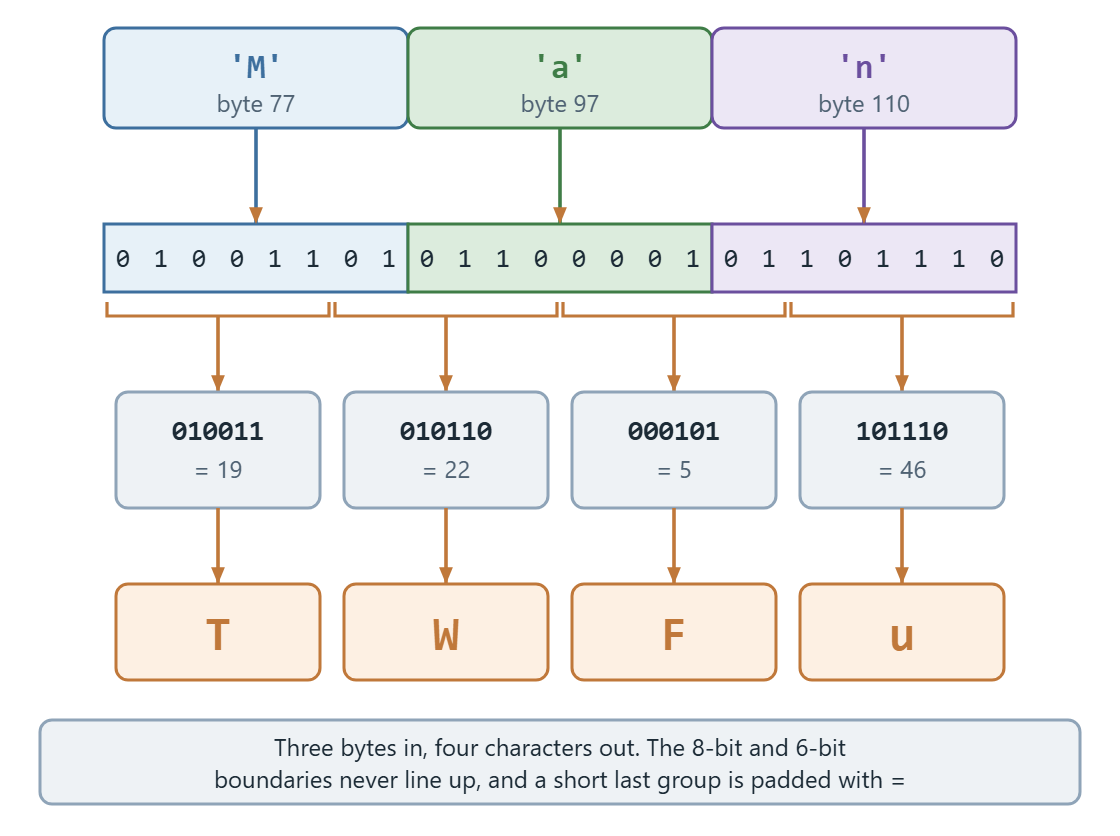
The mechanism is a regrouping, not a cipher. Base64 takes three bytes, which is 24 bits, and reads those same bits back as four groups of six. Each group is a number from 0 to 63, and that number picks one character. Three bytes in, four characters out.
That ratio is where the cost lives. Base64 output is always about a third larger than the input it describes, so a 3 MB image arrives as roughly 4 MB of text.
When the input is not a multiple of three bytes, the final group is short and = characters pad the output up to a multiple of four.
Base64 is not encryption and it is not compression. Anyone can decode it without a key, and the result is bigger than what went in.
The specification says so itself. RFC 4648, section 12 warns that base encoding “visually hides otherwise easily recognized information, such as passwords, but does not provide any computational confidentiality”, and names the exact accident it causes: someone pastes an encoded password into a bug report believing it is protected.
The regrouping is easier to see than to read about: three 8-bit boundaries and four 6-bit boundaries deliberately do not line up.
What Is Base64 Used For?
We can use Base64 to transmit a large amount of binary data within systems. Also, we can use Base64 to encode data inside files like HTML, CSS, and XML. Lastly, we can store files like XML and JSON in Base64.
Encoding is not a substitute for encryption, so anything that actually needs protecting is encrypted first and Base64-encoded afterwards if it also has to travel as text.
How Do We Encode a String to Base64 in C#?
Encoding a string takes two steps, because Base64 encodes bytes and a string is not bytes yet.
First we choose a text encoding and get the bytes out: Encoding.UTF8.GetBytes(text). That choice is part of the contract, not a detail. Encode with UTF-8, decode with UTF-16, and the round trip hands back mangled text rather than an error, which is the hardest kind of bug to find later.
Then we call Convert.ToBase64String(bytes), and that is the Base64 text.
ToBase64String() has five overloads rather than one method with four parameters. The widest takes four arguments: the byte array, an offset, a length, and a Base64FormattingOptions value. The offset and the length select one slice of the array, and they travel together.
Base64FormattingOptions.InsertLineBreaks is the only option worth knowing. It breaks the output every 76 characters, the line length MIME settled on for mail bodies.
On a hot path, Convert.TryToBase64Chars() writes into a Span<char> we already own instead of allocating a new string.
That first step has more to it than one method call, and converting a string to a byte array covers the encodings we can choose between.
The inArray Parameter
inArray is a required parameter and it’s an array of 8-bit unsigned integers. For instance, if we want to convert “Hello world!” to Base64, we need to get the bytes first. The resulting Base64 output is:
var textBytes = Encoding.UTF8.GetBytes("Hello world!");
// after: 72 101 108 108 111 32 119 111 114 108 100 33
var base64String = Convert.ToBase64String(textBytes);
// after: SGVsbG8gd29ybGQh
The offset Parameter
offset is an Int32 optional parameter. It states the position we want our encoding to start from. Using our last example of “Hello world!”, if we want to encode only “world!”, we will set our optional parameter to 6. We must pair this parameter with the length option to make it work. The 8-bit unsigned integer array for “world!” is 119 111 114 108 100 33.
Similarly, the Base64 output will be different from the result we got when all the value was encoded:
var textBytes = Encoding.UTF8.GetBytes("Hello world!");
// after: 72 101 108 108 111 32 119 111 114 108 100 33
var base64String = Convert.ToBase64String(textBytes, 6, 6);
// after: d29ybGQh
The length Parameter
length is an optional Int32 parameter. This parameter works hand-in-hand with the offset parameter. We can use this parameter to state the number of elements or variables we want to encode. Using the last example, the value for this parameter was 6.
The options Parameter
We can use the options parameter to insert line breaks within our Base64 output. Line breaks can improve the readability of our Base64 text and also assist us while using tools that don’t deal well with long lines. The options parameter is optional. Conversely, the encoding scheme will add a line break for every 76 characters.
76 characters was to provide a way to include binary files in e-mails and Usenet postings which was intended for humans using monitors with 80 characters width. The number itself comes from MIME’s own rule for mail bodies: RFC 2045, section 6.8 requires that the “encoded output stream must be represented in lines of no more than 76 characters each”.This value cannot be modified because the value was defined in RFC 2045. To see this in action, we’ll use a text with more characters:
var textBytes = Encoding.UTF8.GetBytes("The great crocodile of Queensland can attain a length of 30 feet");
var base64String = Convert.ToBase64String(textBytes, Base64FormattingOptions.InsertLineBreaks);
// after: VGhlIGdyZWF0IGNyb2NvZGlsZSBvZiBRdWVlbnNsYW5kIGNhbiBhdHRhaW4gYSBsZW5ndGggb2Yg
//        MzAgZmVldA==
We can see that the value has been broken into two lines.
How Do We Decode a Base64 String in C#?
Convert.FromBase64String(text) reverses the encode and hands back a byte[]. Turning those bytes into readable text is the second step, and it has to use the same encoding the first step used: Encoding.UTF8.GetString(bytes).
Whitespace costs nothing. Microsoft’s FromBase64String reference documents that tab, line feed, carriage return and space are all ignored, and that any number of them can appear anywhere in the input. A payload wrapped at 76 characters therefore decodes without being joined back into one line first.
Everything else throws. FromBase64String() raises a FormatException when the length, ignoring whitespace, is not a multiple of four, when a character outside the alphabet appears, when there are more than two padding characters, or when a non-whitespace character sits among the padding.
That makes it the wrong method for input we did not produce. Convert.TryFromBase64String() writes into a Span<byte> we supply and returns false instead of throwing, which turns a validation question back into an if.
// before: d29ybGQh
var base64EncodedBytes = Convert.FromBase64String(base64String);
// after: 119 111 114 108 100 33
var inputString = Encoding.UTF8.GetString(base64EncodedBytes);
// after: world!
Between them, System.Convert carries eleven Base64 members, and which one we want comes down to what we already have and what we want back:
| Method | Converts | On bad input |
|---|---|---|
Convert.ToBase64String(byte[]) | bytes to a Base64 string | not applicable |
Convert.ToBase64String(byte[], Base64FormattingOptions) | bytes to a Base64 string, optionally with line breaks | not applicable |
Convert.ToBase64String(byte[], int, int) | one slice of the array | throws on a bad offset or length |
Convert.ToBase64String(byte[], int, int, Base64FormattingOptions) | one slice, optionally with line breaks | throws on a bad offset or length |
Convert.ToBase64String(ReadOnlySpan<byte>, Base64FormattingOptions) | a span of bytes, no array needed | not applicable |
Convert.ToBase64CharArray(byte[], int, int, char[], int) | bytes into a char[] we already own | throws if the buffer is too small |
Convert.TryToBase64Chars(ReadOnlySpan<byte>, Span<char>, out int, Base64FormattingOptions) | bytes into a Span<char> we already own | returns false |
Convert.FromBase64String(string) | a Base64 string back to bytes | throws FormatException |
Convert.FromBase64CharArray(char[], int, int) | one slice of a char[] back to bytes | throws FormatException |
Convert.TryFromBase64String(string, Span<byte>, out int) | a Base64 string into a Span<byte> we own | returns false |
Convert.TryFromBase64Chars(ReadOnlySpan<char>, Span<byte>, out int) | Base64 characters into a Span<byte> we own | returns false |
How Do We Base64 Encode a File or Stream in C#?
For a file small enough to sit in memory, this is one line in each direction. Convert.ToBase64String(File.ReadAllBytes(path)) gives us the Base64 text, and File.WriteAllBytes(path, Convert.FromBase64String(text)) writes the bytes back out to disk.
That second line is the whole answer to turning a Base64 string into a PDF or an image. There is no PDF-specific step, because Base64 does not know or care what the bytes mean.
Size is the catch. The byte array and the Base64 string are both in memory at once, so a large file is held more than twice over before anything is written.
Microsoft points elsewhere for that case. Its FromBase64String reference says the method is designed to process a single string containing all the data, and names FromBase64Transform for stream data instead.
Wrapping ToBase64Transform or FromBase64Transform in a CryptoStream converts the data in fixed-size blocks, one block at a time.
The whole-file pair is two methods, and reading a whole file into a byte array is the half of it that does the work:
public string EncodeFile(string path)
{
    return Convert.ToBase64String(File.ReadAllBytes(path));
}

public void DecodeToFile(string base64EncodedText, string path)
{
    File.WriteAllBytes(path, Convert.FromBase64String(base64EncodedText));
}
DecodeToFile() is also all there is to writing a byte array back out as a file, whether those bytes are a PDF, a PNG, or anything else.
For the streaming case, the transform goes into a CryptoStream and we copy the input through it:
public void EncodeStream(Stream input, Stream output)
{
    using var transform = new ToBase64Transform();
    using var cryptoStream = new CryptoStream(output, transform, CryptoStreamMode.Write, leaveOpen: true);

    input.CopyTo(cryptoStream);
}
Swapping ToBase64Transform for FromBase64Transform gives us the decode direction. The sample project asserts that the streamed output is byte-for-byte identical to Convert.ToBase64String() on the same input, so the two paths agree rather than merely both running.
What Is Base64Url, and When Do We Need It?
Standard Base64 uses + and /, and both of those mean something else inside a URL. Base64Url is the same encoding with - and _ in their places, and with the trailing = padding left off.
This is a different job from URL encoding, and the two are not alternatives. Percent-encoding escapes characters inside a URL that is already text; Base64Url decides which alphabet the binary was turned into in the first place. A JWT is Base64Url in all three of its parts, which is why a token drops into a query string with nothing done to it.
.NET 9 added a type for it: System.Buffers.Text.Base64Url. Base64Url.EncodeToString(bytes) produces the text, and Base64Url.DecodeFromChars(text) reads it back into bytes.
Before .NET 9, the usual approach was a chain of Replace() calls over Convert.ToBase64String() output, swapping the two characters and trimming the padding by hand. That still works, and it is now unnecessary.
Both directions are one line each:
public string Base64UrlEncoding(string text)
{
    return Base64Url.EncodeToString(Encoding.UTF8.GetBytes(text));
}

public string Base64UrlDecoding(string base64UrlEncodedText)
{
    return Encoding.UTF8.GetString(Base64Url.DecodeFromChars(base64UrlEncodedText));
}
The alphabet swap is visible on any input whose bytes land on those two characters, and the padding is simply absent:
Convert.ToBase64String([0xFB, 0xFF, 0xFE])  ->  +//+
Base64Url.EncodeToString([0xFB, 0xFF, 0xFE])  ->  -__-

Convert.ToBase64String([0x41])   ->  QQ==
Base64Url.EncodeToString([0x41])   ->  QQ
That is the part that matters for tokens, and decoding a JWT is Base64Url three times over. It is a separate question from URL encoding, which solves a different problem: escaping characters inside a URL that is already text.
Conclusion
In this article, we’ve learned how to Base64 encode and decode in C#. In addition, we’ve shown how to encode a string to Base64 and vice-versa, how to run a file or a stream through the same conversion, and when to reach for Base64Url instead.
Tested with .NET 10.
There is a BinaryData class that has helper methods for Base64 plus others.
https://docs.microsoft.com/en-us/dotnet/api/system.binarydata
Hey Paul, which helper methods are you referring to?