Updated on
list.Distinct().ToList() removes duplicates from a list in C#. It is a LINQ method, its values come out in the order they first appear, and it is the right answer unless one of three things is true.
If the list holds objects of a plain class rather than numbers or strings, Distinct() compares references and keeps every separate instance, and we want DistinctBy() with a key selector instead. If we need the list we already hold to change rather than a new one, we want RemoveAll() with a HashSet<T>. If we need the set itself afterwards, we stop at ToHashSet() and skip the conversion back.
The other approaches in this article are variations on those three ideas, plus a few worth knowing only so we can recognise them in someone else’s code.
We already dealt with this problem when the collection is an array, and if you are interested in this topic you can check the Remove Duplicates From a C# Array article.
How Do We Remove Duplicates From a List With LINQ?
Here are three LINQ ways to drop duplicates, and Distinct() is the one to reach for.
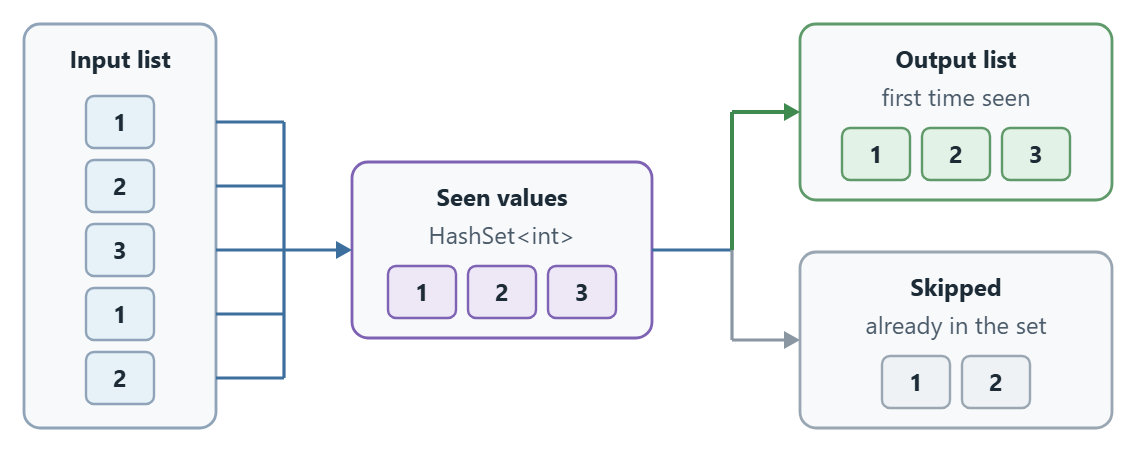
Distinct() walks the sequence once, keeping a set of the values it has already seen, and yields each value the first time it appears. Values come out in first-appearance order, the result is an IEnumerable<T>, and ToList() turns it back into a list.
GroupBy(x => x).Select(g => g.First()) produces the same values. It also builds every group in memory before handing back one element from each, which is work we do not need when the key and the value are the same thing.
Union() is a set operation over two sequences, so calling it with the same list twice is a trick. It removes duplicates because every set operation does, but a reader meeting list.Union(list) has to stop and work out why.
All three compare values with the default equality comparer, which is the detail that decides whether any of them work on a list of objects.
We begin by creating a list containing some duplicates:
List<int> listWithDuplicates = new List<int>() { 1, 2, 3, 4, 1, 2, 3, 4 };
We want to make the listWithDuplicates contain every number only once { 1, 2, 3, 4 }.
Using Distinct()
The first method we use is the LINQ Distinct():
listWithDuplicates.Distinct().ToList();
The Distinct() method does exactly what we need for a list of numbers: it removes the duplicates. A list of objects needs more than that, which the objects section below covers. It returns an IEnumerable<int> result and that’s why we need to perform ToList() if we need a list.
The single pass through a set of seen values is also what ToHashSet(), TryAdd() and RemoveAll() do underneath, which is why the table at the end of the article rates all four as linear:
Using GroupBy() and Select() Combo
Going forward with LINQ methods, we can also perform:
listWithDuplicates.GroupBy(x => x).Select(d => d.First()).ToList();
In this case, we first group equal elements in listWithDuplicates using the GroupBy() method. For each group of equal elements, we return the first one with Select(). Since this operation returns an IEnumerable<int>, we invoke ToList() at the end.
Using Union()
The Union() method creates a union between two sequences, using the default equality comparer. The union of two lists contains the elements from both, excluding duplicates:
listWithDuplicates.Union(listWithDuplicates).ToList();
Here, we perform the union between listWithDuplicates and itself. This operation produces an IEnumerable<T> without duplicates and we convert into a List<T> with ToList().
Written this way it is just a slower Distinct(): in the benchmark at the end of the article it takes 39.570 us against 16.056 us for Distinct() at 2,000 distinct values. Union() earns its place when the second sequence is a different list, like the other set operations, such as finding what is in one collection and not another with Except().
Which Collections Remove Duplicates for Us?
Every method on this page checks whether a value is new, and the collections make that check explicit.
ToHashSet() builds a HashSet<T>, which cannot hold the same value twice, and ToList() copies the result back into a list. new HashSet<T>(list) does the same work through the constructor rather than the extension method, so the two produce the same list and the choice between them is style.
A Dictionary<TKey, TValue> works for the same reason, because its keys are unique too. TryAdd() returns false instead of throwing when the key is already present, so the loop needs no check of its own, and dict.Keys holds the distinct values once it ends.
The empty-list approach is the odd one out and the only one here that is not a hash lookup. Contains() scans the new list from the start for every item, so its cost grows with the number of distinct values found so far.
HashSet
HashSet<T> represents an unordered collection that contains no duplicate elements:
listWithDuplicates.ToHashSet().ToList();
In this case, we convert the list into a HashSet<T>, and this operation returns a HashSet<T> without duplicates. Then, we convert it into a List<T>.
Another interesting use of HashSet<T> is to initialize a HashSet<T> from listWithDuplicates and then converting back to a list:
new HashSet<int>(listWithDuplicates).ToList();
In this case, when we initialize the HashSet, the set rejects every value it already holds, so the duplicates never make it in.
De-duplication is only one use of a set, and we cover what a HashSet<T> is and what else it can do in a separate article.
Dictionary
A Dictionary<TKey,TValue> maps a set of keys to a set of values:
var dict = new Dictionary<int, int>();

foreach (var s in listWithDuplicates)
{
     dict.TryAdd(s, 1);
}

var distinctList = dict.Keys.ToList();
In the foreach loop, we call TryAdd(), that adds an item to the keys of the dictionary only if it is not already contained, since a key in a dictionary must be unique. When we exit from the loop, we take the keys and convert the collection to a list.
Empty List
We can also add the unique elements to another list:
var listWithoutDuplicates = new List<int>();

foreach (int item in listWithDuplicates)
{
    if (!listWithoutDuplicates.Contains(item)) //we can also use !listWithoutDuplicates.Any(x => x.Equals(item))
    {
        listWithoutDuplicates.Add(item);
    }
}
We check if listWithoutDuplicates already contains an item in the foreach loop, and if it doesn’t we add it. To verify it, we use the List<T>.Contains() method, which scans the list item by item. We can also use the LINQ Any() method with an Equals() call, which does the same scan and calls the lambda for every item it checks, and we will see how much that difference costs in the performance section.
How Do We Remove Duplicates From a List of Objects?
Distinct() uses the type’s own idea of equality, which is why it keeps every separate instance in a list of plain classes.
Two Person objects holding identical values are still two different references, and a plain class inherits reference equality, so Distinct() keeps both. Measured on .NET 10.0.10 on 2026-09-12: a list of two Person instances with the same name and age comes back with two items in it.
There are three ways out. Declare the type as a record, which generates value equality from its members, and the same list comes back with one item. Override Equals() and GetHashCode() on the class, which is what the record generates for us. Or leave equality alone and call DistinctBy(), added in .NET 6, which takes a key selector: people.DistinctBy(p => p.Email) keeps the first person for each email address.
DistinctBy() is usually the right answer, because the rule for what counts as a duplicate belongs to this query rather than to the type.
This does not work. We define a plain Person class:
public class Person
{
    public required string Name { get; init; }
    public required int Age { get; init; }
    public required string Email { get; init; }
}
Then we put two people with the same values in a list and call Distinct():
var people = new List<Person>
{
    new() { Name = "Ann", Age = 30, Email = "[email protected]" },
    new() { Name = "Ann", Age = 30, Email = "[email protected]" }
};

var distinctPeople = people.Distinct().ToList(); // still 2 items
Both people survive, because the default comparer for a class falls back to reference equality and these are two different objects. It is worth reading how equality actually works for a class before we override Equals() and GetHashCode() ourselves.
A positional record with the same members behaves the way we expected the class to:
public record PersonRecord(string Name, int Age, string Email);
var people = new List<PersonRecord>
{
    new("Ann", 30, "[email protected]"),
    new("Ann", 30, "[email protected]")
};

var distinctPeople = people.Distinct().ToList(); // 1 item
That works because of records, which generate value equality from their members. When we cannot change the type, or when two people count as the same for this query only, we keep the class and pass a key to DistinctBy():
var distinctPeople = people.DistinctBy(p => p.Email).ToList();
Here, people is the List<Person> from the first example, and the call keeps the first person for each email address. DistinctBy() came with the rest of the key-selector methods .NET 6 added to LINQ.
How Do We Remove Duplicates in Place?
Every approach so far builds a new list. Removing the duplicates from the list we already hold takes one line.
We declare a HashSet<T> and then call list.RemoveAll(x => !seen.Add(x)). HashSet<T>.Add() returns true the first time it meets a value and false every time after that, so the predicate is true for exactly the repeats, and RemoveAll() deletes them in a single pass while the surviving items keep their order. Measured on .NET 10.0.10 on 2026-09-12: a list holding 1, 1, 2, 3, 4, 5 becomes 1, 2, 3, 4, 5, and it is still the same list instance.
This matters when anything else holds a reference to the same list. Writing list = list.Distinct().ToList() gives us a clean list and leaves every other holder pointing at the original one, duplicates included, which is a bug that surfaces a long way from the line that caused it.
Applied to our list, it looks like this:
var seen = new HashSet<int>();
listWithDuplicates.RemoveAll(x => !seen.Add(x));
After the call, listWithDuplicates is the same list instance and holds { 1, 2, 3, 4 }.
How Do the Manual Loop Approaches Work?
We can also remove duplicate elements with nested loops and no helper collection at all. Both versions below take far more code than any approach above. They are here because we still meet them in older codebases, so it helps to know how they work and where they go wrong.
Shifting
Do not write this yourself. Here is how the shifting version works, on a copy of the list:
var list = new List<int>(listWithDuplicates);
var n = list.Count;

for (int i = 0; i < n; i++)
{
    for (int j = i + 1; j < n; j++)
    {
        if (list[i].Equals(list[j]))
        {
            for (int k = j; k < n - 1; k++)
            {
                list[k] = list[k + 1];
            }
            j--;
            n--;
        }
    }
}

var distinctList = list.Take(n).ToList();
Starting from index i = 0, we evaluate all the items starting from the index j = i + 1. If we find that i-th element is equal to the j-th element, then we shift every item to the left, starting from j up to n - 1, by writing each item over the one before it.
Every time we find a duplicate, the size of the final list decreases by one. When we get out of the loops we will take the first n distinct items contained in list with Take() method.
The line that does the work is list[k] = list[k + 1];. A version that copies the item into a local variable instead compiles, runs and never changes the list, so Take(n) only cuts the list short. It looks correct on a list whose duplicates all sit at the end, and on { 1, 1, 2, 3, 4, 5 } it returns { 1 }.
Swapping
As already suggested in the article for the removal of duplicates from the array, the iterative method can be improved with the swapping of elements in the loop. Do not write this one yourself either:
var list = new List<int>(listWithDuplicates);
var size = list.Count;

for (int i = 0; i < size; i++)
{
    for (int j = i + 1; j < size; j++)
    {
        if (list[i].Equals(list[j]))
        {
            size--;
            (list[j], list[size]) = (list[size], list[j]);
            j--;
        }
    }
}

var distinctList = list.Take(size).ToList();
When the j-th item is a duplicate, we decrease size by one and swap the duplicate with the item at index size, the last one still in play. Then we check index j again, because the item that just moved there can be a duplicate too. When we exit from the loop, we take the first size items of list.
Swapping makes one swap per duplicate instead of shifting every item after it, but it does not keep the order: on { 1, 1, 2, 3, 4, 5 } it returns { 1, 5, 2, 3, 4 }. While similar to the previous approach, there are some performance implications that we’re going to explore at the end.
We show both loops so that we recognise the pattern when we find it in old code. In new code, Distinct(), DistinctBy() or RemoveAll() with a HashSet<T> does the same job in one line.
Recursive Approach
The recursion provides another considerable way to perform the removal of duplicates, with a method that goes inside a class:
public List<int> UsingRecursion(List<int>? listWithDuplicates, List<int>? listWithoutDuplicates = default, int index = 0)
{
    if (listWithoutDuplicates == null)
    {
        listWithoutDuplicates = new List<int>();
    }
    if (index >= listWithDuplicates.Count)
    {
        return listWithoutDuplicates;
    }
    if (listWithoutDuplicates.IndexOf(listWithDuplicates[index]) < 0)
    {
        listWithoutDuplicates.Add(listWithDuplicates[index]);
    }

    UsingRecursion(listWithDuplicates, listWithoutDuplicates, index + 1);

    return listWithoutDuplicates.ToList();
}
In this case, we initialize listWithoutDuplicates as an empty list if it is null, and we check if the list contains an item that occupies the position given by index using the IndexOf() method.
If listWithoutDuplicates doesn’t contain the element, we add it to another list, and either way we call again the UsingRecursion() method passing index incremented by one. The recursion stops when the passed value of index is greater than or equal to the size of the list.
Sorting
If we sort the list, we can compare elements two by two:
var listWithoutDuplicates = new List<int>();
listWithDuplicates = listWithDuplicates.OrderBy(x => x).ToList();
int element = default;
foreach (int result in listWithDuplicates)
{
    if (listWithoutDuplicates.Count == 0 || !result.Equals(element))
    {
        listWithoutDuplicates.Add(result);
        element = result;
    }
}
We start by defining a new empty listWithoutDuplicates, sorting listWithDuplicates in ascending order, and defining the variable element with the default value. Then we loop over the items, add the first one, and compare every other one with the element, adding it to listWithoutDuplicates only if it doesn’t contain it yet. After the eventual addition, we assign to element the current value in the loop.
The result comes back sorted rather than in the original order. Sorting itself, including lists of objects, has its own article on sorting a list of objects by property.
Which Way of Removing Duplicates Is Fastest?
We want to show the differences in terms of performance between the methods explored so far, using BenchmarkDotNet. Every case holds 2,000 items, and only the number of distinct values changes: 3, 100 or 2,000. That number decides the ranking, so we measure each method at all three:
BenchmarkDotNet v0.15.8, Windows 10 (10.0.19045.6466/22H2/2022Update)
AMD Ryzen 5 3600 3.60GHz, 1 CPU, 12 logical and 6 physical cores
.NET SDK 10.0.302
  [Host]     : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3
  DefaultJob : .NET 10.0.10 (10.0.10, 10.0.1026.32716), X64 RyuJIT x86-64-v3

| Method                      | DistinctValues | Mean         | Error      | StdDev     | Median       | Rank | Gen0      | Gen1    | Allocated  |
|---------------------------- |--------------- |-------------:|-----------:|-----------:|-------------:|-----:|----------:|--------:|-----------:|
| DictionaryMethod            | 3              |     6.484 us |  0.2165 us |  0.6382 us |     6.391 us |    1 |    0.0305 |       - |      288 B |
| DictionaryMethod            | 100            |     7.131 us |  0.1416 us |  0.2694 us |     7.107 us |    2 |    0.9384 |  0.0153 |     7872 B |
| IterationsAndSwappingMethod | 3              |     8.403 us |  0.2159 us |  0.6297 us |     8.329 us |    3 |    0.9766 |  0.0153 |     8176 B |
| EmptyListWithContainsMethod | 3              |    10.030 us |  0.2624 us |  0.7654 us |    10.028 us |    4 |         - |       - |       72 B |
| InitializingHashSetMethod   | 100            |    11.726 us |  0.2459 us |  0.7094 us |    11.671 us |    5 |    4.7302 |  0.6714 |    39712 B |
| ConvertToHashSetMethod      | 100            |    11.772 us |  0.2493 us |  0.7350 us |    11.692 us |    5 |    4.7302 |  0.6714 |    39712 B |
| RemoveAllInPlaceMethod      | 100            |    12.432 us |  0.2300 us |  0.3905 us |    12.408 us |    5 |    1.6785 |  0.0610 |    14080 B |
| InitializingHashSetMethod   | 3              |    13.430 us |  0.7516 us |  2.2160 us |    13.024 us |    5 |    4.4556 |  0.6104 |    37664 B |
| RemoveAllInPlaceMethod      | 3              |    13.605 us |  0.3553 us |  1.0476 us |    13.602 us |    5 |    0.9766 |  0.0153 |     8248 B |
| DistinctLINQMethod          | 100            |    13.703 us |  0.4356 us |  1.2568 us |    13.744 us |    5 |    4.7302 |  0.6714 |    39776 B |
| ConvertToHashSetMethod      | 3              |    13.938 us |  0.4968 us |  1.4647 us |    13.839 us |    5 |    4.4708 |  0.6256 |    37664 B |
| EmptyListWithContainsMethod | 100            |    14.123 us |  0.2751 us |  0.3274 us |    14.113 us |    5 |    0.1221 |       - |     1184 B |
| DistinctLINQMethod          | 3              |    14.620 us |  0.8026 us |  2.3664 us |    14.197 us |    5 |    4.5013 |  0.6409 |    37728 B |
| DistinctLINQMethod          | 2000           |    16.056 us |  0.3177 us |  0.7105 us |    15.906 us |    5 |    5.4321 |  0.6714 |    45608 B |
| InitializingHashSetMethod   | 2000           |    16.138 us |  0.3225 us |  0.7146 us |    16.132 us |    5 |    5.4321 |  0.6714 |    45544 B |
| ConvertToHashSetMethod      | 2000           |    16.220 us |  0.3204 us |  0.8039 us |    16.000 us |    5 |    5.4321 |  0.6714 |    45544 B |
| DictionaryMethod            | 2000           |    21.745 us |  0.4340 us |  1.1281 us |    21.579 us |    6 |   19.2261 |  6.3782 |   162280 B |
| RemoveAllInPlaceMethod      | 2000           |    21.817 us |  0.4354 us |  1.1546 us |    21.356 us |    6 |   15.6250 |  5.1880 |   131584 B |
| GroupByLINQMethod           | 3              |    22.030 us |  0.6686 us |  1.9714 us |    21.839 us |    6 |    3.0823 |  0.1831 |    25904 B |
| UnionLINQMethod             | 100            |    23.326 us |  0.5860 us |  1.7278 us |    23.187 us |    6 |    0.7629 |       - |     6608 B |
| UnionLINQMethod             | 3              |    23.731 us |  0.8231 us |  2.4270 us |    23.820 us |    6 |    0.0305 |       - |      392 B |
| GroupByLINQMethod           | 100            |    28.896 us |  0.7088 us |  2.0900 us |    28.835 us |    7 |    5.7678 |  0.4578 |    48336 B |
| EmptyListWithAnyMethod      | 3              |    33.294 us |  1.2430 us |  3.6651 us |    32.566 us |    8 |   21.0266 |       - |   176072 B |
| UnionLINQMethod             | 2000           |    39.570 us |  0.7706 us |  1.3085 us |    39.539 us |    9 |   15.6860 |  3.9063 |   131712 B |
| RecursiveMethod             | 3              |    49.741 us |  1.4465 us |  4.2649 us |    49.189 us |   10 |   17.2119 |       - |   144072 B |
| GroupByLINQMethod           | 2000           |    65.568 us |  1.3071 us |  2.9504 us |    64.500 us |   11 |   25.8789 | 11.9629 |   217080 B |
| EmptyListWithAnyMethod      | 100            |    79.603 us |  1.5570 us |  3.7900 us |    78.639 us |   12 |   21.1182 |       - |   177184 B |
| IterationsAndSwappingMethod | 100            |    98.142 us |  1.9130 us |  2.8040 us |    98.122 us |   13 |    0.9766 |       - |     8560 B |
| SortMethod                  | 2000           |   107.436 us |  0.6451 us |  0.5387 us |   107.480 us |   14 |    6.7139 |  0.6104 |    57032 B |
| SortMethod                  | 3              |   109.543 us |  2.1868 us |  6.1679 us |   109.431 us |   14 |    4.7607 |  0.3662 |    40464 B |
| RecursiveMethod             | 100            |   118.791 us |  2.5553 us |  7.4133 us |   117.217 us |   15 |  109.1309 |       - |   913184 B |
| EmptyListWithContainsMethod | 2000           |   122.305 us |  0.8156 us |  0.6368 us |   122.280 us |   15 |    1.9531 |       - |    16640 B |
| SortMethod                  | 100            |   140.934 us |  2.7667 us |  3.3977 us |   141.296 us |   16 |    4.8828 |  0.2441 |    41576 B |
| EmptyListWithAnyMethod      | 2000           |   827.892 us | 16.5329 us | 21.4974 us |   821.146 us |   17 |   22.4609 |       - |   192640 B |
| RecursiveMethod             | 2000           | 1,454.749 us | 28.8228 us | 56.8933 us | 1,440.155 us |   18 | 1925.7813 | 31.2500 | 16128640 B |
| IterationsAndSwappingMethod | 2000           | 1,632.722 us |  8.2963 us |  7.3545 us | 1,631.318 us |   19 |         - |       - |    16160 B |
| IterationsAndShiftingMethod | 100            | 1,807.942 us | 26.1941 us | 24.5020 us | 1,806.838 us |   20 |         - |       - |     8560 B |
| IterationsAndShiftingMethod | 2000           | 2,064.056 us | 39.8543 us | 40.9274 us | 2,055.418 us |   21 |         - |       - |    16160 B |
| IterationsAndShiftingMethod | 3              | 2,498.053 us | 39.9566 us | 37.3754 us | 2,500.956 us |   22 |         - |       - |     8176 B |
The ranking depends on how many distinct values the list holds. With 3 distinct values, the empty list with Contains() takes 10.030 us and beats Distinct() at 14.620 us, because Contains() never scans more than three items. By 100 distinct values every HashSet<T> and Dictionary approach is ahead of it. At 2,000 it takes 122.305 us against 16.056 us for Distinct(), about 7.6 times slower, because its cost grows with the number of values it has already kept, while the hash-based approaches stay linear.
Dictionary with TryAdd() is the fastest method with 3 and 100 distinct values, at 6.484 us and 7.131 us. At 2,000 it falls behind Distinct() and both HashSet<T> methods, at 21.745 us. Distinct(), ToHashSet() and the HashSet<T> constructor stay between 11.7 and 16.3 us in every case, so the choice between them is not a performance question.
Any() is the expensive way to write the Contains() check. At 2,000 distinct values it takes 827.892 us, 6.8 times the Contains() time, and allocates 192,640 bytes against 16,640, because every call allocates a new closure and delegate for the lambda and then calls it for every item, while Contains() searches a list of int values with vectorized code.
The manual loops show why shifting is the worse of the two. With 3 distinct values, swapping takes 8.403 us and shifting takes 2,498.053 us, because shifting moves every later item for each of the 1,997 duplicates, while swapping makes one swap. With 2,000 distinct values there is nothing to move, and both loops, along with Any() and the recursion, are the four slowest methods at that size, between 828 and 2,064 us.
The SortMethod and RemoveAllInPlaceMethod rows include copying the 2,000-item source list on every call, because both methods change the list they work on.
The table below sums up every approach in this article:
| Approach | Call | Order kept | Cost | Reach for it when |
|---|---|---|---|---|
Distinct() | list.Distinct().ToList() | Yes | Linear | Always, unless a row below applies |
DistinctBy() | list.DistinctBy(x => x.Key).ToList() | Yes | Linear | Duplicates are defined by one property (.NET 6 and later) |
HashSet<T> | list.ToHashSet().ToList() | Not guaranteed | Linear | We want the set itself, not a list |
Dictionary + TryAdd() | dict.TryAdd(item, 1) in a loop | Yes | Linear; the fastest row with few distinct values | We need a value per unique key as well |
RemoveAll() + HashSet<T> | list.RemoveAll(x => !seen.Add(x)) | Yes | Linear | The existing list must change in place |
GroupBy() + First() | list.GroupBy(x => x).Select(g => g.First()) | Yes | Linear, but slower than Distinct() | We also need the group counts |
Union() with itself | list.Union(list).ToList() | Yes | Linear | Never; this is Distinct() written obscurely |
Empty list + Contains() | if (!result.Contains(item)) result.Add(item) | Yes | Quadratic when most values are distinct | The list holds only a handful of distinct values |
Empty list + Any() | if (!result.Any(x => x.Equals(item))) | Yes | Quadratic; 6.8 times slower than Contains() at 2,000 distinct values | Never; Contains() is the same check without the delegate |
| Sorting, then comparing neighbours | list.OrderBy(x => x) then one pass | No, the result is sorted | n log n | We wanted it sorted anyway |
| Manual loops, recursion | (see the sections above) | Varies | Quadratic | Never in production code |
The Order kept column describes what these methods do on .NET 10.0.10, which is more than their documentation promises. The Enumerable.Distinct documentation says the method “returns an unordered sequence that contains no duplicate values”, the DistinctBy() page uses the same words, and the HashSet<T> documentation describes a set whose elements are in no particular order. When we run them, Distinct(), DistinctBy(), the dictionary keys and RemoveAll() return the values in the order they first appear. A HashSet<T> does the same unless a value is removed and another added, because a later value can reuse the slot a removed one left.
Conclusion
We’ve learned several ways to remove duplicates from a list in C#, and we’ve explored the difference in their performance.
Tested with .NET 10.0.10, xunit 2.9.3 and BenchmarkDotNet 0.15.8.
Hi, is there a way to delete distinctby method?
I have more than 10,000 records in a table that records the status of some cases. Each update creates a record with the same case but different update.
With linq I first have to download the 10000 records and when it’s already an ienumerable list I can just use distinctby.
With morelinq, the discinctby is done before making the list, so I only download about 100 records. it is very easy, but with your method now it is very complicated.
Anyway, what I want to do is use morelinq and delete the lina method
Your benchmarks should also vary the number of elements in the list. What’s fastest for 8 elements is likely to not be fastest for 80,000 elements.
Thanks for the suggestion. We have the source code provided for this article, so anyone can download and play a bit with the values. We’ve just put some reference results in the article.